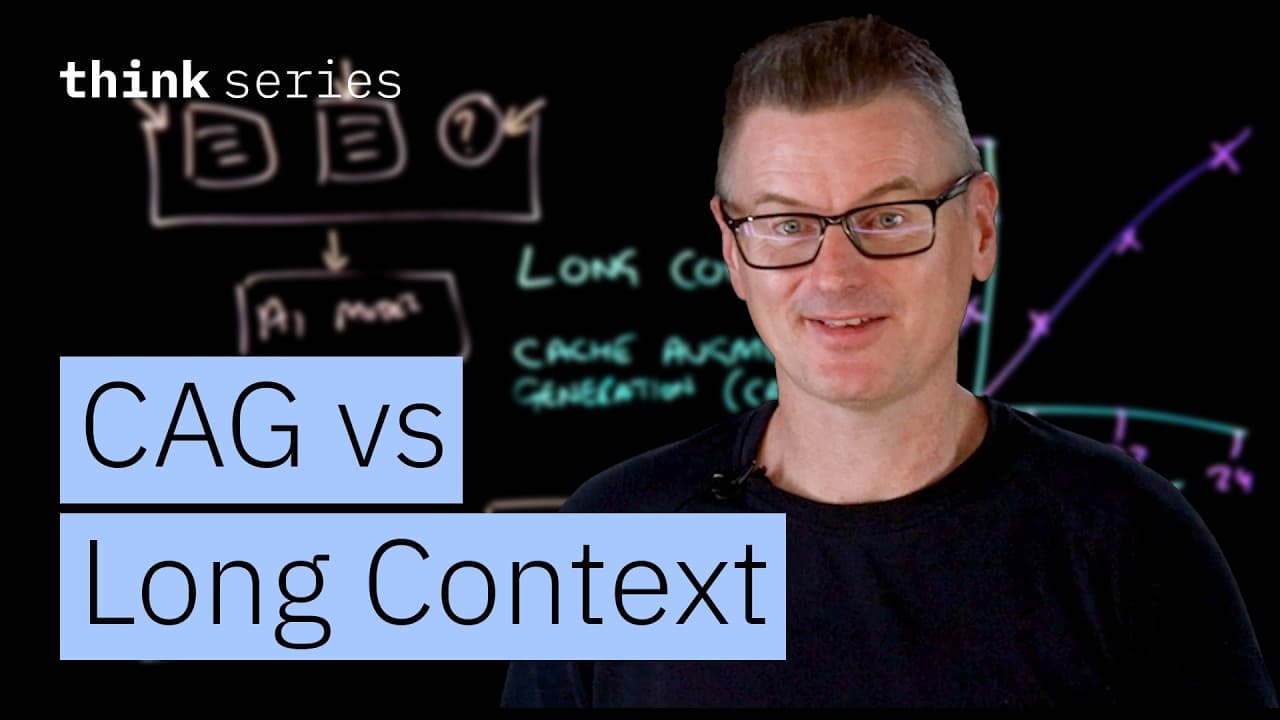
How to choose between long context and CAG in LLMs
TL;DR
Long context feeds all documents at inference time, while Cache Augmented Generation precomputes a KV cache to speed repeated queries. Use long context for a single, one-off analysis and CAG for multiple questions on a stable knowledge base. Prompt caching can further reduce processing costs.
Transcript
Long context and cache augmented generation are two ways to give a large language model access to external knowledge and they actually build on each other in a way that's worth understanding. So an LLM, a large-language model, it only knows what was in its training data. So if it needs to reason over some data that's in a private document or maybe ... Read More
Key Insights
- Long context requires reprocessing documents on every inference, increasing latency and cost.
- CAG uses a persistent KV cache created during a pre computation phase to accelerate subsequent queries.
- The KV cache stores how the model reads and understands documents as keys and values.
- Phase one of CAG is knowledge preparation where documents are formatted for the model window.
- Phase two of CAG is pre computation to generate and save the KV cache.
- Phase three of CAG is inference that appends a new question to the cached knowledge.
- Prompt caching as a service allows skip of document processing for many requests.
- Long context is best for one time analyses while CAG excels at repetitive queries on stable data
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is the core difference between long context and CAG?
Long context makes the model read and process all documents at inference time, meaning every query reprocesses the entire knowledge base and incurs higher latency and cost. CAG, by contrast, pre computes a KV cache once during a preparation phase, then re uses that cache for subsequent queries, making repeated queries faster and cheaper.
Q: When is long context most appropriate?
Long context is most appropriate when a workload involves analyzing a single document or a one off query where there is no repetition of same questions. In such cases there is no benefit to building and maintaining a cache, and keeping everything in the prompt is simpler and straightforward.
Q: What does KV cache stand for and why is it important?
KV cache stands for key value cache. It is important because it stores the internal representations of documents after the model has read them, allowing future queries to reuse these representations instead of reprocessing the full text. This results in faster responses and reduced computational load for repeated questions.
Q: What are the three phases of CAG?
The three phases of CAG are knowledge preparation, where relevant documents are gathered and formatted; pre computation, where the model processes documents to generate and save the KV cache; and inference, where a new query is appended to the cache and the answer is generated using the pre computed memory.
Q: How does prompt caching relate to CAG?
Prompt caching is a practical extension of CAG as a service that handles the KV cache management behind the scenes. It allows subsequent requests sharing the same prompt to skip document processing entirely, resulting in large token savings and easier integration for developers who want faster, cheaper responses.
Q: What limits does CAG have?
CAG is limited by the need for the entire knowledge base to fit within the model’s context window, and any changes to source documents require recomputing the KV cache. The approach is most beneficial when the data is stable and queries are repeated often, not for rapidly changing datasets.
Q: Why would someone prefer long context over CAG for a single workload?
Someone might prefer long context for a single workload because it avoids the overhead of building and maintaining a cache, and it guarantees that the model has access to all documents within the current prompt. It simplifies deployment and eliminates cache invalidation concerns when data changes infrequently.
Q: What is the potential performance advantage of CAG over long context?
The potential advantage of CAG is a large speedup on repeated queries, since the heavy document processing happens during pre computation and subsequent in ference simply loads the cached memory and appends the new question. This can yield significant latency reductions and cost savings for stable knowledge bases.
Summary & Key Takeaways
-
Long context loads and processes documents with every query, which can increase latency and cost but keeps setup simple. It enables the model to access everything in one prompt without managing separate storage or caches.
-
CAG pre computes a KV cache during a preprocessing phase, then loads it for future queries to speed up responses and reduce repeated computation. It suits repeated questions on a stable dataset.
-
Prompt caching can further optimize performance by reusing the same prompt and documents across requests, lowering token processing costs for subsequent queries
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator