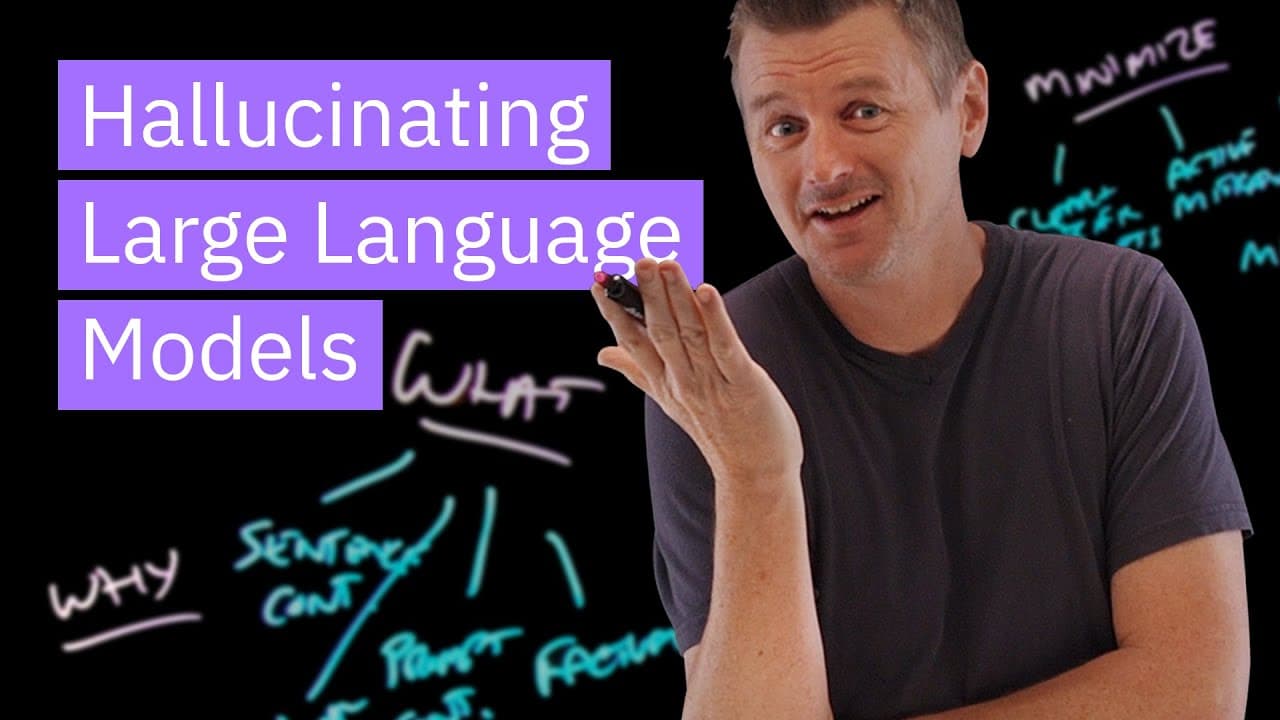
How Do LLMs Hallucinate and How Can We Reduce It
TL;DR
LLMs hallucinate when they generate plausible but incorrect statements due to data quality, training sources, generation methods, and unclear context. You can reduce hallucinations by giving clear, specific prompts, using settings to control output randomness, and employing multi shot prompting to guide the model toward desired results.
Transcript
I'm going to state three facts. Your challenge is to tell me how they're related; they're all space in aviation theme, but that's not it. So here we go! Number one-- the distance from the Earth to the Moon is 54 million kilometers. Number two-- before I worked at IBM, I worked at a major Australian airline. And number three-- the James Webb Telesco... Read More
Key Insights
- LLMs can produce contradictions or factual errors that violate the input prompt or stated facts, demonstrating the existence of hallucinations across multiple levels of granularity and highlighting the need for verification in outputs.
- The key causes of hallucinations include data quality issues in training data, which may contain biases or inaccuracies that the model generalizes from, underscoring the limits of current training corpora.
- Generation methods such as beam search or sampling introduce tradeoffs between fluency, diversity, and accuracy, which can bias outputs toward generic or fabricated content if not managed carefully.
- Input context plays a critical role; unclear or conflicting prompts can mislead the model, making precise and consistent instructions essential for reliable results.
- Effective mitigation includes crafting clear, specific prompts that constrain the model to the desired domain and output format, reducing stray or irrelevant information.
- Active mitigation can involve adjusting LLM settings like temperature to balance creativity and reliability, where lower temperature typically yields more conservative and focused responses.
- Multi shot prompting teaches the model through repeated examples, helping it infer the expected structure and content, and is especially useful for tasks requiring format consistency or specialized writing styles.
- The overarching strategy is to treat outputs as propositions to be verified, using prompts and configuration to guide the model toward factual and contextually appropriate results.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is an LLM hallucination and how does it manifest in outputs?
An LLM hallucination is an output that deviates from facts or contextual logic and can range from minor inconsistencies to completely fabricated statements. These can appear as factual errors, contradictions, or irrelevant information, and they arise from how the model learns from noisy data, the generation strategy used, and how the user frames the prompt. Identifying these patterns helps users keep outputs trustworthy and supports better prompt design to minimize falsehoods.
Q: What are the main causes of LLM hallucinations according to the video?
The video lists three main causes: data quality in training data, where sources may be biased or incorrect; generation methods, such as beam search or sampling, which create tradeoffs between fluency, diversity, and accuracy; and input context, where unclear or conflicting prompts misguide the model. Understanding these helps in choosing appropriate mitigation techniques like precise prompts and controlled settings.
Q: How does data quality influence hallucinations in LLMs?
Data quality influences hallucinations because training data may contain inaccuracies, biases, or noise that the model learns, and this information can be generalized to new queries. Even if data were fully reliable, coverage gaps can lead to hallucinations when the model encounters topics it has not seen sufficiently during training. This explains why some statements in outputs feel plausible yet are incorrect.
Q: What role does the generation method play in hallucinations?
Generation methods determine how the model constructs its outputs, with tradeoffs between probability, fluency, and originality. Techniques like beam search favor common, high probability words, which can reduce specificity and accuracy, while sampling can introduce more diverse but potentially erroneous content. Balancing these methods is crucial to reduce hallucinations.
Q: Why is input context important when using LLMs?
Input context guides what the model should produce, and lacking or conflicting context can lead to outputs that do not match the user’s intent. Supplying precise instructions about the desired domain, audience, and format helps the model stay on topic and reduces the chance of irrelevant or incorrect statements. Context also helps the model avoid inadvertently mixing unrelated topics.
Q: What practical steps can users take to reduce hallucinations?
Practical steps include writing clear, specific prompts that constrain the output to the target topic and format, using lower temperature settings to decrease randomness, and employing multi shot prompting with examples to prime the model toward the desired structure. These strategies help guide the model to produce more accurate and relevant results.
Q: How can multi shot prompting help reduce hallucinations?
Multi shot prompting reduces hallucinations by providing several examples of the exact output format and context the user expects. This primes the model to recognize patterns, structure, and terminology, making it more likely to generate consistent, correct outputs across similar tasks. It is particularly useful for coding, writing in a specific style, or producing standardized reports.
Q: Why is it important to verify LLM outputs in practice?
Verification is important because even with mitigation, LLMs can still produce plausible but incorrect information due to hidden biases, gaps in training data, or unexpected prompts. Treating outputs as provisional and cross checking facts against reliable sources ensures accuracy, especially for critical decisions, technical explanations, or evidence-based arguments.
Summary & Key Takeaways
-
Hallucinations in large language models are deviations from facts or logical context, ranging from simple contradictions to completely fabricated statements, and they can arise from training data quality, generation methods, and input prompts. Understanding these categories helps in diagnosing when outputs are unreliable and in selecting mitigation strategies. The video emphasizes concrete steps users can take to minimize such errors in practice.
-
Mitigation focuses on prompt precision, contextual clarity, and generation controls, explaining that lower temperature settings tend to reduce randomness while multi shot prompting provides examples of desired outputs. The aim is to align model behavior with user expectations through explicit instructions and repetition of the target format.
-
The overall message is that while LLMs are powerful and fluent, their tendency to hallucinate is manageable with careful prompting and configuration. This makes using LLMs more reliable for tasks that demand factual accuracy and contextual coherence, such as summaries, reports, and technical explanations.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator