What is reservoir computing and why it works?
TL;DR
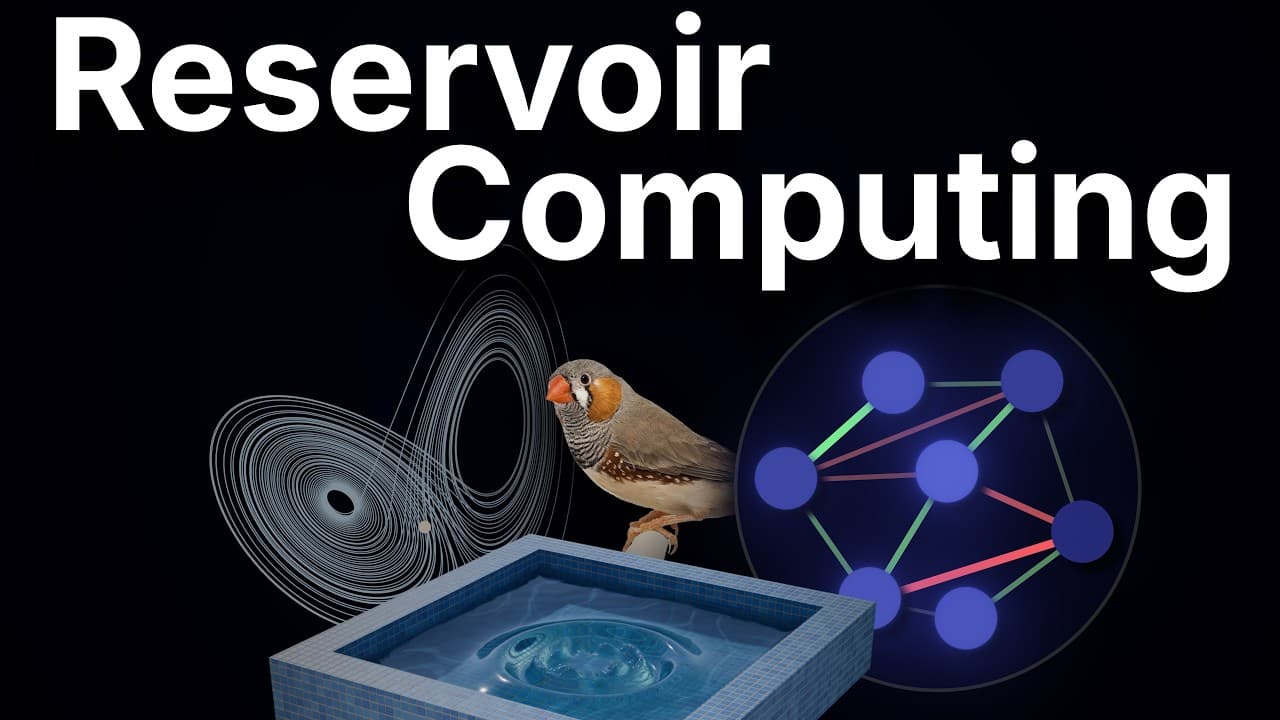
Reservoir computing uses a randomly connected neural pool and only trains a readout to match a target signal, avoiding complex weight optimization. The key idea is that a large random ensemble provides a rich temporal basis that can be linearly combined to reconstruct complex patterns, making learning simpler while preserving dynamic behavior.
Transcript
You know there is something miraculous happening in your brain right now. Close your eyes. I want you to think of the song We Will Rock You by Queen. Chances are you can hear it in your head. But here's the mystery. Where is it coming from? Your ear drums are not vibrating. The outside world is not pushing the song into your brain. You are generati... Read More
Key Insights
- Reservoir computing uses a fixed random reservoir to transform inputs into a rich set of temporal patterns.
- The readout layer is the only component trained, typically via a linear regression, to produce the target signal.
- The model leverages the echo state property where past inputs leave fading traces in the reservoir.
- A driving rhythmic signal can sustain activity in the reservoir, enabling longer sequences to be generated.
- The concept is tied to the idea that a diverse library of temporal shapes can approximate complex outputs.
- Fourier-like intuition underpins the method, where a collection of simple temporal components builds complex signals.
- The approach mirrors ancient ideas about building complex functions from simple basis functions like sine waves.
- Reservoirs can be understood as a random basis that, when read out linearly, reconstructs target dynamics.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is reservoir computing and how does it differ from traditional recurrent networks?
Reservoir computing is a framework where the internal connections of a fixed, randomly connected neural network (the reservoir) are left untouched, and only the readout weights are trained, typically by linear regression. This contrasts with traditional recurrent networks where every connection weight is adjusted during training. The reservoir generates a rich set of temporal patterns from inputs due to its intrinsic dynamics, and the readout linearly combines these patterns to match the target output. The key advantage is reduced training complexity while still capturing complex sequential behavior.
Q: Why is the echo state property important in reservoir computing?
The echo state property ensures that the influence of initial conditions fades over time, allowing the network to respond to current inputs rather than being dominated by arbitrary starting states. This fading memory makes the reservoir’s internal state primarily reflect recent inputs, which helps the readout learn a stable mapping to the desired output. In practice, this stability is crucial for reliably reconstructing target signals from the reservoir’s dynamic activity.
Q: How does a simple sine wave drive a reservoir to reproduce complex outputs?
A sine wave acts as a simple driving input that continuously perturbs the fixed reservoir. Because the reservoir contains many nonlinear units with random connections, the single sine wave is transformed into a rich, high-dimensional activity pattern. The readout then linearly combines these patterns to synthesize complex outputs, such as bird songs, by exploiting the diverse temporal features embedded in the reservoir’s response.
Q: What is the role of linear regression in reservoir computing?
Linear regression is used to compute the readout weights that map the reservoir’s activity to the desired target signal. This is the only training step required, turning a potentially intractable nonlinear optimization problem into a straightforward linear one. The efficiency and closed-form solutions associated with linear regression enable rapid training and easy comprehension of how different reservoir states contribute to the output.
Q: What analogy helps explain why random reservoirs can work well?
The analogy compares the reservoir to a library of random temporal shapes, where each neuron’s activity is a different, noisy waveform. With enough variety, any target signal can be approximated by a linear combination of these waveforms. This mirrors the idea that a function can be decomposed into sine waves or polynomial bases, allowing complex outputs to be built from simple components.
Q: How does the theory connect reservoir computing to historical Fourier ideas?
The idea that a complex signal can be reconstructed from a collection of simple sine and cosine components echoes Fourier analysis. In reservoir computing, the random reservoir provides a broad mix of temporal components, and the readout learns how to weight them to reproduce the target signal, analogous to summing basis functions to form any desired waveform.
Q: What problem does reservoir computing solve compared to deep recurrent nets?
Reservoir computing addresses the difficulty of training highly intricate dynamical systems by fixing the reservoir and only training the readout. This reduces training instability and computational cost while still enabling the network to produce complex temporal patterns. It offers a practical alternative when full backpropagation through time is expensive or unstable.
Q: Can reservoir computing scale to large, real-world tasks?
Yes, in principle, because the core training is linear and scales well. By using larger reservoirs with richer dynamics and combining multiple readouts or regularization techniques, practitioners can adapt reservoir computing to more demanding sequence prediction, time-series modeling, or control tasks, though careful design is still required to maintain the echo state property and manage resources.
Summary & Key Takeaways
-
Reservoir computing deploys a fixed random network, or reservoir, to generate diverse temporal patterns from input signals and relies on a trainable readout to produce the desired output.
-
The central idea is that the reservoir acts as a basis of temporal features, enabling simple linear regression to map activity to targets.
-
This approach contrasts with full weight optimization in traditional recurrent networks, reducing training complexity while maintaining dynamic expressiveness.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Artem Kirsanov 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator