Large Language Models Explained Briefly: How Do They Work?
TL;DR
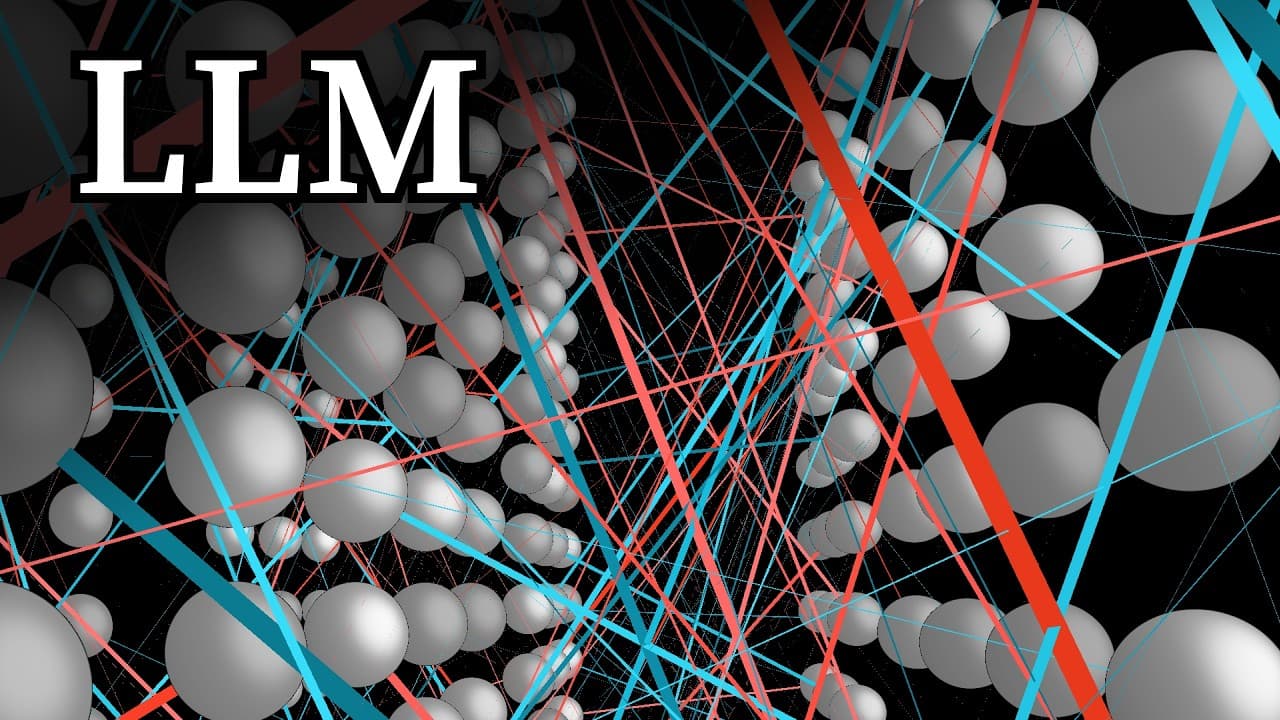
The “Large Language Models explained briefly” transcript explains that these models assign probabilities to possible next words, then repeatedly select words to generate responses. They learn by refining hundreds of billions of parameters across many trillions of examples, while transformers use attention to process context in parallel. Read on to understand pre-training, backpropagation, GPUs, and reinforcement learning with human feedback.
Transcript
Imagine you happen across a short movie script that describes a scene between a person and their AI assistant. The script has what the person asks the AI, but the AI's response has been torn off. Suppose you also have this powerful magical machine that can take any text and provide a sensible prediction of what word comes next. You could then finis... Read More
Key Insights
- Large language models predict the next word by assigning probabilities to all possible next words.
- Training involves processing massive amounts of text, requiring significant computational power.
- Parameters, or weights, determine model behavior and are refined through training.
- Transformers process text in parallel using attention mechanisms, enhancing efficiency.
- Backpropagation is used to adjust parameters, improving prediction accuracy.
- Reinforcement learning with human feedback refines models for better user interaction.
- Specialized computer chips, like GPUs, enable the massive computations required for training.
- The transformer model introduced in 2017 revolutionized language processing with parallel text processing.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What does the “Large Language Models explained briefly” transcript explain?
It explains that a large language model is a sophisticated mathematical function that assigns probabilities to all possible next words. A chatbot repeatedly uses these predictions to build a response to the user.
Q: How do large language models generate chatbot responses?
A chatbot combines text describing a user and an AI assistant with the text entered by the user. The model then repeatedly predicts the next word that the hypothetical assistant would say, and the resulting sequence is presented as the response.
Q: Why can the same prompt produce different answers?
The model assigns probabilities rather than choosing one word with certainty. Allowing it to randomly select less likely words can make its output more natural, so the same prompt typically produces a different answer each time even though the model itself is deterministic.
Q: How are large language models trained?
Their parameters begin at random and are repeatedly refined using example passages of text. The model receives all but the final word of an example, predicts the missing word, and compares that prediction with the true final word.
Q: What does backpropagation do during training?
Backpropagation tweaks the model’s parameters after its prediction is compared with the true last word of a training example. It makes the model slightly more likely to select the correct word and less likely to select the alternatives.
Q: Why does training large language models require GPUs?
Training involves an enormous amount of computation across huge quantities of data and parameters. GPUs make this possible because they are special computer chips optimized to run many operations in parallel.
Q: What is reinforcement learning with human feedback?
It is additional training that helps turn a pre-trained text completion model into a better AI assistant. Workers flag unhelpful or problematic predictions, and their corrections change the parameters so the model becomes more likely to produce responses users prefer.
Q: How do transformers use attention to process text?
Transformers process text all at once in parallel instead of reading it one word at a time. Attention lets the numerical representations of words influence one another and refine their meanings based on context, such as distinguishing a riverbank from another meaning of bank.
Summary & Key Takeaways
-
Large language models function by predicting the next word in a sequence, assigning probabilities to potential words. They are trained on vast text datasets, and their parameters are refined using algorithms like backpropagation to improve accuracy. Transformers, a type of model, use attention mechanisms to process text efficiently in parallel.
-
Training large language models involves enormous computational power, often requiring specialized computer chips like GPUs. The models learn from trillions of examples, enabling them to make accurate predictions even on unseen text. Reinforcement learning with human feedback further refines their predictions for better user interactions.
-
Transformers revolutionized language processing in 2017 by allowing parallel processing of text using attention mechanisms. This method enhances the model's ability to understand and predict language, making them highly efficient and effective in generating fluent and useful text outputs.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from 3Blue1Brown 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator