How Do Loss Functions Help AI Models Learn?
TL;DR
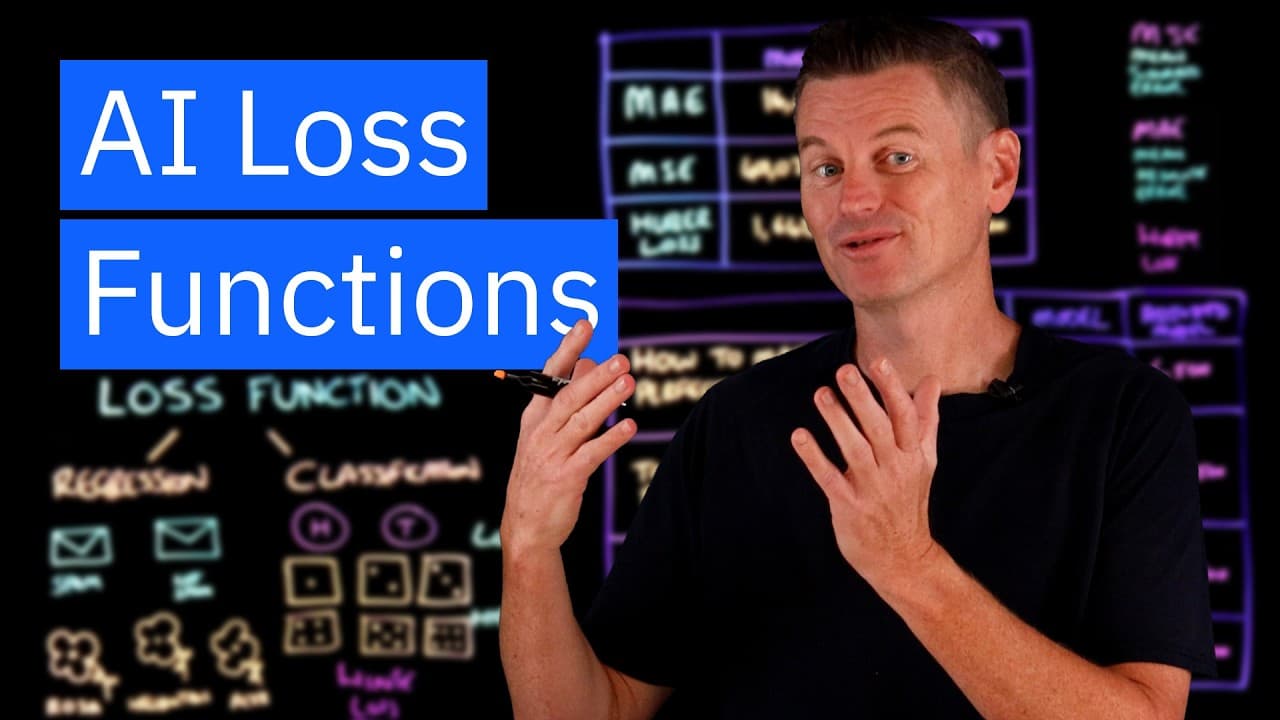
A loss function quantifies the difference between a model’s prediction and the ground truth, providing the feedback needed to improve predictions. Regression tasks can use MSE, MAE, or Huber loss, while classification tasks can use cross-entropy or hinge loss. Optimization methods such as gradient descent then update model weights and biases to reduce loss.
Transcript
How good is an AI model at forecasting? We can put an actual number on it. In machine learning a loss function tracks the degree of error in the output from an AI model, and it does this by quantifying the difference or the loss between a predicted value. So let's say that that is five, the model gave us five, as the output and then comparing that... Read More
Key Insights
- A loss function is a numerical measure of the difference between an AI model’s prediction and the corresponding ground truth. Accurate predictions create comparatively small loss values, while inaccurate predictions create larger values that indicate the model requires further adjustment.
- Loss minimization is a central objective of model training because it provides a mathematical way to evaluate parameter changes. A model can be considered sufficiently trained when its loss has been minimized below a predefined threshold established for the task.
- Regression loss functions are designed for continuous numerical targets, including house prices, daily temperatures, and expected YouTube views. They must reflect both whether a prediction is incorrect and the degree to which it differs from the actual target value.
- Mean squared error is the average squared difference between predicted and true values across all training examples. Squaring each error gives especially large mistakes a disproportionate effect on total loss, making MSE useful when severely inaccurate predictions should receive strong penalties.
- Mean absolute error is the average absolute difference between predicted and true values. Because it does not square errors, MAE is less sensitive to extreme outliers and can be preferable when occasional unusual observations should not exert excessive influence on the model.
- Huber loss is a compromise between MSE and MAE because it behaves like MSE for small errors and like MAE for large errors. It penalizes substantial mistakes while preventing them from affecting the result as severely as they would under MSE.
- Cross-entropy loss is a widely used classification loss function that compares uncertainty in a model’s predicted categories with the certainty of ground-truth labels. Higher disagreement between predicted certainty and the actual outcome produces a larger classification loss.
- Gradient descent reduces loss by calculating the slope of the loss function with respect to each model parameter. An optimization algorithm uses that gradient to select a downward direction, then updates weight and bias terms until the loss has been sufficiently minimized.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is a loss function in machine learning?
A loss function is a mathematical measure of how far an AI model’s output differs from the actual value or ground truth. A comparatively accurate prediction produces a small loss, while an inaccurate prediction produces a larger loss. This number allows model developers to compare different forecasts, evaluate parameter adjustments, and determine whether training is moving the model toward better predictions.
Q: How does a loss function help an AI model learn?
A loss function helps an AI model learn by acting as a feedback mechanism. It indicates how far predictions are from actual results and makes the effect of parameter changes measurable. If an adjustment lowers loss, performance has improved. If it raises loss, performance has worsened. Optimization algorithms can use this feedback to update weights and biases until loss reaches a sufficiently low level.
Q: What is the difference between regression and classification loss?
Regression loss measures error in predictions involving continuous numerical values, such as a house price, a temperature, or the number of YouTube views. Classification loss evaluates categorical predictions, such as whether an email is spam or whether a plant belongs to the correct species. In classification, the loss reflects how well predicted probabilities or labels match the actual categories.
Q: When should mean squared error be used?
Mean squared error is useful when the ground-truth data contains relatively few extreme outliers and predictions far from the correct value should be penalized heavily. It averages the squared differences between predictions and true values, so large mistakes have a disproportionate influence on the result. The transcript uses relatively stable July temperature ranges in the southern United States as an example of suitable data.
Q: When should mean absolute error be used?
Mean absolute error is a better option when the data contains more outliers and those unusual values should not dominate the model’s learning signal. It calculates the average absolute difference between predicted and true values without squaring errors. Product-demand forecasting is one example because occasional sales surges may be real but should not excessively skew the model’s overall behavior.
Q: How does Huber loss combine MSE and MAE?
Huber loss combines characteristics of mean squared error and mean absolute error. It behaves like MSE when errors are small and like MAE when errors are large. This provides a balanced approach when large errors should receive meaningful penalties but should not affect the result as severely as they would when every error is squared under MSE.
Q: How do cross-entropy loss and hinge loss differ?
Cross-entropy loss measures how uncertain a model’s categorical predictions are relative to the certain ground-truth labels. Hinge loss instead encourages the model to make correct predictions with a specified level of confidence by maximizing the margin between classes. Hinge loss is particularly useful for binary classification when the two classes should be separated as clearly and confidently as possible.
Q: How does gradient descent minimize a loss function?
Gradient descent minimizes loss by calculating the gradient, or slope, of the loss function with respect to each model parameter. An optimization algorithm uses this gradient to determine which direction will move downward and reduce loss. The model repeatedly updates its weight and bias terms in that direction until the loss function has been sufficiently minimized according to the training objective.
Summary & Key Takeaways
-
A loss function assigns a numerical value to prediction error by comparing a model’s output with the ground truth. Small differences produce lower loss, while inaccurate predictions produce higher loss. This makes loss both a performance score and a practical feedback signal for deciding whether parameter changes improve or worsen a model.
-
Regression loss functions evaluate predictions involving continuous values, such as house prices, temperatures, or YouTube views. MSE strongly penalizes large errors by squaring them, while MAE averages absolute errors and is less sensitive to outliers. Huber loss combines both approaches, using MSE behavior for small errors and MAE behavior for large ones.
-
Classification loss functions evaluate categorical predictions, such as whether an email is spam or which species a plant belongs to. Cross-entropy compares the certainty of predicted categories with certain ground-truth labels. Hinge loss encourages correct, confident predictions with separation between classes. Optimization can then reduce loss by updating model weights and biases.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator