How to Upgrade Hermes Agent With Four Features
TL;DR
Configure Hermes with a fixed Ministry of Experts panel, using one orchestrator to combine parallel answers from several reference models, while caching keeps repeated context costs lower. The update also adds computer control, a /learn command for turning conversations into reusable skills, voice chat, and supporting features such as background agents, iMessage, and a desktop app.
Transcript
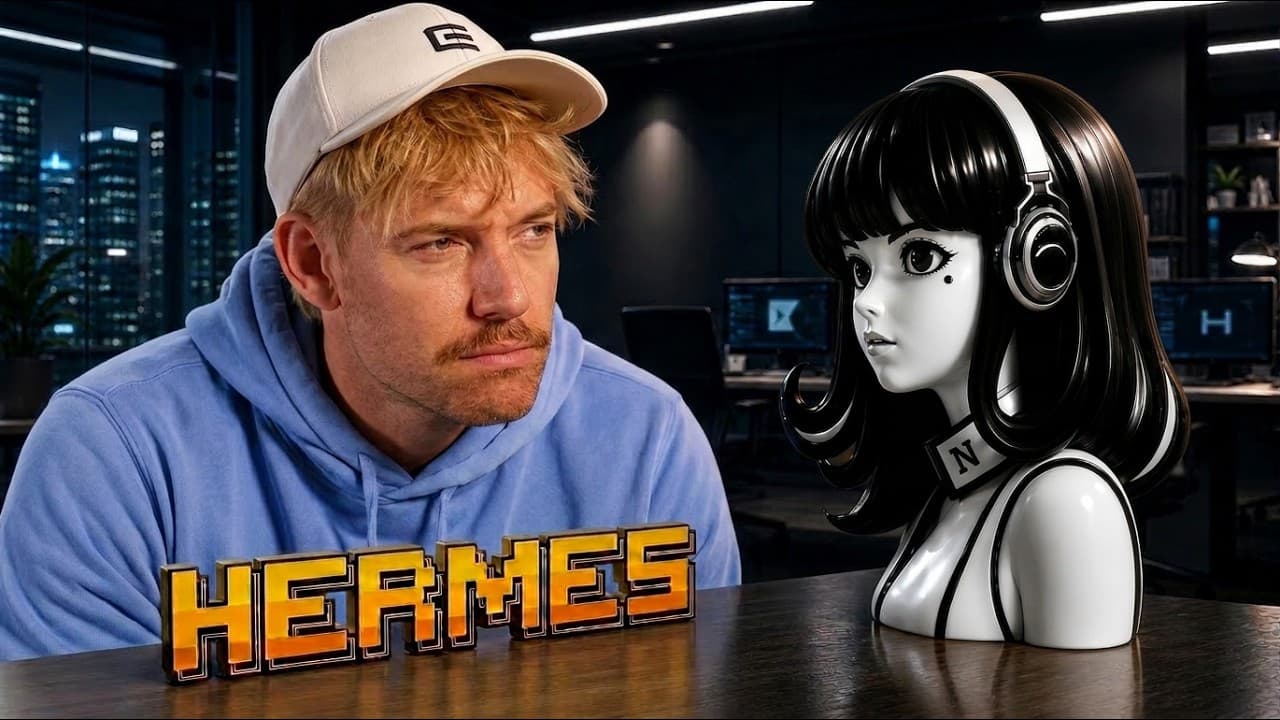
Homie's agent just released its biggest update so far and it's going to improve the performance of your agent whilst also costing less and make it more accurate. And in this video, I'm going to cover the big four updates that you need to know about right now so you don't fall behind and you can take your Hermes agent to a completely new level. And ... Read More
Key Insights
- The Ministry of Experts is a fixed committee of models that answers each request in parallel before an orchestrator synthesizes the final response and runs the tool. It is designed to improve answer quality by exposing the orchestrator to several independent approaches and potential corrections.
- Different models make different mistakes, so combining their proposals can reveal blind spots that a single model might miss. The orchestrator receives each proposal as private context, evaluates the contributions, and produces a synthesized answer rather than simply selecting one model's response.
- Hermes caching works by reading the shared context once and reusing it, preventing each participating model from repeatedly processing the entire context. According to the presentation, this makes the built-in committee less expensive than manually spawning separate agents that each reread everything.
- Hermes Bench is News' stated benchmark for evaluating the system, and the presentation reports a claim of performance 8% above Opus 4.8. The claim is presented as plausible because Opus 4.8 can orchestrate several additional models that help identify errors and missing considerations.
- The demonstrated panel uses Opus 4.8 as the orchestrator and DeepSeek V4 Pro, GLM 5.2, and ChatGPT 5.5 as reference models. The interface also displays model information such as speed, cost, agent capability, and Arena rankings to support manual selection.
- OpenRouter provides one connection to the models used in the demonstrated setup, while a ChatGPT subscription is recommended for access to GPT 5.5 coding usage. The presenter cites a $20 monthly subscription and uses that access to make the multi-model configuration more cost-effective.
- The Ministry of Experts is a committee rather than a router because it runs the same user-configured panel on every turn. It does not inspect each task and automatically choose a specialist, and its reference models cannot create their own subagents during this process.
- Hermes computer control is intended for software that lacks an API or MCP, allowing the agent to perform actions through the computer interface. Other highlighted additions include the /learn command for reusable skills, voice chat, enterprise compliance, iMessage, background agents, and a desktop app.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How does the Hermes Ministry of Experts work?
The Ministry of Experts sends the same question to a fixed group of reference models in parallel. Their proposed answers are appended to the orchestrator's private context, and the orchestrating model synthesizes the final response and runs the relevant tool. This arrangement resembles a team in which every selected model contributes a perspective, helping the orchestrator notice blind spots or mistakes.
Q: Why can multiple models improve a Hermes answer?
Multiple models can improve an answer because different models may make different mistakes or emphasize different details. Hermes lets several reference models independently attempt the same request, then gives all of their proposals to an orchestrator. The orchestrator can compare those perspectives, use their strongest contributions, identify inconsistencies, and write a more complete final answer than one model might produce alone.
Q: How does caching reduce Ministry of Experts costs?
Caching reduces costs by letting Hermes read the full shared context once and reuse it across the panel. Without that mechanism, independently spawned agents would each need to reread the entire context, increasing token usage and expense. The presentation says Hermes keeps the cache intact during the committee process, making its built-in approach cheaper than manually running several separate agents.
Q: Which models are used in the demonstrated Hermes panel?
The demonstrated configuration places Opus 4.8 in the orchestrator role and uses DeepSeek V4 Pro, GLM 5.2, and ChatGPT 5.5 as reference models. The presenter favors the combination because it brings together several model perspectives while including lower-cost options. Hermes also allows these selections to be moved or replaced as the available model list changes.
Q: What accounts are recommended for the multi-model setup?
The presenter recommends supplying Hermes with an OpenRouter API key because OpenRouter can connect the agent to multiple models through one connection. A ChatGPT subscription is also recommended for GPT 5.5 coding usage. The subscription price cited in the presentation is $20 per month, and the presenter uses that access to reduce the effective cost of the panel.
Q: Can Hermes automatically route each task to a different expert?
The described Ministry of Experts does not automatically inspect a task and choose a particular specialist. It runs the same fixed panel configured by the user on every turn, collects every model's response, and fuses the proposals through the orchestrator. The presenter therefore distinguishes it from a router and describes it as a committee optimized for quality and protection against model blind spots.
Q: How can users control the length of expert responses?
Users can adjust the token allowance for the Ministry of Experts, with the demonstrated range running from about 4,000 to 16K tokens. A smaller allowance is recommended when the desired response should be succinct and direct, while a larger allowance supports more extensive work. In the live test, the presenter requests a 4,000-token limit for an explanation of Hermes memory.
Q: What other features are included in the Hermes update?
The update also includes computer control for working with software that does not provide an API or MCP. The /learn command can turn a conversation into a reusable skill, and voice chat enables spoken interaction with Hermes. The description additionally identifies enterprise compliance, iMessage, background agents, and a new desktop app among the features covered in the update.
Summary & Key Takeaways
-
The Ministry of Experts sends the same prompt to several reference models in parallel, then gives their proposals to an orchestrating model that writes the final response and runs the tool. This committee approach is intended to catch blind spots because different models may make different mistakes when answering the same question.
-
Hermes reduces the cost of this multi-model process by reading the full context once and reusing it through caching. The demonstrated configuration uses Opus 4.8 as orchestrator, with DeepSeek V4 Pro, GLM 5.2, and ChatGPT 5.5 as reference models. Users can manually replace models as available options change.
-
Other additions broaden how users can operate and extend Hermes. Computer control covers tasks in software without an API or MCP, the /learn command can convert a conversation into a reusable skill, and voice chat enables spoken interaction. Additional updates include compliance support, iMessage, background agents, and a new desktop app.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Jack Roberts 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator