How to choose between sparse, dense, and hybrid retrieval?
TL;DR
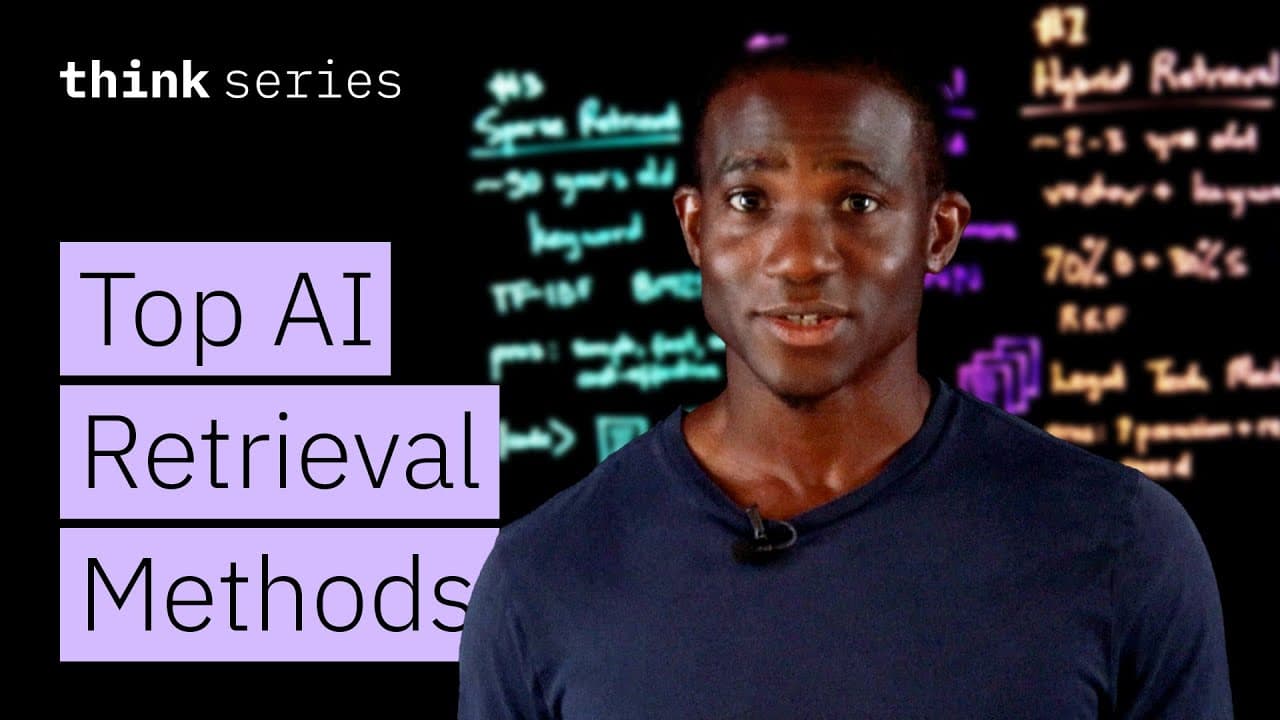
Hybrid retrieval is the top choice because it combines the strengths of both keyword search and vector similarity, delivering higher precision and recall. Sparse retrieval is fast and exact for short queries, while dense retrieval excels at semantic understanding and context, making it complementary. Overall, hybrid retrieval provides the best balance for serious RAG deployments.
Transcript
I've heard about five different variations of my first name Joseph, Joe, Joseph with an F, Jose from Mis Amigos en Guadalajara, and then, there's that one guy in grad school who called me Joseppi. Meanwhile, I don't think I've ever had anything similar with my last name, just Washington. The retrieval in retrieval augmented generation or RAG is kin... Read More
Key Insights
- Sparse retrieval is a foundational method using keyword based scoring like BM25 and TF-IDF. It is simple, fast, scalable, and cost effective, and it requires no embeddings.
- Dense retrieval maps queries and documents into high dimensional vectors and uses semantic similarity for ranking, enabling natural language queries but can miss rare terms and short phrases.
- Hybrid retrieval combines vector and keyword search in parallel and fuses results, balancing speed, precision and recall to outperform dense or sparse alone.
- BM25 and TF-IDF are prominent sparse methods and are compatible with Elasticsearch, Apache Lucene, and even Milvus for some implementations.
- Dense retrieval relies on embedding models such as sentence transformers to produce vector representations that capture meaning beyond exact word matches.
- Hybrid retrieval uses fusion methods like weighted sums or reciprocal ranked fusion to merge results from both retrievers effectively.
- Hybrid retrieval is currently the state of the art due to its ability to handle synonyms and critical terms without sacrificing speed.
- Choice of retrieval strategy should consider the domain, jargon, and need for exact terms versus flexible meaning.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: A real search query question about the video (e.g. 'How to...', 'What is...', 'Why does...', 'When should...'). Question 1
Sparse retrieval is a keyword based method that scores documents by how often query terms appear, using techniques like BM25 or TF IDF. It is fast, scalable, and does not require embeddings, making it cost effective for exact wording, short queries, code searches, logs, and legal clauses. It is best when exact wording matters and domain terms are relatively stable.
Q: Question 2
Dense retrieval maps both queries and documents into high dimensional vector space so similarity is based on meaning rather than exact word matches. It relies on embedding models to capture semantic relationships, enabling natural language queries and flexible phrasing. It shines in chatbots and unstructured knowledge bases but may miss rare terms or jargon.
Q: Question 3
Hybrid retrieval combines vector based and keyword based approaches by running both in parallel and then fusing results. The fusion often uses a weighted sum or reciprocal ranked fusion to merge scores from each retriever. This yields better precision and recall across diverse domains, including specialized jargon, by leveraging strengths of both methods.
Q: Question 4
Why is hybrid retrieval considered the current best practice for RAG deployments? Because it balances speed from sparse methods with the context sensitivity of dense methods, providing robust results. Benchmarks show it consistently outperforms dense only retrieval, particularly in domains with jargon and technical terminology, and it is supported by major platforms.
Q: Question 5
What are the drawbacks of sparse retrieval and when should you avoid it? Sparse retrieval may miss context and synonyms because it focuses on exact term matches. It struggles with natural language queries and terms beyond the exact wording. It is less effective for unstructured data but remains valuable when precise terms are critical and queries are short.
Q: Question 6
What limitations does dense retrieval have and how can hybrid help? Dense retrieval can miss rare or domain specific terms and can struggle with very short queries. Hybrid retrieval mitigates this by adding keyword search to catch rare terms and ensure important phrases are not overlooked, improving accuracy across varied inputs.
Q: Question 7
How do fusion strategies like weighted sums and reciprocal ranked fusion work in hybrid retrieval? Weighted sums assign relative importance to each retriever and combine scores to rank results, while reciprocal ranked fusion uses the positions from each retriever instead of raw scores. Both methods aim to merge strengths and reduce weaknesses.
Q: Question 8
What practical guidance does the video offer for implementing retrieval in a real system? Start with sparse retrieval for fast baseline results and simple deployment, add dense retrieval for semantic understanding, and move to hybrid as the default approach to achieve strong precision and recall across complex knowledge bases and domains.
Summary & Key Takeaways
-
Hybrid retrieval blends vector and keyword search to optimize precision and recall across use cases, making it the default in many RAG deployments.
-
Sparse retrieval remains fast and exact for short, well defined queries where exact wording matters, such as code or legal clauses.
-
Dense retrieval adds context awareness and semantic matching, but can miss rare terms and struggles with very short queries in some scenarios.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator