How to Use Obsidian for Knowledge Management
TL;DR
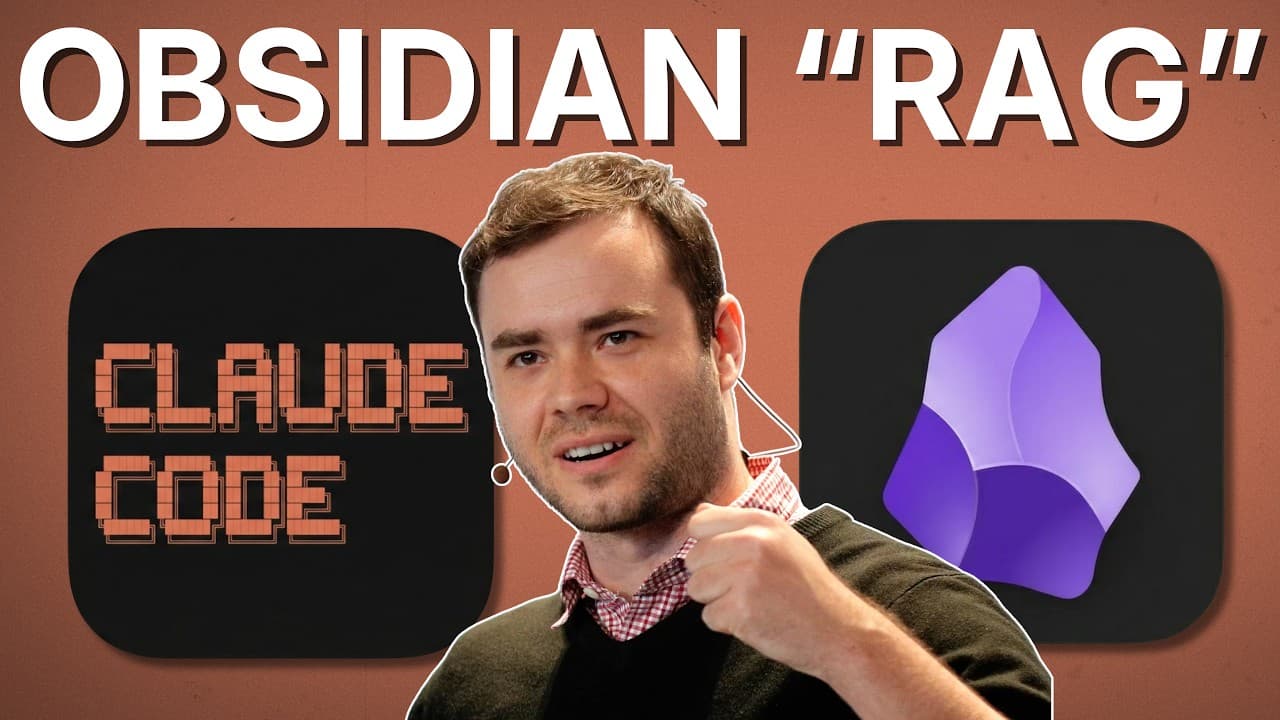
Andre Karpathy's Obsidian-based system offers a lightweight alternative to traditional RAG systems, enabling users to manage large language model knowledge bases without complex setups. This method involves organizing data within Obsidian using a simple file structure, allowing efficient data ingestion and retrieval without the need for vector databases or embeddings.
Transcript
Andre Carpathy just gave us the keys to his personal Obsidian Rag system. And I put Rag in air quotes because this Obsidian power knowledge base has no vector database, no embeddings, and no complicated retrieval process. Yet, it solves the exact same problem that these more complicated rag structures claim to do, which is allow our large language ... Read More
Key Insights
- Obsidian can function as a lightweight alternative to traditional RAG systems.
- The system does not require vector databases or embeddings for data retrieval.
- Data is organized in Obsidian using a simple file structure with raw and wiki folders.
- Cloud Code can automate the creation of wikis from raw data stored in Obsidian.
- The Obsidian Web Clipper extension helps convert web pages into markdown files.
- Community plugins in Obsidian enhance functionality, such as handling images.
- Obsidian is suitable for solo operators or small teams with moderate data needs.
- Scaling to millions of documents may require transitioning to a traditional RAG system.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How does Obsidian manage data without a RAG system?
Obsidian manages data by using a simple file structure where data is ingested into a 'raw' folder and organized into 'wiki' folders. This setup allows users to manually or automatically create wikis using Cloud Code, facilitating efficient data retrieval without the need for vector databases or complex retrieval processes.
Q: What are the benefits of using Obsidian over traditional RAG systems?
Obsidian offers a lightweight, cost-effective alternative to traditional RAG systems, making it ideal for solo operators or small teams. It simplifies data management by using a straightforward file structure and does not require complex setups like vector databases, making it easier to manage moderate amounts of data efficiently.
Q: How does the Obsidian Web Clipper extension work?
The Obsidian Web Clipper extension converts web pages into markdown files, which are then automatically stored in the designated 'raw' folder within Obsidian. This tool simplifies data ingestion by allowing users to easily capture and organize information from the internet directly into their Obsidian knowledge base.
Q: What role do community plugins play in Obsidian?
Community plugins in Obsidian enhance its functionality by adding features that address specific needs, such as handling images within markdown files. These plugins expand Obsidian's capabilities, allowing users to customize their knowledge management system to better suit their data handling and retrieval requirements.
Q: When should a user consider transitioning to a traditional RAG system?
A user should consider transitioning to a traditional RAG system when their data needs scale to the point where managing millions of documents becomes necessary. Traditional RAG systems offer more robust solutions for handling large-scale data efficiently, which may not be feasible with the lightweight Obsidian setup.
Q: How does Cloud Code integrate with Obsidian?
Cloud Code integrates with Obsidian by automating the creation of wikis from the raw data stored in the Obsidian vault. It can conduct research, gather relevant information, and generate structured wikis, facilitating efficient data retrieval and management within the Obsidian knowledge base.
Q: What is the setup process for creating an Obsidian knowledge base?
To set up an Obsidian knowledge base, users need to download Obsidian, designate a folder as the 'vault,' and create a file structure with 'raw' and 'wiki' folders. Users can then use the Obsidian Web Clipper and community plugins to ingest data and organize it into wikis using Cloud Code for efficient management and retrieval.
Q: How does Obsidian facilitate efficient data retrieval?
Obsidian facilitates efficient data retrieval by organizing information into a clear file structure with master index markdown files and wiki links. This setup allows both users and Cloud Code to easily navigate and access relevant data, minimizing the need for extensive tool calls and simplifying the process of finding specific information.
Summary & Key Takeaways
-
Andre Karpathy's Obsidian system offers a streamlined approach to managing large language model knowledge bases without the complexity of traditional RAG systems. By using a simple file structure within Obsidian, users can efficiently ingest and retrieve data. This setup is ideal for solo operators or small teams not dealing with massive amounts of documents.
-
Obsidian's system involves organizing data in a 'vault' with raw and wiki folders, enabling users to manually or automatically create wikis using Cloud Code. The Obsidian Web Clipper extension and community plugins enhance data ingestion and management, making this approach accessible and effective for many users.
-
While traditional RAG systems are beneficial for handling large-scale data, Obsidian provides a cost-effective solution for those with moderate data needs. This method allows users to experiment and scale their knowledge management processes, transitioning to more complex systems only if necessary.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Chase AI 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator