How to Ship AI Agents Faster with Simulations
TL;DR
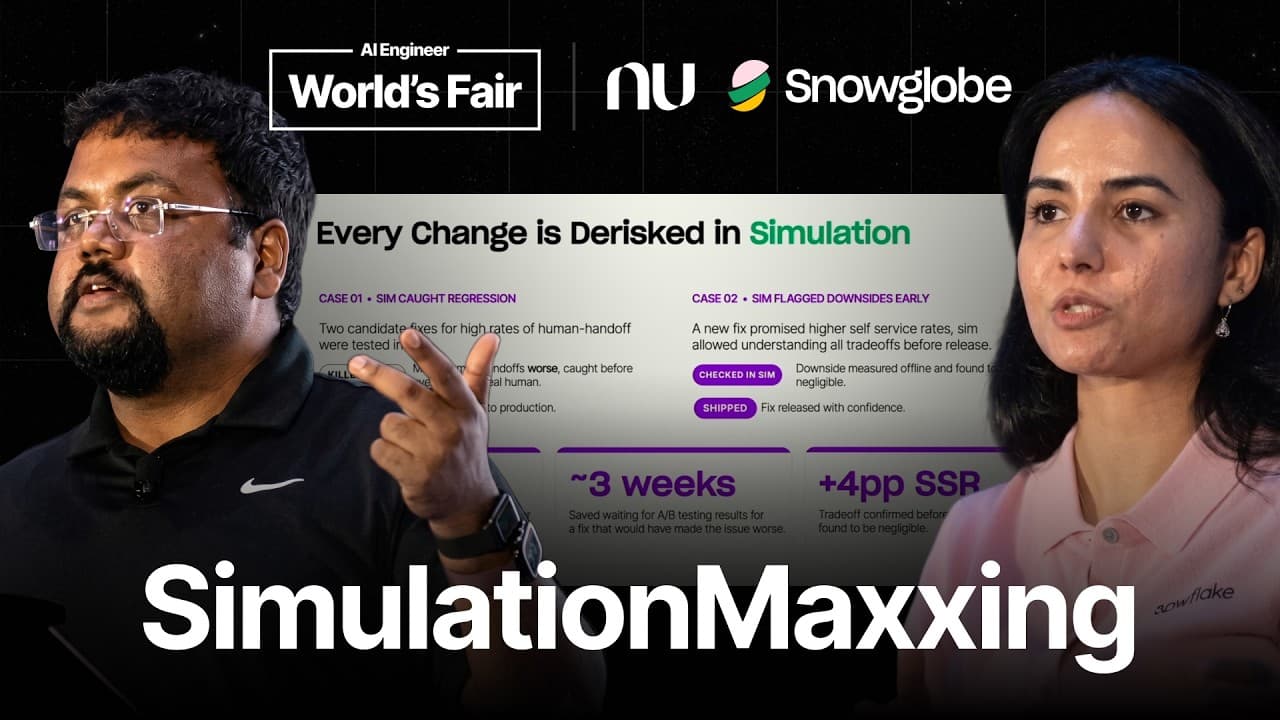
Generate agent evaluation data through grounded simulations instead of waiting for hand-authored examples or production feedback. Nubank reports that this approach shortened release cycles from weeks to hours in some cases, while helping five production agents improve customer satisfaction toward or beyond human quality. Human reviewers considered simulated and real conversations comparable about 80% of the time.
Transcript
[music] Hi everybody, my name is Shrea. I am the CEO of Snow Globe and we have with us Ammon who is a principal machine learning engineer at new. And this talk is going to be about simulation maxing and how you can ship or how new bank ships uh agents 20x faster using simulations. Hey everyone, I'm Aman. Uh so let me talk about New Bank at a glance... Read More
Key Insights
- Agent evaluation depends on both metrics and data, but data is often the larger bottleneck. Metrics can be aligned with human judgment through language-model judges, classifiers, human labels, automated optimization, and prompt tuning, while representative multi-turn evaluation examples remain expensive to obtain.
- Multi-turn agent data is a stateful trajectory rather than a simple question-and-answer row. Each example may contain internal tool calls, account state, intermediate decisions, and conversational history, all of which must remain consistent for the evaluation to represent realistic agent behavior.
- Manual evaluation authoring is slow because people must plan synthetic state, user behavior, expected trajectories, and tool responses. Production traces are nearly free to collect, but relying on them means testing changes with live users and waiting for sparse, noisy feedback.
- Simulation reduces the feedback cycle by providing an artificial user whenever offline evaluation data is needed. Nubank reports that work which previously required weeks of production testing can sometimes be evaluated in less than a day, with certain checks completing within hours or minutes.
- A grounded simulation combines a persona, use case, intent, communication style, and consistent contextual data. The example customer includes a synthetic identity, address, credit card information, and account context, allowing the real agent to call mocked tools and receive coherent responses.
- Snowglobe works by connecting its SDK to an agent, identifying the tools that need to be mocked, and defining how simulations should be steered. It then produces thousands of multi-turn conversations and applies judges that report how the agent behaves at each turn.
- Simulated conversations were judged comparable to real conversations about 80% of the time. The description presents that level of realism as sufficient for bringing up new agents, reducing the risk of changes, and protecting the rate at which customers successfully use self-service support.
- Nubank's improvement loop combines production observation, robust evaluations, simulation, real data, and agent optimization. Both simulated and production interactions pass through aligned evaluators, creating detailed signals that guide harness changes before a revised agent is released to customers.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How can simulations help teams ship AI agents faster?
Simulations generate evaluation conversations on demand, so teams do not need to wait for people to hand-author complex examples or for enough production feedback to accumulate. The simulated users interact with the real agent through grounded, multi-turn scenarios and mocked tools. Nubank reports that this can shorten a release cycle from weeks to less than a day, with some evaluations taking only hours or minutes.
Q: Why is evaluation data a bottleneck for AI agents?
Agent evaluation data is difficult because one example is an entire trajectory rather than a single prompt and response. It can include multiple conversational turns, internal tool calls, changing account state, and dependencies between earlier and later actions. Creating and annotating these trajectories manually requires careful planning, while collecting them in production delays experimentation and places real users in the testing loop.
Q: What information does a simulated customer persona contain?
A simulated persona can include a synthetic identity, age, occupation, customer status, intent, tone, communication style, and grounding information needed by the agent. In the example, Maria Souza is a 34-year-old designer ordering her first credit card. Her fake address, credit card details, and account context remain consistent while the agent converses with her and calls mocked tools.
Q: How does Snowglobe generate agent evaluation data?
Snowglobe connects its SDK to an existing agent without requiring code changes, then identifies which tools must be mocked for realistic execution. Teams specify the personas, use cases, and data points that should steer the simulations. The system runs those scenarios against the real agent, creates thousands of grounded multi-turn conversations, applies judges to the resulting behavior, and sends the scored data into the evaluation pipeline.
Q: How realistic were the simulated agent conversations?
Human review found the simulated conversations comparable to real conversations about 80% of the time. According to the description, that level of similarity was useful enough to support new-agent development, reduce the risk of changes, and protect self-service performance. The simulations are strengthened by consistent personas, account context, intents, tones, and mocked tool responses rather than relying on ungrounded dialogue alone.
Q: Why are production traces insufficient for rapid agent testing?
Production traces are inexpensive because they arise naturally from live agent use, but they impose a time and risk cost. Every experiment affects real customers, and teams may need to wait for statistically meaningful evidence that a new version improves on the previous one. Customer feedback can also be sparse and noisy, so determining whether a change is moving in the right direction can take weeks.
Q: How does Nubank use simulations in its improvement loop?
Nubank's loop begins by shipping and observing an agent, then creating robust evaluations aligned with human judgment. The team runs simulations and passes both simulated and real interactions through those evaluations. The resulting signals guide changes to the agent harness. Once the revised harness is verified as better, the team ships it and repeats the process with new observations and evaluation data.
Q: What results did Nubank report from simulation-based evaluation?
Nubank reported roughly 20 times faster agent shipping and substantial customer-satisfaction improvements across five production agents. The agents initially had weaker TNPS results, but several months and multiple quarters of work moved many toward human quality. The speakers also said the displayed results were stale and that many agents were already exceeding human quality, while evaluation cycles had fallen from weeks to hours in some cases.
Summary & Key Takeaways
-
Agent development is constrained less by changing prompts, tools, or harnesses than by obtaining useful evaluation data. Multi-turn conversations contain trajectories, tool calls, and changing state, making each example costly to create and annotate. Production traces are easier to collect, but experiments expose real customers and reliable feedback can arrive slowly.
-
Snowglobe generates synthetic personas, intents, account context, communication styles, and grounded data that remain consistent throughout simulated interactions. It runs these personas against the real agent while mocking required tools, producing thousands of multi-turn conversations. Judges then score agent behavior per turn and feed the results directly into the evaluation pipeline.
-
Nubank incorporates simulation into a continuous improvement loop: ship an agent, observe its behavior, build aligned evaluations, simulate interactions, analyze real and synthetic data, optimize the agent harness, verify improvements, and ship again. The resulting evaluation capacity supports faster launches, safer changes, regression detection, and broader experimentation with agent variants and open models.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Engineer 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator