How to Build Memory for Long-Running AI Agents
TL;DR
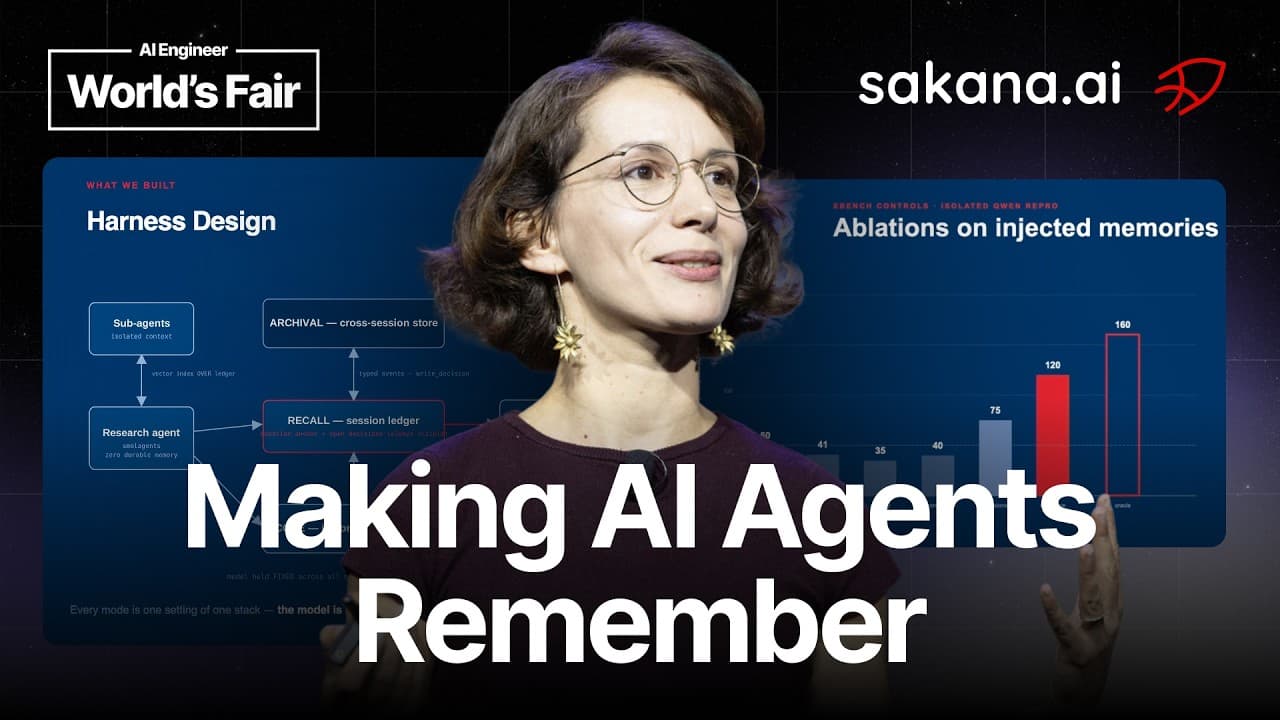
Memory harnesses are most useful when relevant information falls outside an agent’s context window. A ranked decisions ledger improved recall across long-horizon evaluations while using fewer tokens, whereas adding memory to a literature review that already fit in context increased cost without improving accuracy. Memory should therefore be treated as a write, manage, and read control loop with recall policy evaluated as a first-class metric.
Transcript
[music] >> Hello. Welcome. Uh this is a big room, so you're if you're in the back, don't hesitate to come closer. Um My name is Stefania Druga. I'm a research scientist at Sakana AI in Tokyo. Uh I used to be based here and AI engineering uh is home community for me before being the hyperloop. So, it's very good to be back. And today I'm going to ta... Read More
Key Insights
- Memory is a write, manage, and read control loop around an agent, not merely a database attached to one. The harness must decide what information to record, how to organize and prioritize it, what to retrieve, and what should survive across repeated runs and sessions.
- Context degradation causes long-running agents to contradict earlier conclusions, redo completed work, forget prior tasks, or drift away from the original question. A memory harness becomes relevant when the information needed for the current decision is no longer available inside the model’s active context window.
- Memory adds cost without adding capability when the full task and all relevant evidence already fit within the context window. In the literature-review experiment, performance remained the same with and without memory, while the memory-enabled condition consumed additional resources.
- The experimental recall ladder consisted of no recall, vector RAG, a decisions ledger, and an oracle. The underlying model remained fixed across tasks, allowing differences in performance to be attributed to the recall policy rather than changes in model capability.
- A ranked decisions ledger records decisions made at each turn and prioritizes them during retrieval. Across 68 X-Bench questions with multiple cells and seeds, ranked ledger recall performed better than memory-free operation and better than gating retrieval on whether the agent appeared to need memory.
- An oracle can supply the correct memory without producing perfect task performance. The model may ignore the supplied information, retrieve or select conflicting information, or become confused, showing that access to the right memory does not guarantee correct reasoning or use.
- Bad memory is expensive because irrelevant or incorrect retrieval consumes tokens and can direct the agent toward the wrong conclusion. A structured ranking policy can improve recall while reducing token usage and budget, so memory quality matters more than simply increasing retrieved context.
- Local evaluation provides control over data, computation traces, and every stage of the memory pipeline. The experiments used a 96 GB M3 Ultra with 28 CPU cores, running a 4-bit quantized Qwen 27B and Deep Seek V4 Flash, although serial execution made evaluations slow.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: When should an AI agent use a memory harness?
An AI agent should use a memory harness when a task extends beyond the model’s active context window and relevant facts, decisions, or instructions must be recovered from much earlier steps. In the presented X-Bench example, the answer appeared at step 124 while the question arrived at step 500. Memory was beneficial because the required evidence was no longer inside the available context.
Q: When does agent memory fail to improve performance?
Agent memory may fail to improve performance when the complete task and all relevant information already fit inside the context window. In the literature-review experiment, every paper was available within context, so adding memory produced the same accuracy as using no memory while increasing cost. The result identifies a practical boundary: retrieval is unnecessary when the model can already access everything it needs.
Q: What is a memory harness for AI agents?
A memory harness is a control system surrounding an agent that manages a write, manage, and read loop. It determines what information should be stored, how stored material should be organized, which memories should be recalled for a particular turn, and what should persist across sessions. In the described design, the harness includes an always-visible trace core, recall policies, and archival storage.
Q: How does a ranked decisions ledger improve agent recall?
A ranked decisions ledger records the decisions made during each turn and prioritizes those records when later questions require earlier information. This structured policy outperformed no recall, similarity-based vector retrieval, and a gate that first asked whether memory was needed. Its advantage came from retrieving more relevant prior decisions instead of adding arbitrary, recent, or merely similar material to the model’s context.
Q: Why does correct memory not guarantee a correct answer?
Correct memory does not guarantee a correct answer because retrieval and use are separate stages. The oracle condition supplied the right information to the model, but it did not force the model to rely on that information correctly. The model could ignore it, choose conflicting information, retrieve an incorrect detail, or become confused. Consequently, even oracle recall did not achieve maximum performance.
Q: Why can bad memory make an AI agent more expensive?
Bad memory increases cost because irrelevant or incorrect recalled material consumes context tokens and can send the agent toward an unproductive line of reasoning. The agent may then perform unnecessary work or reach the wrong conclusion. The experiments showed that a strong structural recall policy could both improve answer accuracy and use fewer tokens, making recall quality a direct budget concern.
Q: How were the memory recall policies evaluated?
The evaluation kept the underlying model fixed and changed only the recall policy. The tested ladder included memory turned off, vector RAG based on similarity, a decisions ledger that tracked and prioritized decisions, and an oracle that supplied the correct memory. Results were examined across 68 X-Bench questions with multiple cells and seeds, additional ablations, multiple models, and the Spider V2 benchmark.
Q: Can memory harness experiments run on local AI models?
Memory harness experiments can run on local models, with tradeoffs in speed and hardware demands. The described setup used a 96 GB M3 Ultra with 28 CPU cores, a 4-bit quantized Qwen 27B, and Deep Seek V4 Flash. Local execution enabled control over data, computation traces, and evaluations, but the models ran serially and Deep Seek V4 Flash did not support batch querying.
Summary & Key Takeaways
-
Memory harnesses address context degradation in long-running agents, including contradictions, repeated work, forgotten tasks, and drift from the original question. The proposed design keeps agents without durable internal memory and surrounds them with a harness containing an always-visible trace core, a configurable recall block, and archival storage that persists information across sessions.
-
The experiments held the model fixed while varying recall policies: no memory, vector RAG based on similarity, a decisions ledger that records and prioritizes decisions from each turn, and an oracle that supplies the correct memory. This setup isolated the effect of recall design rather than attributing performance changes to different underlying models.
-
Memory provided no accuracy improvement when all literature-review materials already fit inside the context window, but it became valuable on long-horizon tasks where relevant evidence appeared hundreds of steps earlier. Ranked ledger recall performed best across the tested policies, generalized across models and benchmarks, and reduced token consumption compared with poorly selected memory.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Engineer 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator