How to optimize agentic inference with open weight models
TL;DR
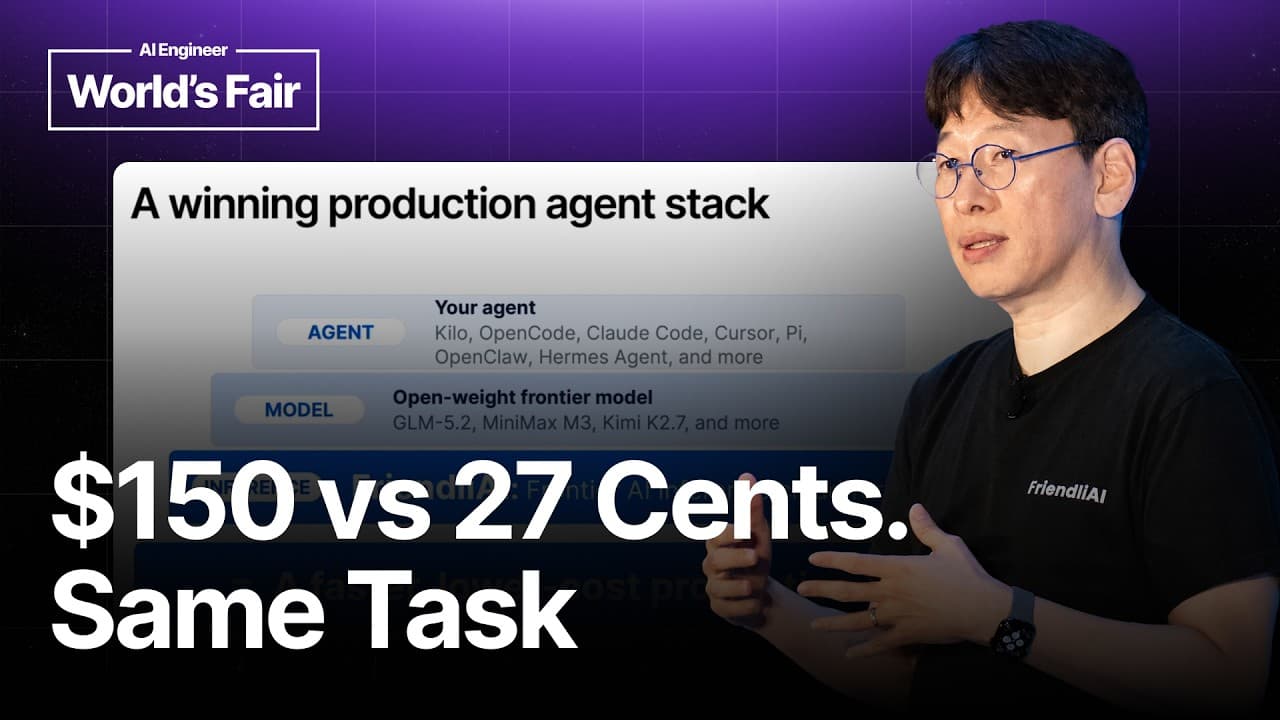
Open weight models can deliver frontier level capabilities at a fraction of cost when used for agentic workloads. By rebuilding the inference stack around tasks rather than single requests, and using techniques like prefix caching, hierarchical KV caching, and cache aware routing, end to end latency improves while keeping quality high. This approach enables production ready agents with better economics and reliability.
Transcript
Let's uh get started. Uh hi everyone. Thank you for coming. Uh this is the late afternoon in the last day. Um so I really appre appreciate it. I'm gone, founder and CEO of friendly AI. Today I want to talk about agentic inference. So I'll first walk through what changed uh why it matters and how we rebuilt the inference cloud for agents. Before we ... Read More
Key Insights
- Agent workloads are task based rather than single requests, and end to end task latency matters more than per request latency.
- Prefix caching allows computing a shared prefix once and reusing it across steps to save compute.
- Hierarchical caching spans GPU memory, host memory, and disks to extend usable context and reduce recomputation.
- Cache aware routing directs requests to the replica with the needed prefix to preserve locality and efficiency.
- Agent aware optimization uses agent level context to make scheduling decisions, not just per call optimization.
- Open weight models can achieve frontier quality while reducing cost, changing the economics of running agents.
- Four pillars define the architecture: prefix caching, cache aware routing, agent aware optimization, and underlying model optimizations.
- Producing reliable agents requires end to end optimization rather than improving individual inference steps.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is the fundamental shift in how agent workloads are treated compared to chat workloads?
The fundamental shift is that agent workloads are task driven rather than based on single requests. A task may involve multiple model cores and tools and can run for minutes or hours. The key metric becomes end to end task completion time, not the latency of an individual token or response.
Q: How does prefix caching improve agent performance?
Prefix caching improves performance by computing a large shared prefix once and caching it. On later steps, only the new suffix is processed, which reduces compute and speeds up end to end task completion. The longer a task runs, the more valuable this optimization becomes, especially when prefixes are shared across steps.
Q: Why is hierarchical caching important in Friendly AI’s approach?
Hierarchical caching is important because it extends cache reach beyond a single GPU. By packing more active context on each level of memory and using cache across GPU, host memory, and disks, the system can serve prefixes across replicas and sustain long running tasks without recomputing previously seen content.
Q: What is cache aware routing and why does it matter?
Cache aware routing matters because it balances load while preserving cache locality. It directs requests to the part of the system that already has the needed prefix cached, turning a potential cache miss into a cache hit and avoiding unnecessary recomputation while maintaining overall load balance.
Q: What does agent aware optimization entail?
Agent aware optimization means the scheduler understands the agent’s longer running program rather than treating each LLM call as independent. It enables smarter decisions like preempting work, speculatively prefilling likely next steps, and making better cache eviction choices based on the agent context to reduce end to end latency.
Q: What is the economic benefit of open weight models according to the talk?
Open weight models offer frontier quality capability at a fraction of the cost. The speaker contrasts Opus 4.8 cost with GLM 5.2, showing significant cost differences while achieving usable task results. This cost efficiency, combined with reliability and speed, drives the economic case for agentic inference with open weights.
Q: How does Friendly AI position itself in the agent inference stack?
Friendly AI positions itself as the frontier inference cloud for agents, designed to run inference at scale faster, cheaper, and more reliably. It provides multiple deployment options including model APIs, serverless endpoints, and BYOG deployments, all aimed at optimizing end to end task latency for agent workflows.
Q: What practical outcomes are demonstrated with the tower defense coding task?
The practical outcome demonstrated is that the same task can be completed end to end using open weight models with the Friendly AI stack, achieving usable results and better economics. The example shows a tangible improvement in cost while maintaining performance, illustrating how the four pillars work in practice.
Summary & Key Takeaways
-
Friendly AI presents an inference cloud optimized for agent workflows, focusing on end to end task latency rather than individual requests.
-
Open weight models reach frontier quality, and when combined with specialized caching and routing, offer faster, cheaper agentic inference for production workflows.
-
The talk highlights four pillars of the stack: prefix caching, cache aware routing, agent aware optimization, and model layer techniques to enable scalable, reliable agent workloads.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Engineer 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator