How to pick local AI hardware for running models
TL;DR
The key factors are memory capacity and memory bandwidth, which determine which models fit in fast memory and how fast they run. Use the speed formula memory bandwidth divided by model size to estimate token speed, and compare real benchmarks across devices to guide buying from budget to high end.
Transcript
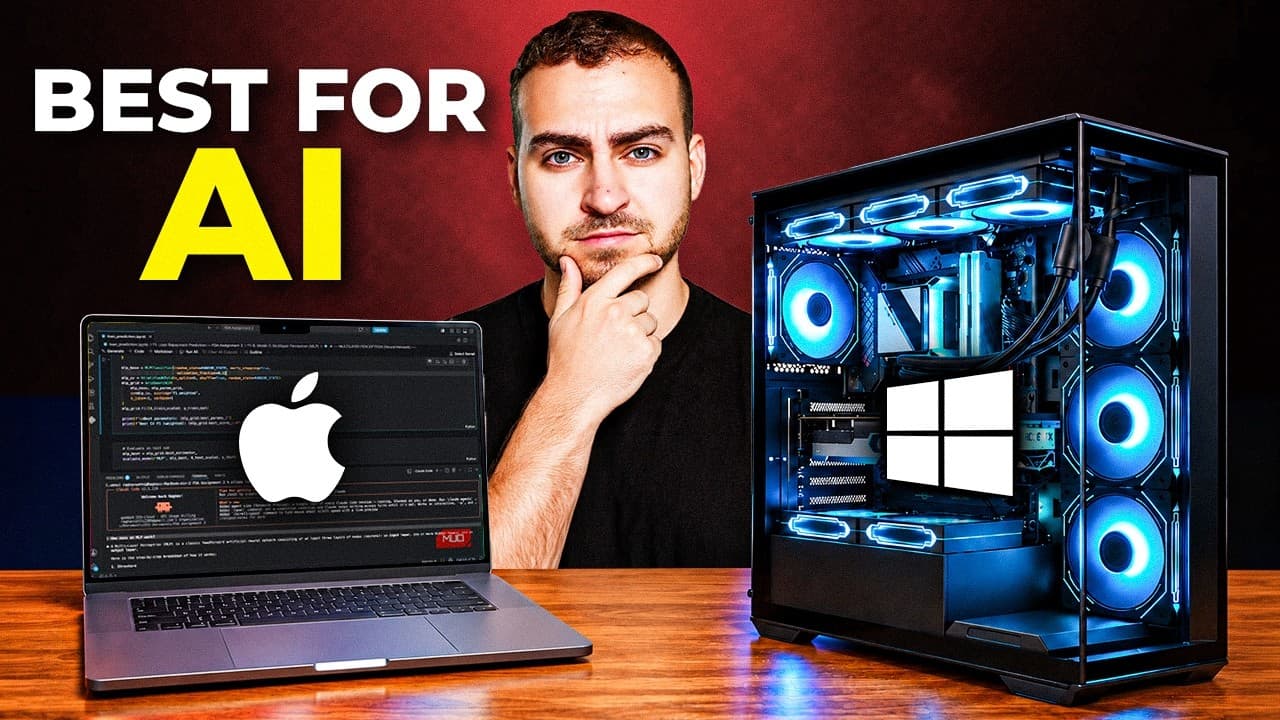
Mac or PC. Which one should you buy for running AI models? Now I own both. Plus I also have Nvidia's DGX spark, and in this video, I'm going to hopefully settle this debate with real benchmark numbers and explain why you want to pick what device, for what purpose. Now you're going to learn the two specs that decide everything, which is memory capac... Read More
Key Insights
- Capacity determines if a model can run at all by ensuring the entire model fits in fast memory accessible to the GPU.
- Bandwidth sets the theoretical ceiling for token generation speed, since memory access is required for each token.
- The speed formula is bandwidth divided by model size, which provides a close estimate of maximum tokens per second without optimizations.
- A model like 27B parameters in 4-bit quantization uses about 17GB of space, illustrating how quantization affects capacity needs.
- If a model does not fit in VRAM, performance collapses and may become unusable, especially on lower bandwidth devices.
- Mac devices with unified memory can offer large capacity but may have slower per-token speed compared to high bandwidth discrete GPUs.
- Prompts processing speed matters; reading large context or documents before responding can be a bottleneck independent of token speed.
- Benchmarks show that device choice impacts both capacity and speed, which in turn affects practical usability for different tasks.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is the main factor that decides which local AI models you can run on a device?
The main factor is memory capacity, specifically the amount of fast memory available for the GPU to hold the entire model. If the model size exceeds the available VRAM or fast unified memory, it cannot be run efficiently or at all. This constraint determines whether a device can even host a given model.
Q: How does memory bandwidth influence AI model performance per token?
Memory bandwidth determines the maximum throughput for reading the model per token. For every token generated, the model data is reread from memory, so higher bandwidth increases tokens per second. If bandwidth is low, token speed drops dramatically even if the model fits in memory.
Q: What is the simple formula to estimate model speed on a device?
The speed can be estimated with a simple formula: memory bandwidth divided by the model size. This provides a ceiling on tokens per second that the device can achieve without optimizations, helping compare different hardware setups and guide purchases according to required performance.
Q: Why is the Mac vs PC debate relevant for local AI?
The debate centers on memory architecture: Macs often use unified memory shared between CPU and GPU, while PCs use separate system RAM and VRAM. Unified memory can host large models but may have different speed characteristics, whereas discrete GPUs on PCs can offer higher bandwidth but with smaller effective memory pools for some models.
Q: What did the benchmarks in the video compare?
The benchmarks compare token decode speeds across devices such as TX 5090, RTX 3090, M5 Max, DGX Spark, and Rise in AI Max, for a 27B parameter model with 4-bit quantization, illustrating how capacity and bandwidth translate into actual token rates under baseline conditions.
Q: What is the impact of model size on required memory and speed?
Larger models require more VRAM or unified memory capacity to fit entirely, and if they don’t fit, speed drops and usability worsens. As model size grows, only devices with substantial memory and bandwidth can maintain reasonable token rates, making capacity a decisive factor for choice.
Q: How important is prompt processing speed in practice?
Prompt processing speed is important because it determines how quickly a device can ingest large inputs before generating the answer. Even with fast token speeds, reading thousands of tokens of context or documents can be a bottleneck, so prompt processing capacity must be considered alongside token speed.
Q: What is a practical buying ladder suggested by the video?
The video suggests matching your hardware to your budget and needs, from affordable options that run smaller models to high-end devices with large memory and high bandwidth for faster token speeds. The ladder emphasizes balancing capacity and speed to achieve usable, scalable local AI performance.
Summary & Key Takeaways
-
A local AI setup must have enough fast memory to hold the entire model in VRAM or unified memory, otherwise performance drops dramatically and operation may be impractical.
-
Bandwidth dictates how quickly each token is processed, because the device rereads the model from memory for every token, so higher bandwidth enables higher token per second speeds.
-
Benchmarks across devices show a trade-off between capacity and speed, with Mac unified memory offering large capacity and PC GPUs delivering high bandwidth, ultimately informing a tailored buying ladder for different budgets.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Tech With Tim 📚

Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator