How Does Prompt Caching Reduce LLM Latency?
TL;DR
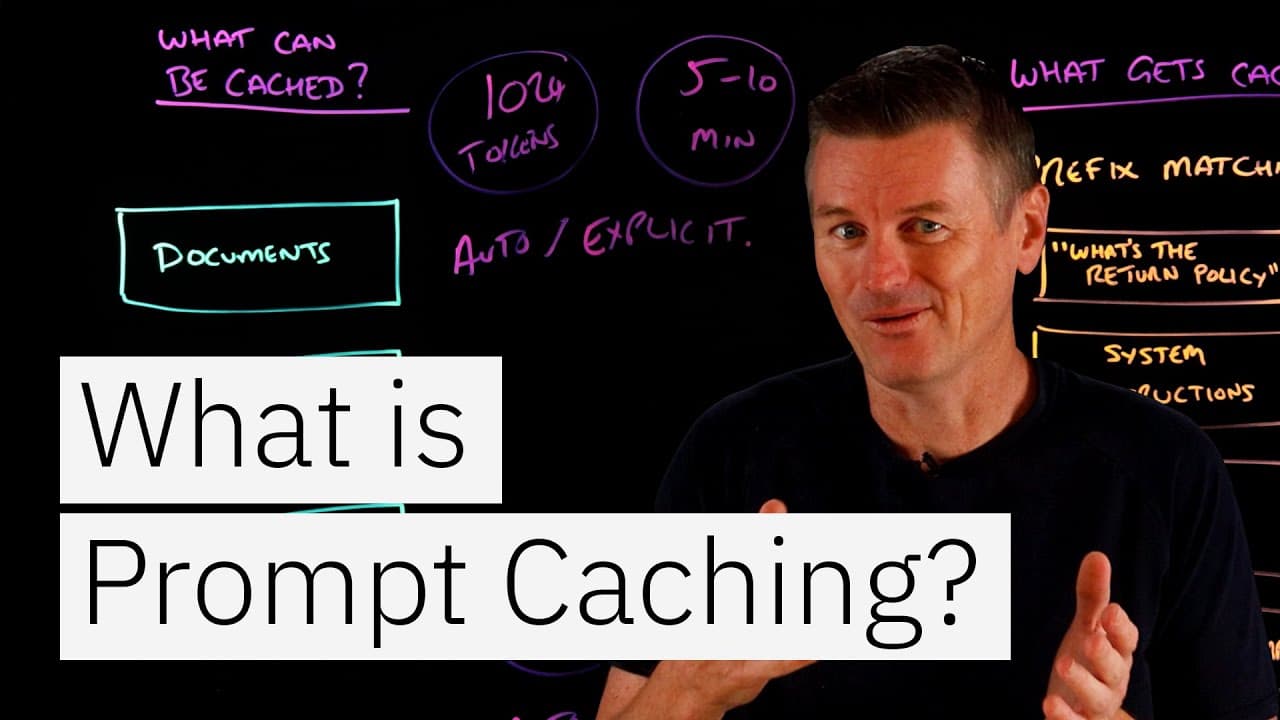
Prompt caching reduces LLM latency and cost by storing precomputed key-value pairs for reusable prompt prefixes, allowing the model to avoid processing the same input tokens again. It is most useful for long, repeated content such as system instructions, documents, examples, tool definitions, and conversation history, especially when static content appears before changing user questions.
Transcript
Prompt caching can significantly improve the speed and cost effectiveness of large language models. Sounds good. Sign me up. But, um. But what is prompt caching? Well, let me start by defining what prompt caching is not. So it is not regular output focused caching. So let me give you an example of that. If you've sent in a query and you've sent tha... Read More
Key Insights
- Prompt caching is an input-processing optimization that stores precomputed key-value pairs rather than completed LLM responses. It allows the model to reuse internal processing for matching prompt content while still generating a new answer for each request.
- Key-value pairs are computed at every transformer layer for every input token. They represent the model’s internal understanding of relationships, context, and relevant information, and their computation occurs during the prefill phase before the first output token is generated.
- Output caching is different from prompt caching because it returns a stored response when an identical query is repeated. Prompt caching still invokes the LLM, but it avoids recomputing the cached input portion before producing a new response.
- Long repeated prompts provide the clearest caching benefits because processing thousands of tokens across dozens of transformer layers requires millions of operations. A short prompt, such as a simple factual question, is too cheap and fast to offer much potential saving.
- Reusable prompt content can include documents, system instructions, few-shot examples, tool and function definitions, and conversation history. These elements are useful caching candidates when they remain unchanged across multiple requests or conversations.
- Prefix matching works from the very beginning of a prompt, comparing tokens until the first difference appears. The cached key-value pairs can be reused only for the matching prefix, after which the model resumes normal processing for new content.
- Static content should appear before dynamic content in prompts designed for automatic caching. Placing system instructions, documents, and examples first lets the cached prefix remain valid when the user question at the end changes.
- Prompt caches typically require at least 1,024 tokens before caching begins because management overhead can exceed savings below that threshold. Caches are usually cleared after 5 to 10 minutes, although some can remain available for up to 24 hours.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is prompt caching in an LLM?
Prompt caching is a technique that stores the precomputed key-value pairs created while an LLM processes input tokens. When a later request begins with the same prompt content, the model can retrieve those pairs instead of processing the matching input again. It still generates a new response, but it reduces repeated work during the prefill phase.
Q: How is prompt caching different from output caching?
Output caching stores a completed response and returns it when the same query appears again, potentially skipping the LLM call entirely. Prompt caching stores only the processed representation of the input prompt. The LLM still handles the request and generates an answer, but it can reuse key-value pairs for the matching prompt prefix instead of recomputing them.
Q: How does prompt caching reduce LLM latency?
Prompt caching reduces latency by avoiding repeated calculation of key-value pairs for unchanged input tokens. Those calculations occur across transformer layers during the prefill phase, before the model produces its first output token. Retrieving stored pairs for a matching prefix lets the model process only the new portion, such as a different question appended to a shared document.
Q: What types of prompt content can be cached?
Cacheable content can include large documents, system prompts, few-shot examples, tool and function definitions, and conversation history. System prompts are a common use case because chatbots repeatedly use the same personality, rules, and behavioral instructions. Documents also benefit when users ask multiple questions about the same manual, research paper, legal contract, or other source material.
Q: How does prefix matching work in prompt caching?
Prefix matching compares a new prompt with cached content from the beginning, one token at a time. The cache remains usable while the tokens match exactly. When the system encounters the first different token, reuse stops at that point and ordinary processing begins. This behavior makes the order of static and changing prompt elements important for effective automatic caching.
Q: How should a prompt be structured for automatic caching?
A prompt should place reusable static content first and changing content last. For example, system instructions can come first, followed by a manual and few-shot examples, with the user’s question at the end. When a later request changes only the final question, prefix matching can reuse all earlier content and process only the new question.
Q: When is prompt caching most useful?
Prompt caching is most useful when requests repeatedly contain long, identical prefixes. A 50-page document followed by different questions is a strong example because the model would otherwise recompute key-value pairs for thousands of tokens across dozens of transformer layers. Simple prompts with only a handful of tokens provide little benefit because their processing is already cheap and fast.
Q: What are the token threshold and lifetime of a prompt cache?
Prompt caching typically requires at least 1,024 tokens before it begins, because below that point the overhead of managing the cache can exceed the processing savings. Caches also expire. They are usually cleared after 5 to 10 minutes to keep data fresh, although some caches can remain available for as long as 24 hours.
Summary & Key Takeaways
-
Prompt caching stores the key-value pairs calculated for input tokens during the transformer prefill phase. Unlike output caching, it does not reuse a previously generated answer or skip the LLM call. Instead, it preserves the model’s earlier processing of reusable prompt content so generation can begin with less repeated computation.
-
Long documents, system prompts, few-shot examples, tool definitions, and conversation history can benefit from caching. A model can reuse the processing for a document prefix while answering different questions about it. This reduces the work required across transformer layers before the model generates its first output token.
-
Automatic caching relies on prefix matching from the beginning of a prompt, token by token. Static content should therefore appear before dynamic content such as user questions. Caching typically begins at 1,024 tokens, caches may last 5 to 10 minutes or up to 24 hours, and provider implementations vary.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator