How to Use Metadata to Make RAG Agents Smarter

TL;DR
Metadata is data about data. Attaching fields such as video title, URL, and timestamp to each vector chunk lets a RAG agent cite the exact source of an answer. Metadata does not change a chunk's meaning or where it sits in the vector database. Its value is in giving more context on retrieval, keeping data organized, and filtering searches to specific sources.
Transcript
Today I'm going to be talking about the different ways you can use metadata to make your rag agents much more intelligent. Not only does metadata let us organize and filter through our data, but it also lets us enrich it so that we can get way more context as to what chunks we're looking at. If it doesn't make too much sense to you yet, don't worry... Read More
Key Insights
- Metadata is data about data. Any loaded content can be enriched with fields such as date, department, author, file name, or file size, which give an AI agent extra context about each chunk it retrieves from a vector database.
- Without metadata, a retrieved chunk carries no record of its origin. With three transcripts stored in one vector database, the agent could not tell which YouTube video a chunk came from or back up its answer with a source.
- Metadata has no effect on a chunk's meaning or on where it is placed in the vector database. Search embeds the query and pulls back the nearest chunks based only on the content, and metadata is read after retrieval for context.
- Metadata filtering lets a search be limited to certain sources. For example, a query can be restricted to transcript C alone when the user knows which video holds the insight they want.
- Metadata in vector database RAG has three main benefits: more context when results come back, better organization and segmentation of data, and filtering so that only the wanted results are returned.
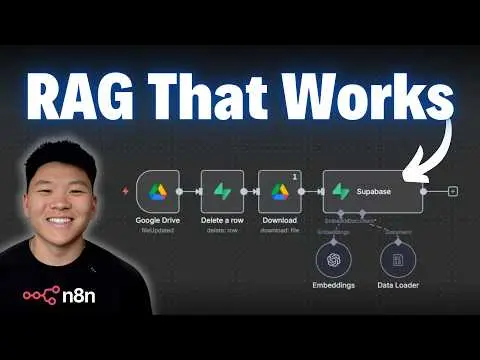
- The demo pipeline is built in n8n. A form submission collects a video title and URL, Apify scrapes the transcript, code nodes clean and chunk it, the chunks are stored in a Supabase vector store, and a Google Sheet logs the processed videos.
- The Apify transcript scraper returns hundreds of small objects, each with a start time, a duration, and text. The creator wrote n8n code nodes by pasting a sample of this JSON schema into Claude and describing the output he wanted.
- Timestamps are kept by grouping 20 transcript objects per chunk. The chunk takes its start time from the first object and its end time from the last object's start time plus its duration, giving about 40 seconds per chunk.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is metadata in a RAG system?
Metadata is data about data. In a RAG system it is extra information attached to each chunk stored in a vector database, such as the date, department, author, file name, file size, or, for YouTube transcripts, the video title, video URL, and timestamp. It gives the agent context about where a retrieved chunk came from, so answers can be traced back to an actual source.
Q: Does metadata change how vector search finds chunks?
No. Metadata has no effect on the meaning of a chunk or on where that chunk is placed in the vector database. During a search the query is embedded, placed in the vector space, and the nearest chunk or chunks are returned based only on the content's meaning. Only after a relevant chunk is retrieved is its metadata read to add context, such as which video and timestamp it came from.
Q: Why does a RAG agent need metadata to cite sources?
When transcripts are chunked and embedded, each vector point represents only a piece of text. If several transcripts are stored together, a retrieved chunk carries no record of which video it belongs to. Without metadata such as the video title, URL, and timestamp, the agent cannot say where an insight came from, and users have little reason to trust a response it cannot back up with a source.
Q: What are the main benefits of adding metadata to a vector database?
There are three main benefits. First, retrieval gives more context, since each returned chunk arrives with details like its title, URL, or timestamp. Second, data stays more organized and segmented across different sources. Third, metadata filtering lets a search return only what is wanted, such as limiting a query to a single transcript when the user already knows which video holds the relevant insight.
Q: How does metadata filtering work in RAG?
Metadata filtering restricts a vector search to chunks whose metadata matches a condition. For example, if a vector database holds transcripts A, B, and C, a query can be limited to transcript C only because the user knows that video contains the insights they want. The search still ranks chunks by meaning, but only within the subset of chunks whose metadata fits the filter.
Q: How do you build a YouTube transcript RAG pipeline in n8n?
The demonstrated workflow starts with a form that collects a video title and URL. An HTTP request to Apify scrapes the transcript. Code nodes clean the output and group it into chunks with timestamps. A merge node combines the results, a default data loader sends the chunked text and metadata into a Supabase vector store, and a Google Sheet is updated to record which videos have been processed.
Q: How can you keep timestamps on each transcript chunk before vectorizing?
The Apify output is a list of objects, each with a start time, a duration, and text. A code node groups 20 of these objects at a time and joins their text into one chunk. The chunk's start time comes from the first object, and its end time is the last object's start time plus its duration. In the example this produced 25 chunks, each covering about 40 seconds.
Q: Which metadata fields are set in the Supabase data loader for transcripts?
The default data loader vectorizes only the chunked text with timestamps, not the full combined transcript. It adds three metadata fields to every chunk. The video title and video URL are dragged in from the form submission. The timestamp is built from the merge node's formatted start time, a manually typed dash, and the formatted end time, which creates a time range for each chunk.
Summary & Key Takeaways
-
Metadata, or data about data, makes RAG agents more useful by adding context to each stored chunk. In a demo, a YouTube transcript agent answers a question about relational versus vector databases and also returns the source video title, the exact timestamp, and a clickable link to the full video.
-
Metadata does not affect a chunk's meaning or where it sits in the vector store. Retrieval uses only the embedded content. Metadata is then read for context, used to keep data organized and segmented, and applied as a filter, for example to search only one chosen transcript among several.
-
The n8n pipeline takes a video title and URL from a form, scrapes the transcript with Apify, and uses code nodes to group 20 transcript objects per chunk with start and end times. A default data loader then stores each chunk in Supabase with video title, timestamp, and URL as metadata.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Nate Herk | AI Automation 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator