How to handle AI tool outages and bugs
TL;DR
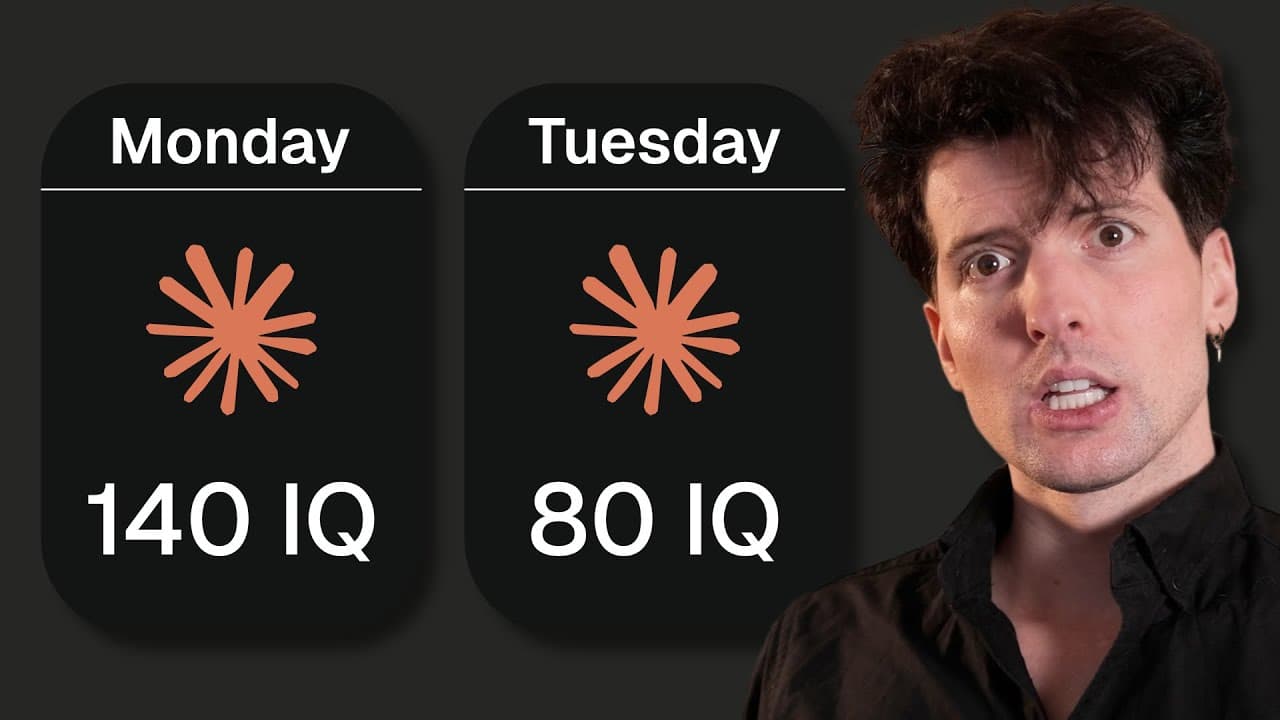
Claude showed degraded intelligence and downtime due to multiple issues, including two identified problems that were resolved and a separate Opus degradation. The video explains how outages affect developers, the importance of monitoring incidents, and practical workarounds, including relying on API uptime and sponsor mentions like WorkOS for better reliability.
Transcript
You guys have probably noticed that I've soured a little bit on Anthropic over the last year or two. There are a bunch of small reasons for it, but the big one is that they broke my hand. No, they didn't do that. What they actually did was put out models and tools that I just was finding less and less useful. Cloud Sonnet 4 was a huge drop when it ... Read More
Key Insights
- Claude has experienced degraded intelligence, where model quality drops but responses still occur, impacting usefulness and accuracy. The key is recognizing this as a separate failure mode from outright downtime.
- Downtime and outages on the Claude site and API create reliability concerns for developers, with users reporting inconsistent access and broken chat experiences, underscoring the need for fallback plans.
- Anthropic reported two degraded quality issues that were addressed, plus a separate Opus performance degradation incident, indicating multiple concurrent reliability challenges across different model variants.
- There is a noticeable discrepancy between website uptime and API uptime, with the API generally offering more reliable access, suggesting API-based workflows as a partial mitigation.
- The video highlights ongoing monitoring and incident reporting as essential practices when service reliability is variable, including updates that claims fixes were implemented.
- Community sentiment around Claude is volatile, with public forums showing speculation and frustration about continued performance concerns and outages.
- The sponsor segment promotes WorkOS as a solution for enterprise readiness, focusing on SAML and integration capabilities to simplify admin and security concerns during deployments.
- The presenter emphasizes that reliability issues are systemic and industry-wide, not just isolated to one product, urging viewers to consider infrastructural resilience and developer experience in AI tool choices.
- More videos from this channel:
- More from this channel: Theo - t3․gg
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What are the two categories of Claude issues discussed and how do they differ?
The two categories are degraded intelligence and actual downtime. Degraded intelligence means the model quality is worse but responses still arrive, affecting usefulness and accuracy, while downtime means the site or API is unreachable or unresponsive, preventing any interaction. Recognizing both helps in planning appropriate mitigations, such as relying on API uptime or preparing fallback tools.
Q: What evidence is presented that Claude outages were widespread or ongoing?
The video notes multiple incidents including the site outage, differences in what status pages show, and reports of the site being down or slow. The speaker mentions Claude Opus degradation and separate incidents, with status updates claiming fixes were implemented, followed by continued access issues, illustrating a pattern of repeated reliability problems across time.
Q: How does the speaker view the reliability of Claude compared to other chat tools?
The speaker expresses frustration with Claude reliability, contrasting it with other tools that provide better uptime or more dependable access. He implies that other chat apps and providers are more reliable at the moment, which fuels his criticism and perspective that Claude has underperformed in reliability relative to peers.
Q: What is the role of status pages and internal updates in managing outages according to the video?
Status pages and internal incident updates play a crucial role in communicating outages, describing what went wrong, what has been fixed, and what the plan is to prevent recurrence. The speaker highlights chaos around status pages, suggesting that clear, consistent, and timely updates are essential to help users understand the situation and adjust their workflows.
Q: What workaround or alternative does the video suggest for better reliability in practice?
A practical takeaway is to consider API uptime as a more reliable access point than visiting the website, since API endpoints often have better uptime characteristics. Additionally, the video suggests evaluating other tools or platforms that may offer more consistent performance during degraded intelligence or outages.
Q: What is the sponsor mentioned and what is its relevance to reliability?
The sponsor is Work OS, which is presented as a solution for better operational reliability in enterprise contexts. The discussion emphasizes integration capabilities, SAML, and administrator tooling to ensure smoother onboarding and configuration for organizations relying on AI tools within their software stack.
Q: How does the speaker relate outages to the broader AI industry and user expectations?
The speaker argues that reliability is a fundamental concern in the AI industry, noting that outages and degraded performance undermine trust and usability for daily workflows. He stresses the need for monitoring, incident handling, and robust infrastructure as observed industry-wide to avoid eroding user confidence in AI tooling.
Q: What is the overall takeaway regarding Claude’s performance and future expectations?
The overall takeaway is that Claude’s performance has been inconsistent due to multiple reliability issues, including degraded intelligence and downtime, with some claims of fixes. The speaker recommends vigilance, monitoring, and using more reliable access methods or tools while awaiting more stable and predictable performance from Anthropic and comparable providers.
Summary & Key Takeaways
-
The video analyzes recent Claude performance problems, highlighting degraded intelligence and downtime as two separate issue categories, with the speaker detailing how these problems affected his workflows and how Anthropic has claimed to resolve them.
-
It discusses infrastructure reliability and the impact of outages on daily tooling, comparing site uptime to API uptime and emphasizing the need for resilience strategies and monitoring during outages.
-
The sponsor segment promotes WorkOS and explains why robust O implementations and integrations matter for enterprise reliability and smoother customer onboarding when using AI tools.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Theo - t3․gg 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator