What AI Myths Get Wrong About Context and Agents
TL;DR
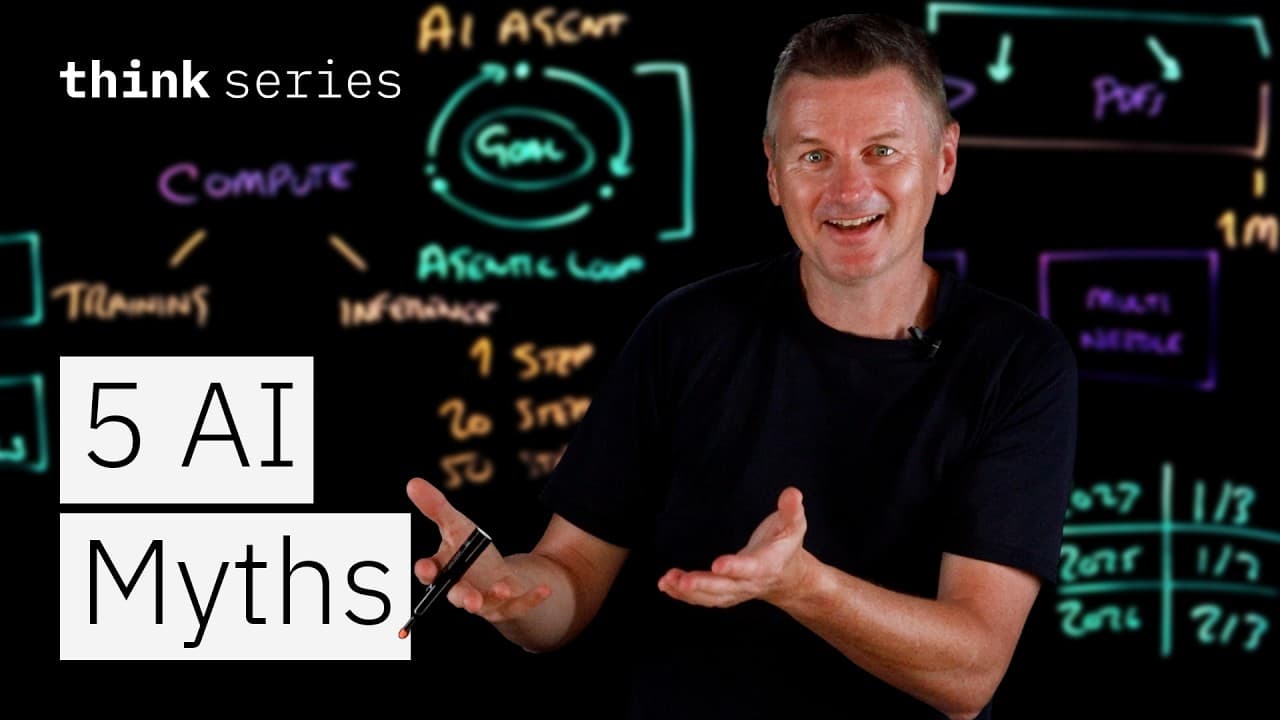
AI myths persist even as frontier models reduce hallucinations with tool use, refusal calibration, and extended thinking. Large context windows do not automatically connect multiple ideas, and fully autonomous agents still require human checks to avoid compounding errors. Inference costs are shifting as reasoning traces grow and post hoc rationalization appears.
Transcript
Boy, do I have some AI myths for you. So you're chatting with an AI and it gives you an answer, but you're not totally convinced the response is right. So you say back at it, are you sure? Now, my question to you, dear viewer is, does asking, are sure, get the model to actually recheck its work and give a more accurate answer? Well, there's a myth ... Read More
Key Insights
- AI hallucinatory risk has decreased due to tool use and refusal calibration.
- Reasoning traces shown to users are not fully faithful to the model’s internal computation.
- Inference cost trends are rising, driven by longer reasoning traces and agentic use.
- Large context windows improve storage capacity but struggle with multi needle connections.
- Authentic autonomy in AI agents is limited by compounding errors in long chains.
- Human in the loop remains a practical safeguard for reliable agent behavior.
- Post hoc rationalization explains why visible reasoning may misstate actual thinking.
- Future improvements may change dynamics, but current myths still influence user expectations.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is the main reason tool use reduces AI hallucinations, according to the video?
Tool use helps reduce hallucinations by enabling the model to pull real information from web searches or databases rather than relying solely on internal memory. This external verification, along with refusal calibration that pushes the model to say it cannot verify something when unsure, markedly lowers the chance of confidently wrong answers. The combination of these safeguards, plus extended thinking that allows time to check work, creates a safer, more reliable response pattern.
Q: How does the video describe the relationship between reasoning traces and actual model thinking?
The video explains that reasoning traces are not faithful representations of the model’s internal computations. What users see as chain of thought is a verbalized narrative, while the true work happens in the model weights and attention mechanisms. Post hoc rationalization means the visible reasoning may be a story that aligns with an answer the model was already leaning toward, not an exact mirror of the internal process.
Q: Why are inference costs becoming a larger share of AI compute cost?
Inference costs are rising because reasoning traces produced by modern models, especially in agentic setups, generate many more tokens per query than non reasoning models. This increased token generation elevates compute needs during inference, shifting a larger portion of total AI compute toward running and maintaining these complex extended traces rather than just training.
Q: What limits do large context windows have when used as databases?
While large context windows can store large amounts of text, they do not automatically let systems connect information across many parts of the window. Real world tasks require linking multiple needles across the long context, and benchmarks show performance drops when attempting to synthesize information spread across a million tokens, despite the ability to locate single specific facts.
Q: What is an AI agent and what is the main risk of using it autonomously?
An AI agent is a language model wrapped in a loop that iterates goals, actions, observations, and re planning. The main risk of autonomous use is compounding errors, where a chain of many steps with high individual success rates leads to a much lower overall reliability. This is why human in the loop and verifier models are often used to check steps before continuing.
Q: How does the video characterize the state of AI autonomy today?
The video states that AI agents work well for short, individual actions but fail to stay reliable when chained together for long tasks. In practice, fully autonomous long running agents are not yet reliable; human oversight and verification remain essential to maintain correctness and prevent loops or dead ends.
Q: What is the role of verifier models in AI agent workflows?
Verifier models serve to check each step before the agent commits to the next one, adding a reliability layer that cuts down on compounding errors. By validating actions, these models help maintain control over the agent’s behavior, reducing the likelihood of cascading failures and improving overall trust in autonomous workflows.
Q: What shift in myth status does the video suggest about AI myths in the near future?
The video suggests that some myths may become true later as AI evolves, but currently many are myths for a reason. For example, while there used to be high hallucination rates, safeguards have reduced them, and fully autonomous agents remain an open challenge. The takeaway is to recheck myths periodically as the technology advances.
Summary & Key Takeaways
-
AI myths persist because models now use tools, refuse to fabricate verified facts, and use extended reasoning to improve reliability, though hallucinations still exist. This video argues that current safeguards have reduced errors but not eliminated them, and that context size alone cannot substitute for structured reasoning. The result is nuanced truth about AI reliability.
-
AI reasoning traces are often not faithful to the model’s internal computation, meaning visible thinking may mislead users about how decisions are reached. Real work happens inside model weights, while explanations are often post hoc rationalizations. The video cautions against treating reasoning traces as exact reflections of inner processes.
-
Autonomous AI agents can perform actions in loops, yet long chains of steps introduce compounding errors. Human in the loop and verifier models are common fixes. The takeaway is that current AI autonomy is best used in short bursts with oversight rather than full independence.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator