How to adopt open data lakehouse for scalable analytics
TL;DR
The open data lakehouse provides easy access, fast deployment, and cost efficient analytics by unifying data from diverse sources. It enables fast data sharing with governance while allowing workloads to run where they perform best. This open approach supports faster time to value and adaptable modernization.
Transcript
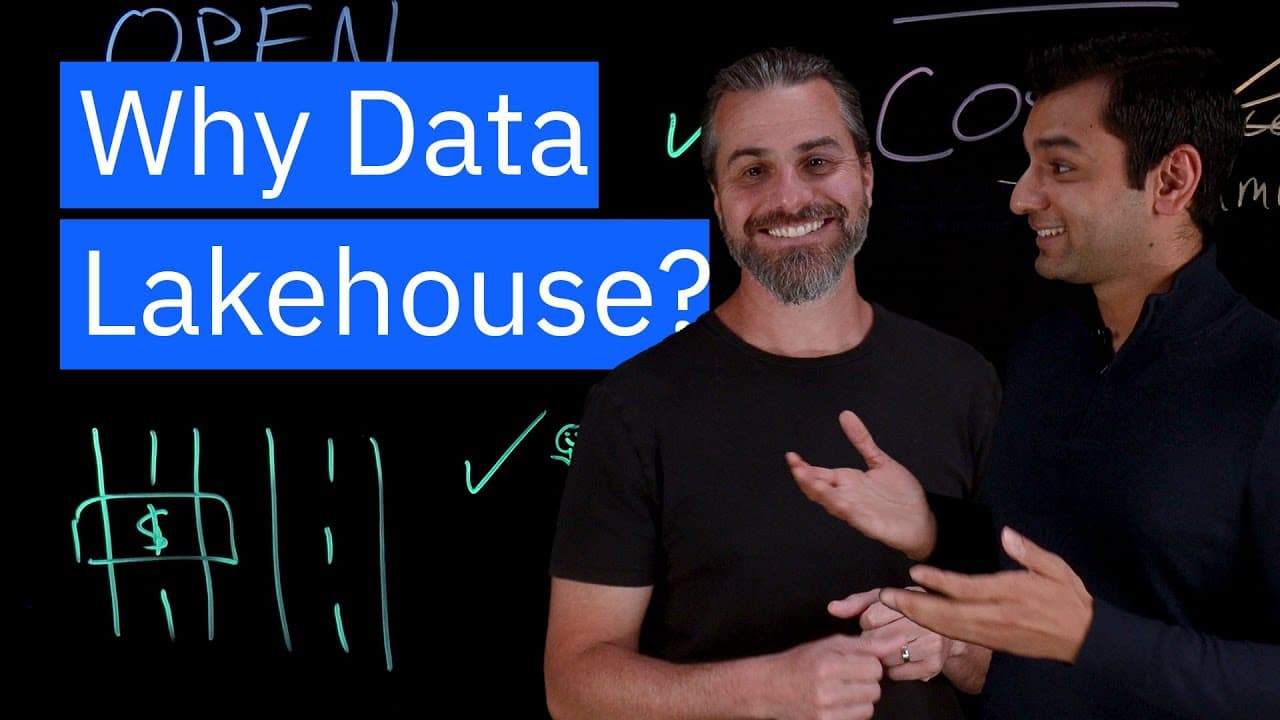
In a previous video, we talked about the data Lakehouse concept and shared a story about how data lakehouses are much like the operations of a commercial kitchen in a restaurant. So definitely check out that video if you haven't seen it. Today, I'd like to discuss more about the key drivers for and values delivered by an open data lakehouse archite... Read More
Key Insights
- Data volume and data variety are driving rising data costs.
- Data consumption is expanding with more business users and AI use cases.
- An open lakehouse lets you use the right tool for the right job and control costs.
- Open means no forced migration from existing warehouses or lakes.
- Open data lakehouses avoid vendor lock-in and prohibit excessive copying of data.
- Governance and security are built in to support data sharing and compliance.
- New workloads should start in the lakehouse, with existing environments supported.
- The architecture aims to optimize price performance across storage and compute tiers.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is an open data lakehouse and why is it valuable?
An open data lakehouse is a architecture that unifies data from multiple sources and formats while remaining compatible with existing data environments like data warehouses and data lakes. It enables easy access, cost effective storage, and governance across data sharing and analytics. The value lies in reducing procurement friction, enabling quick data consumption by business users, and optimizing analytics workloads for cost and performance.
Q: How do macro trends influence data lakehouse adoption?
Macro trends show data volume and cost are rising, consumption is expanding, and architectures are being disrupted. An open data lakehouse addresses these by consolidating diverse data, democratizing access for more users, and providing a flexible path to modernize from existing warehouses or lakes. This helps organizations scale analytics and AI while controlling costs and governance.
Q: What does governance look like in an open data lakehouse?
Governance in an open data lakehouse is built in to support data sharing and compliance while avoiding unnecessary data copies. It emphasizes secure access controls, lineage, and policy enforcement so that business users can access data quickly in a trustworthy environment. This balance enables broader data usage without sacrificing governance.
Q: Why is openness important in this architecture?
Openness allows organizations to leverage capabilities across existing data environments rather than forcing migration. It enables modernization over time and prevents vendor lock-in. Openness also supports broader data reuse, better governance, and lower costs by avoiding proprietary formats and enabling data to be used where it performs best.
Q: How does the lakehouse affect cost and performance?
The lakehouse enables optimization of price performance by letting workloads run where they perform best and cost least, using the right tool for the right job. It supports storage and compute tier optimization, reducing unnecessary spending while maintaining fast access to data for analytics and AI workloads.
Q: What role does democratization play in this approach?
Democratization means business users can access data quickly and easily, enabling faster decision making and AI-driven automation. This requires governance to ensure compliance and secure sharing, but the result is faster value realization and broader data-driven insights across the organization.
Q: Can existing data environments coexist with a lakehouse?
Yes, an open lakehouse is designed to work alongside data warehouses and data lakes. It should not force migration; instead it provides a modernization path and the ability to start new data and workloads within the lakehouse while preserving existing environments. This coexists for a smoother transition and shared governance.
Q: What is the practical takeaway for executives considering this architecture?
Executives should view the open data lakehouse as a flexible, cost aware path to scale analytics and AI. It supports easier access to data, faster deployment, and governance without vendor lock-in. The practical outcome is lower total cost of ownership, faster insight generation, and the ability to adapt analytics to evolving business needs.
Summary & Key Takeaways
-
The open data lakehouse unifies large amounts of data from different sources and formats, enabling easier access and storage while maintaining governance. It is designed to be easy to deploy within existing environments, reducing procurement and wrangling time. It optimizes analytics by choosing the right tool for the right job at the right cost.
-
Users can leverage existing environments without forced migration, while new data and workloads can use the lakehouse as a modernization path. This approach emphasizes openness, avoids vendor lock-in, and minimizes data copies, helping reduce costs and improve governance across the analytics stack.
-
Open data lakehouses support broader data democratization by enabling business users to access data quickly and securely, driving faster insights and AI-enabled decision making while adhering to regulatory requirements and governance policies.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator