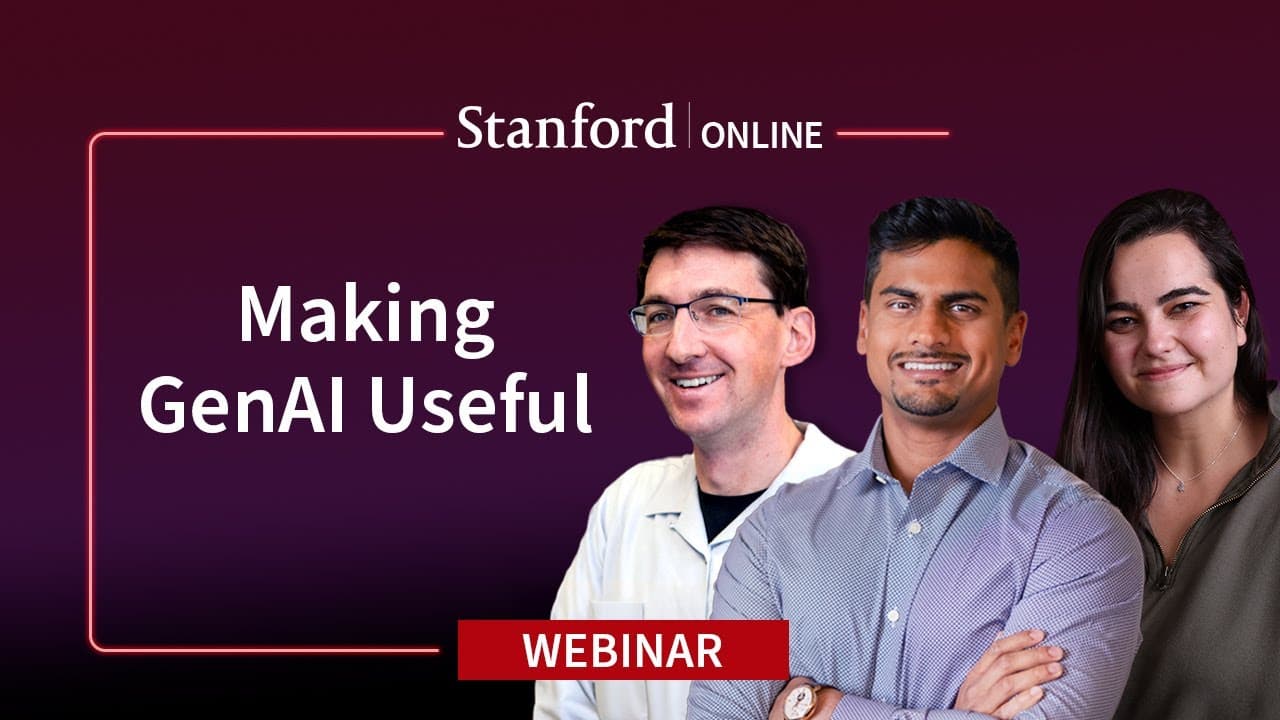
Stanford Webinar: How Can We Make GenAI Useful? Lessons from Research and Deployment
TL;DR
Generative AI becomes useful when post-training aligns a capable but difficult-to-use base model with human preferences and elicits specific capabilities. Stanford professor Christopher Potts also recommends context engineering, data curation, continued pre-training, and supervised fine-tuning, which he describes as relatively predictable and controllable. Read on to understand how these methods shape model behavior and surface latent capabilities.
Transcript
PETRA: We have three very, very exciting guests today. We have Aditya Challapally, who is the machine learning engineer and product lead at Microsoft, and he's also one of the instructors in the course Master in GenAI for Product Innovation. He will be our amazing moderator. So in a little bit, I will hand it over to him and he will lead us through... Read More
Key Insights
- Base models are often underestimated in their capabilities, especially for creative tasks.
- Post-training processes align models with human preferences, making them more user-friendly.
- The systems surrounding AI models are crucial for user experience, not just the models themselves.
- Truthfulness in AI models can be achieved by grounding them in reliable sources.
- Developers should focus on building robust evaluation systems to ensure model reliability.
- Instruction following in AI models is complex and involves various categories like format and content.
- Models are becoming increasingly interpretable as they improve, revealing systematic structures.
- Synthetic data, combined with human data, can accelerate model evaluation and development.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How can generative AI models be made more useful?
Post-training can align base models with human preferences and elicit specific capabilities, making them easier to use as assistants. Context engineering, continued pre-training, supervised fine-tuning, and careful data curation can also bring latent capabilities to the surface.
Q: What is a base language model?
A base model is the raw form of the model produced at the end of pre-training. It is trained for next-token prediction on a vast corpus of language and can be highly intelligent, but it is often difficult to use directly.
Q: What is the difference between pre-training and post-training?
Pre-training develops a base model through next-token prediction over a vast language corpus. Post-training then aligns that model with human preferences or draws out specific capabilities so it behaves more like a useful assistant.
Q: Why are base models difficult to use?
Base models continue text rather than naturally responding as helpful assistants. Michelle Pokrass explains that asking a base model “how do I ride a bike?” could produce another question such as “how do I drive a car?” instead of an answer.
Q: Are base models more capable than people assume?
Christopher Potts argues that people underestimate base models, especially on tasks involving creativity. They may contain latent capabilities that can produce surprising results, although their behavior is less predictable and requires more context engineering.
Q: How does context engineering help base models?
Context engineering supplies the guidance needed to make less predictable base models perform the intended task. Potts says it can help bring latent capabilities to the fore and may itself become part of the engineering and creative process.
Q: Why use supervised fine-tuning in post-training?
Supervised fine-tuning can surface capabilities already present in a base model. Potts describes it as a predictable and controllable option compared with more advanced reinforcement-learning algorithms, and notes that it often appears alongside more sophisticated methods.
Q: What role does data curation play in supervised fine-tuning?
Data curation helps provide suitable examples for bringing desired model capabilities to the surface during supervised fine-tuning. Potts presents it as an important consideration when planning a post-training process.
Summary & Key Takeaways
-
Generative AI models can be more practical by aligning them with human preferences through post-training processes. This alignment makes models more intuitive and user-friendly, essential for real-world applications. Developers should focus on building robust systems around AI models to enhance user experience.
-
Evaluating AI models through effective systems is crucial for ensuring reliability and truthfulness. This involves grounding models in reliable sources and using both human and synthetic data for comprehensive evaluation. Instruction following is a key area of focus, with different categories like format and content.
-
The interpretability of AI models has improved, revealing systematic structures that aid understanding. This development opens up new possibilities for applications in education, legal representation, and creative industries. Developers should leverage these capabilities to build innovative and effective AI-driven solutions.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Stanford Online 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator