How Do Rhythm Garg and Linden Li Make Reinforcement Learning Efficient at Applied Compute?
TL;DR
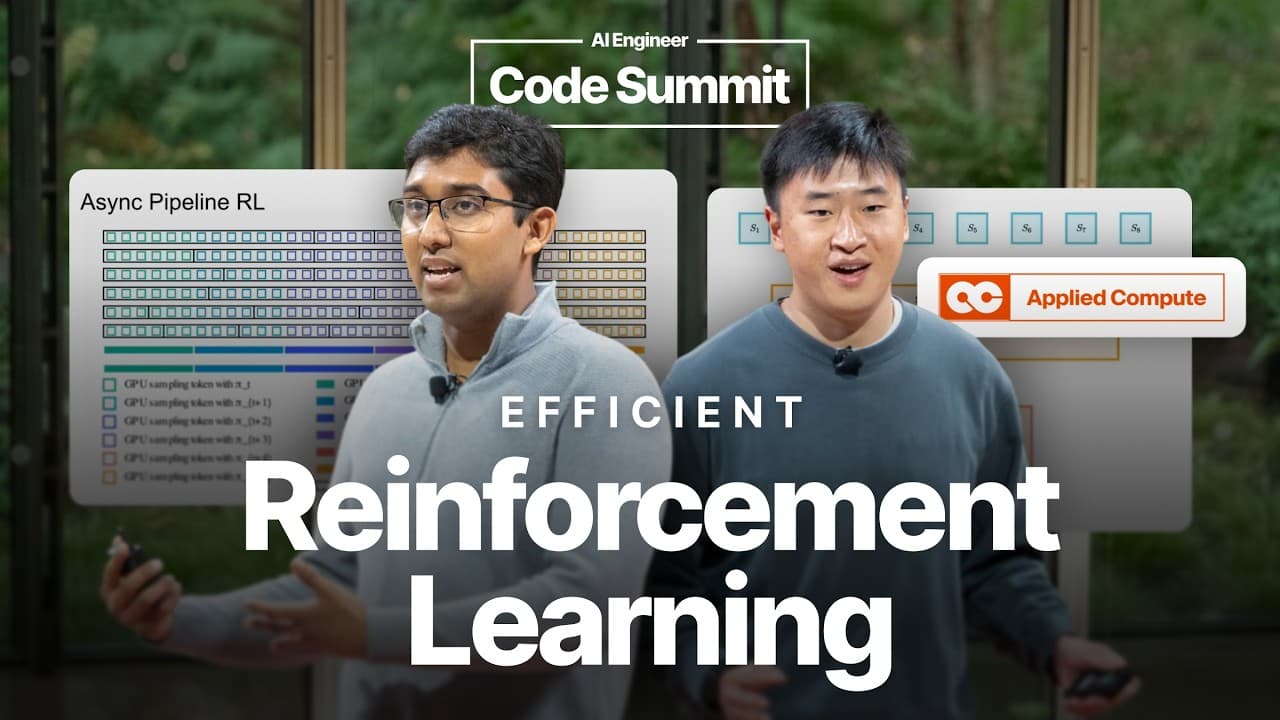
Asynchronous pipeline RL makes reinforcement learning faster and cheaper by assigning separate GPUs to continuous sampling and training instead of waiting for the slowest sample. In Applied Compute’s test, 99% of samples finished in about 40 seconds, while the last 1% required another 80 seconds. In-flight weight updates improve utilization but introduce staleness that can destabilize learning, making the full tradeoff worth reading on for.
Transcript
Hey everyone, it's great to meet you all. Really great to be here today. My name is Rhythm. This is my co-founder Lyndon. Our third co-founder, Yash, couldn't make it today, but we're all very excited to be here. Um, three of us were previously researchers at OpenAI, and now we're bringing Frontier AI inside of enterprise at applied compute. Today,... Read More
Key Insights
- Reinforcement learning at Applied Compute works by sampling batches of problems (e.g. four math problems), having an open-source model like GPT-OSS or Llama attempt each 100 times, grading the answers, then reinforcing weights on correct reasoning traces and discouraging incorrect ones.
- Synchronous RL is inefficient because sampling and training happen in lock step, so the whole batch waits for the slowest straggler sample, leaving many GPUs idle until that last completion.
- The long-tail problem is measurable: across 40 arithmetic problems with 32 samples each on Qwen 30B, 99% of samples finished in about 40 seconds but the final 1% took another 80 seconds to complete.
- Asynchronous RL breaks the lock-step condition by allowing training to happen while sampling continues, which keeps GPUs from slacking during the sampling tail.
- Pipeline RL dedicates some GPUs to sampling and some to training; sampling workers never stop, completed samples enter a training queue, and after each train step new weights propagate to all sampling workers via an in-flight weight update.
- In-flight weight updates create stale tokens: a single sample can be generated by multiple policy versions (t, t+1, t+2), so when trained on later it mixes tokens from policies several steps behind the current one.
- Tolerating more staleness reduces idle GPUs, but the policy gradient uses an importance ratio to stay unbiased, and that ratio's variance grows with staleness, making learning unstable and risking divergence.
- Applied Compute's business needs RL runs that are fast (delivered in days), cheap enough for sustainable unit costs, and low-variance in duration so training is reliably fast, not just generally fast, for customers.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How can reinforcement learning be made fast and cheap?
Applied Compute uses asynchronous pipeline RL to let training continue while sampling is still underway. Separate sampling and training GPUs work continuously, reducing the idle time caused by slow samples and supporting runs that can be delivered to customers on the order of days.
Q: How does reinforcement learning train a language model to reason?
A training step can select four problems and have an open-source model attempt each one 100 times, producing reasoning trajectories and final answers. Correct answers reinforce the associated thinking traces, while incorrect answers discourage that behavior over repeated training steps.
Q: Why is synchronous reinforcement learning inefficient?
Synchronous RL performs sampling and training in lock step, so every sample in a batch must finish before training begins. Because the step lasts as long as the slowest sample, many GPUs become idle while waiting for stragglers.
Q: How severe is the long-tail sampling problem in synchronous RL?
Applied Compute tested 40 arithmetic problems with 32 samples per problem using Qwen 30B. About 99% of the samples completed in 40 seconds, but the remaining 1% required another 80 seconds, leaving GPUs underutilized near the end.
Q: How does asynchronous pipeline RL work?
Some GPUs are dedicated to sampling and others to training, while sampling workers continuously perform high-batch-size inference. Completed samples enter a queue, training workers pull batches from it, and updated weights are propagated back to the sampling workers after each training step.
Q: What are in-flight weight updates and stale tokens?
An in-flight weight update changes a sampling worker’s model weights while it may still be generating a sample. One sample can therefore contain tokens produced by policy versions t, t+1, and t+2, creating a mismatch when it is later used for training.
Q: What is the tradeoff when reinforcement learning tolerates more staleness?
Greater staleness tolerance reduces GPU idle time because sampling and training do not need to pause for each other. However, the variance of the policy gradient’s importance ratio grows with staleness, which can make learning unstable and cause divergence.
Q: Why does Applied Compute need reinforcement learning runs to be predictably fast?
Applied Compute aims to train and deliver specialized models to customers on the order of days. Runs must also be cheap enough for sustainable unit costs, and duration estimates must have low variance so delivery is reliably fast rather than merely fast on average.
Summary & Key Takeaways
-
Applied Compute, founded by three former OpenAI RL researchers, helps enterprises build specialized in-house intelligence that delivers quantitative ROI. RL is the mechanism they use to bring out-of-distribution datasets into distribution, teaching models to reason and excel at company-specific tasks, then deploying with a data flywheel that improves the system with continued use.
-
The RL mechanism samples a batch of problems, has an open-source model attempt each many times producing long reasoning trajectories, grades the final answers, and biases the model's weights to reinforce correct thinking traces while discouraging incorrect behavior. Synchronous RL does this in lock step, leaving GPUs idle as they wait on the slowest straggler sample to finish.
-
Asynchronous pipeline RL separates sampling and training GPUs, updating sampling-worker weights mid-sample so samples contain stale tokens from multiple policy versions. Higher staleness tolerance reduces idle GPUs but increases importance-ratio variance and instability, creating a core research tradeoff that the team models with first-principles systems analysis over GPU count, batch size, and sampling throughput.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Engineer 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator