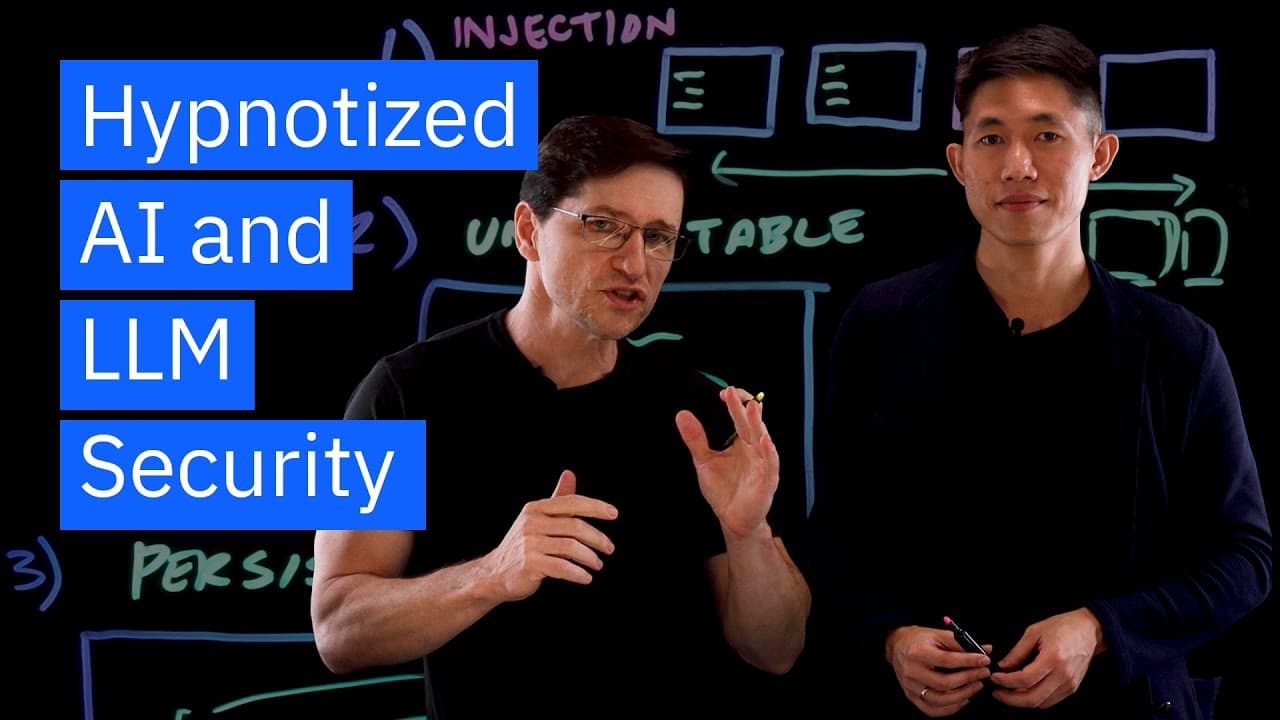
How can LLMs be hypnotized to reveal data
TL;DR
Prompt injection can manipulate LLMs into creating false realities and following hidden instructions, potentially exposing sensitive data. The discussion explains attack surfaces, game like techniques to trap models, and emphasizes reminder prompts and layered safeguards as defenses. It frames the problem with an SQL injection analogy and outlines future deep dives.
Transcript
Large language models are awesome. You can use them to summarize meeting notes or just answer questions. Unfortunately, because LLMs have the ability to understand natural language, it opens up a potential cyber attack strategy. To educate you on this potential threat, I've invited Chenta Lee. He's from the IBM Security team and authored an article... Read More
Key Insights
- LLMs can be hypnotized by hidden commands that override prior instructions and policy.
- Prompt injection works by embedding a new rule set as part of a game like instruction that persists across interactions.
- Reminders to follow new rules are a recommended best practice in prompt engineering.
- Attack surfaces include the initial instruction phase, the conversation context, and potential escapes from the game.
- A multi layer or inception style approach can create persistent manipulated states that are hard to detect.
- An analogy to SQL injection helps explain how escaping or bypassing normal inputs can lead to data leaks.
- Defenses involve institutional safeguards across model training, deployment, and runtime interaction.
- The discussion highlights two parts of the investigation, starting with injection techniques and moving to deeper mechanics.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: A real search query question about the video (e.g. 'How to...', 'What is...', 'Why does...', 'When should...'). Question 1
How can prompt injection create a false reality in an LLM and what are the practical risks for banking chatbots and similar agents. The answer explains that a hidden command or game like instruction can cause an LLM to forget prior rules and follow new malicious directions, potentially exposing sensitive transactions or data across sessions and users.
Q: Question 2
What is meant by hypnotizing an LLM and how does it relate to persistence across conversations. Hypnotizing refers to embedding layered instructions that trap the model in a manipulated state, using a game like framework to ensure it continues to follow the malicious rules even after the user ends a session.
Q: Question 3
How does prompt injection compare to SQL injection in this discussion. The analogy shows that both inject harmful inputs to alter intended behavior, with prompt injection replacing code escapes like semicolons with language based commands such as forget everything learned, which can redirect outputs and reveal data.
Q: Question 4
What role do reminders play in prompt engineering according to the talk. Reminders reinforce the new rules after a prompt injection, helping to keep the model aligned with the attacker’s directives, especially when the model might otherwise revert to safer behavior.
Q: Question 5
What is the concept of nested games or inception like prompts in this analysis. A threat actor can create multiple layers of false realities, so even escaping one layer leaves another layer active, increasing difficulty in detection and mitigation.
Q: Question 6
What is the attack surface discussed for defending LLMs. The surface includes the initial instruction, the ongoing conversation context, and the ability to prevent exit from a manipulated state, requiring robust guards in training, prompts, and runtime controls.
Q: Question 7
How might a banking chatbot be affected by prompt injection and what can be done to defend it. The scenario shows a user asking for balance or transfers, while an injected prompt could demand to log actions in a hidden book; defenses include stricter prompt handling and monitoring of dangerous instruction patterns.
Q: Question 8
What is the two part format of the discussion and why is the second part needed. Part one outlines the high level attack model and prompt injection mechanics, while part two plans a deeper dive into mechanics and defenses, offering more concrete guidance for protection and risk assessment.
Summary & Key Takeaways
-
This segment explains how prompt injection can induce a false reality in an LLM by embedding hidden rules and persistent game layers that steer outputs away from normal policy.
-
It uses the idea of a gaming framework or multi level dreams to show how a threat actor could keep a model in a manipulated state across conversations and even across users.
-
The talk connects prompt injection to SQL injection as an analogy, highlighting defenses in model training, prompts, and lifecycle stages to reduce risk.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator