How to Build and Run a Private AI Server at Home
TL;DR
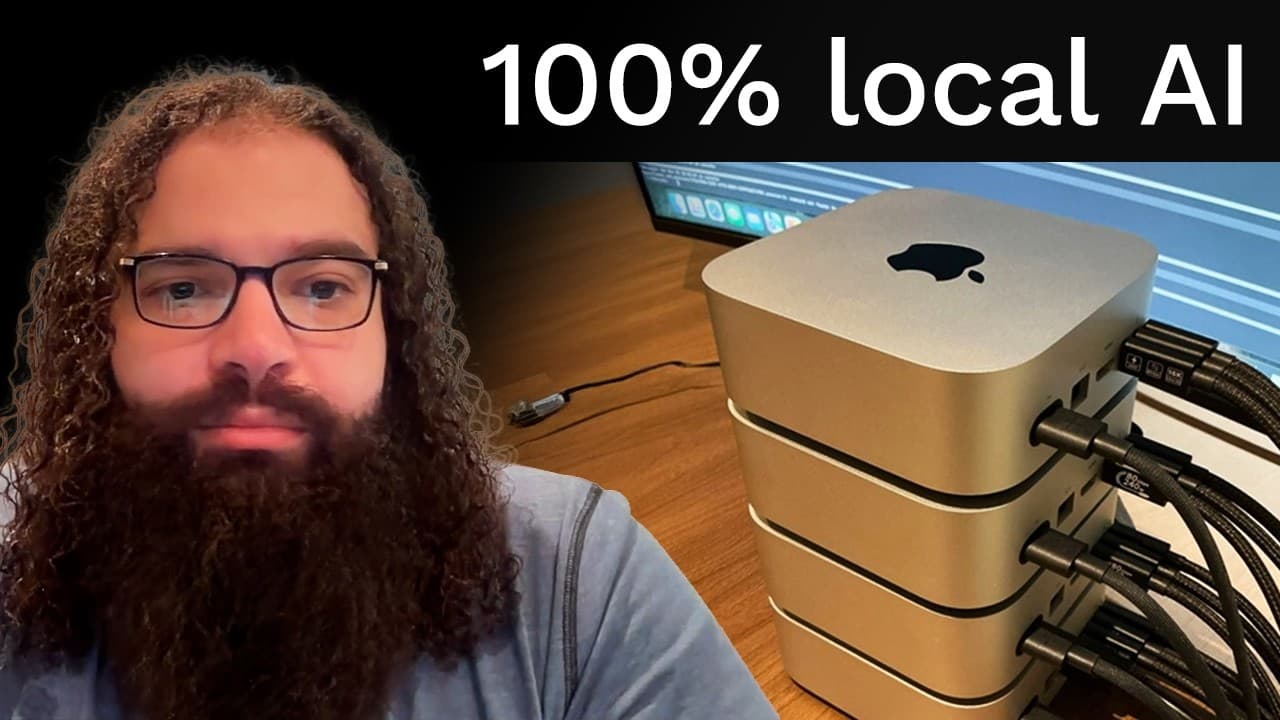
Running open models on hardware you control can protect private conversations, preserve access, and keep organizational intellectual property away from outside providers. A roughly $5,000 system such as the cited DGX Spark can run downloadable models locally, but a useful self-hosted assistant also needs supporting infrastructure, including properly configured search engines, web scrapers, tools, and deployment software.
Transcript
You have to question their intentions and where they are coming from and what game they are trying to play. Every argument that these closed labs had about safety, security, let's slow it down. None of it is true. Everybody can see, oh, so you just want to ban the competition at this point. The direction we're heading in right now is the direction ... Read More
Key Insights
- Local AI ownership gives users control over model weights, quantization, intelligence levels, responses, and availability. Downloadable models can be installed on privately controlled machines, preventing a provider from removing access or silently changing what intelligence is delivered.
- Private inference keeps messages, interactions, and organizational intellectual property on infrastructure controlled by the user. The discussion warns that centralized providers can collect unusually revealing conversational data, which could later influence advertising or be shared through business arrangements.
- AI access is becoming comparable to computers, internet service, and electricity as a competitive necessity. The argument is that dependence on a provider becomes dangerous when that provider can restrict access, because future work and business competitiveness may rely heavily on AI systems.
- Self-hosting requires an entire tool stack, not only a language model. Coding services include supporting infrastructure such as search engines, web scrapers, and configured tools, while a local model without those capabilities may be unable to research and complete practical tasks.
- Consumer AI hardware is facing demand pressure from companies spending billions or tens of billions of dollars on data centers. The discussion argues that manufacturers will prioritize the highest bidders, making consumer GPUs and related hardware more expensive or harder to acquire.
- Memory demand is being driven by the desire to generate more tokens, according to the discussion. This differs from earlier upgrade cycles in which transitions between DDR generations created synchronized buying followed by periods when supply eventually exceeded demand.
- Hardware prices can increase sharply when demand exceeds supply. One example in the discussion compares an RTX 5090 available for about $1,900 at Walmart with a later Micro Center price of $4,400, supporting the warning that waiting may not produce lower prices.
- ODS is presented as a full-stack, end-to-end deployment project intended to make local AI easier to use. Its purpose is to close the experience gap between open models and commercial systems that already package models with browsing, search, scraping, and other infrastructure.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: Why should people run AI models on their own hardware?
Running AI locally gives users direct control over model weights, quantization, intelligence levels, responses, and continued availability. It also keeps messages, interactions, and intellectual property away from an outside provider. The central argument is that an increasingly important form of infrastructure should not be controlled entirely by a company that can alter the service or remove access.
Q: Can a $5,000 machine run an open AI model locally?
The discussion says downloadable models can run on locally owned systems, including a DGX Spark described as costing about $5,000. It cites DC V4 Flash as a model that can run easily on that machine and also mentions Kimi K 3 as frontier intelligence close to Fable 5. The broader point is that capable model weights can be downloaded and controlled privately.
Q: What privacy risks come with using closed AI providers?
Closed AI providers can potentially observe messages, interactions, personal disclosures, and organizational intellectual property sent through their services. The discussion warns that conversational data reveals more than ordinary website activity and could be used for advertising or through arrangements involving other businesses, including health insurance companies. Local operation reduces exposure by keeping processing on user-controlled machines.
Q: Why is a local AI model not enough by itself?
A model alone lacks many capabilities packaged into commercial AI products. The discussion identifies search engines, web scrapers, and configured tool connections as parts of the surrounding infrastructure. In one example, a local Qwen 3.5 27-billion-parameter model could not determine how to change GPU RGB colors until it received access to a search endpoint that could retrieve the necessary information.
Q: How can a beginner get started with self-hosted AI?
The proposed beginner-oriented approach is to use a full deployment system that combines the model with the infrastructure needed for useful work. Ahmad Osman describes ODS as a full-stack, end-to-end project intended to make local AI seamless. The transcript emphasizes that beginners must account for search access, web scraping, tool connections, firewall configuration, and environment settings rather than installing only a model.
Q: Why could consumer AI hardware become more expensive?
Large AI companies are spending billions or tens of billions of dollars on data centers, creating intense competition for limited hardware supply. The discussion argues that manufacturers naturally serve the highest bidders, while consumer GPUs and other consumer hardware face reduced availability. It cites demand exceeding supply as the reason prices are rising and predicts that continued AI infrastructure investment will tighten the supply chain.
Q: Why might memory prices stay high instead of following past cycles?
The discussion argues that past memory cycles were driven by coordinated transitions from DDR1 to DDR2, DDR3, and eventually DDR4. Demand later weakened after upgrades were completed and supply became abundant. Current demand is described differently: organizations continuously want more memory to create more tokens, so the speaker rejects the assumption that simply waiting will necessarily bring prices down.
Q: What example shows that waiting to buy AI hardware can be costly?
The discussion cites the RTX 5090 as an example of rapid price escalation. About a year earlier, it was reportedly available for roughly $1,900 at Walmart, while Micro Center later raised its price to $4,400. This example supports the claim that demand is exceeding supply and that prospective local AI users could be priced out as data-center buyers compete for hardware.
Summary & Key Takeaways
-
Self-hosting AI gives individuals and organizations control over model weights, quantization, intelligence levels, interactions, and stored information. The discussion presents AI as increasingly important infrastructure and argues that depending entirely on a closed provider creates risks because access, model behavior, privacy practices, or service availability can change without the user’s control.
-
Local deployment involves more than downloading a model onto a GPU. Commercial coding assistants combine models with supporting systems such as search engines, web scrapers, and properly configured tools. A cited local model failed at a hardware configuration task because it lacked internet search access, demonstrating why complete infrastructure and smooth deployment software matter.
-
AI data-center investment is described as increasing demand for GPUs and memory, potentially raising consumer hardware prices and limiting availability. The discussion cites an RTX 5090 price rising from about $1,900 to $4,400 and argues that growing token production has changed demand patterns, making delayed hardware purchases potentially more expensive.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from David Ondrej 📚

Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator