What Is RAG and Why Is It a Profitable AI Skill?
TL;DR
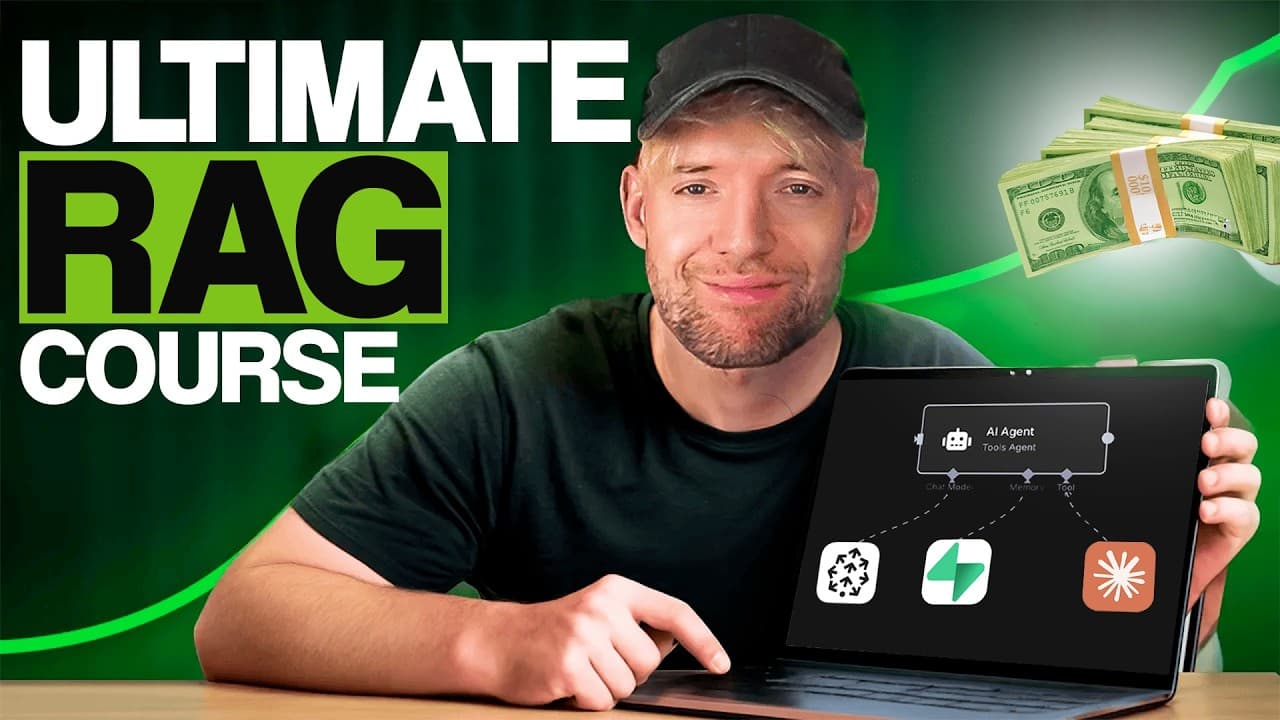
RAG (retrieval augmented generation) gives AI a reliable memory by storing your data as searchable chunks and pulling only the most relevant pieces to answer a question. It solves the hallucination and limited context-window problems, is far cheaper than fine-tuning, and can be applied to almost any data a business owns.
Transcript
Welcome to the most comprehensive rag masterass on YouTube, where I'm going to take you from beginner to expert. I've sold rag systems to so many companies, I even flew out to New York to compete in NA10's first ever rag agent competition. I'm going to take you from theory to actual business systems that make money. We're going to cover the best ra... Read More
Key Insights
- RAG stands for retrieval augmented generation: when asked a question, the system retrieves relevant information, augments the query with it, and then generates a smarter, more grounded response rather than relying on memory alone.
- The core problem RAG solves is memory and hallucination: language models can sound confident while giving false information, and you cannot easily tell when they are retrieving accurately versus fabricating an answer.
- RAG is cheaper and more accessible than fine-tuning, which requires training a model on specific data at significant cost, making RAG the more practical way to give a company's data to an AI.
- A context window is the limited amount of conversation and data a model can hold at once, which is why simply pasting large amounts of context into a chatbot becomes unreliable for accurate retrieval and citation.
- Vectorization is how RAG stores data: documents are chopped into chunks, and each chunk is converted by an embedding model into a long numeric code called an embedding that acts as a unique identifier.
- Retrieval works by similarity: the same embedding model turns your question into a comparable number, and the system pulls back the chunks whose embeddings are most relevant to that question.
- A RAG system has three parts working together: an agent that receives instructions, a knowledge base where vectorized information is stored, and a memory layer used to access that stored data.
- You can apply RAG to almost any data source, including PDFs, Word documents, contracts, spreadsheets, databases, websites, emails, meetings, books, YouTube, and podcasts, which is why it has near-infinite business applications.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What does RAG stand for and what does it actually do?
RAG stands for retrieval augmented generation. In simple terms it is an AI that remembers, learns, and responds smarter. When you ask it a question, it first retrieves relevant information from a stored knowledge base, augments the question with that information, and then generates a better, more grounded response. Rather than depending only on what the model already knows, it looks up the right material first so the answer is more accurate and can be traced back to a source.
Q: Why is RAG considered a profitable AI skill to learn?
The video argues RAG is profitable because almost anything you do with AI involves data, and RAG sits at the center of that data. Businesses of every size need AI systems that can control and accurately use their own information, and RAG systems are a frequent, sellable request for agencies. It can save businesses large amounts of time and even unlock entirely new product categories, which in turn create new revenue streams, making it a high-value skill for both business owners and agencies.
Q: How does RAG solve the hallucination and memory problem?
The memory problem is that a very capable model can hold high intelligence yet fail to reliably retain the specific information you gave it, and it may state false information confidently without signaling when it is wrong. Hallucinations can be costly or even illegal in sectors like healthcare and medicine where accuracy is essential. RAG is described as the strongest defense because it retrieves grounded information from a stored knowledge base, giving you more confidence that the answer is based on real, retrievable source material.
Q: Why can't you just rely on a language model's context window instead of RAG?
Every model has a context window, meaning the entire conversation is passed through each time and only a limited amount can be held. Google's Gemini, for example, has a very large context window measured in tokens, so early on people simply pasted in lots of context. But when you need to retrieve information reliably, cite sources, or work with more data than fits, context alone becomes insufficient. You also cannot tell when the model hallucinates, so raw context does not give the accuracy and confidence that RAG provides.
Q: What is vectorization and how does it store information for RAG?
Vectorization is how RAG prepares data for retrieval. The AI takes a document, such as a book, and chops it into chunks, for example groups of pages. Each chunk is then passed through an embedding model that converts it into a very long number called an embedding, which serves as a unique code identifier for that piece of information. These embeddings are stored in a vector database, so instead of storing raw text, the system stores numeric representations that can later be compared and searched efficiently.
Q: How does RAG retrieve the right information when you ask a question?
When you ask a question, RAG uses the same embedding model that vectorized the stored data to convert your question into a similar numeric representation. It then compares that number against the stored embeddings and pulls back the most relevant chunks of information. The video illustrates this with a secretary who, when asked about a recruitment policy, walks to the bookcase and grabs only the most relevant books on recruitment and brings them back, delivering targeted, relevant context rather than everything at once.
Q: What are the main components of a RAG system?
A RAG system has three parts working together. First is the agent, described as the office or the person you give instructions to, which handles the questions. Second is the knowledge base, where information is stored and vectorized. Third is the memory layer, which is how the system actually accesses and retrieves that stored information. In a no-code platform like n8n, this appears as an agent connected through a chat window to a RAG database it can reach into for retrieval.
Q: What types of data can you use RAG with?
According to the video, you can apply RAG to almost any information imaginable. Named examples include PDFs, Word documents, databases, contracts, Excel spreadsheets, phone conversations, the internet and websites, books, YouTube, podcasts, emails, and meetings. Because it is one framework with nearly infinite applications, it can be involved in real estate operations, education, tracking and retrieving data, and countless other use cases. This flexibility is a major reason the video positions RAG as central to almost any AI project a business might build.
Summary & Key Takeaways
-
RAG is presented as the most profitable AI skill to learn because businesses increasingly need AI systems that can use their own data accurately. The global AI market is growing rapidly, and companies across healthcare, real estate, education, and more require accuracy that generic chatbots cannot reliably provide.
-
The central issue is the memory problem: a highly capable model can hallucinate and give false information without signaling when it is wrong, which is costly or even illegal in sensitive sectors. RAG is described as the strongest defense against this, and it is cheaper than fine-tuning a model.
-
Technically, RAG chunks documents, vectorizes each chunk into an embedding via an embedding model, and stores them in a vector database. A question is embedded the same way and used to retrieve the most relevant chunks, illustrated through analogies of a librarian, an indexing card, and a secretary fetching the right books.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Jack Roberts 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator