How to streamline data CI/CD for AI pipelines
TL;DR
CI/CD automates testing, packaging, and deployment of data pipelines, reducing manual work and risk. It enforces standardized, automated processes across environments, improves quality through testing, and enables selective promotion of reliable changes to staging and production, delivering data and AI workloads faster with confidence.
Transcript
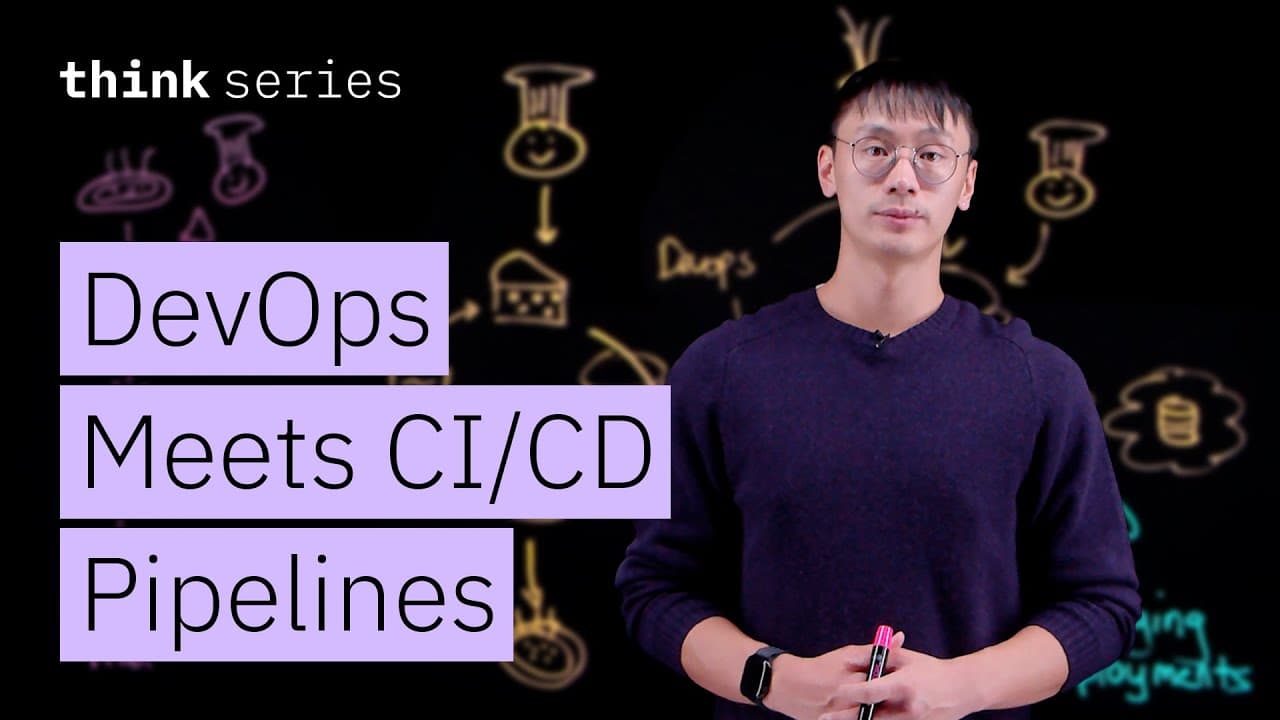
Imagine your data engineering development lifecycle is like a Michelin-starred restaurant kitchen. The process to source, cook, and deliver the food mirrors a well-oiled DevOps cycle. DevOps is the approach that automates, streamlines and the, the, delivery, development and monitoring of applications, enabling faster releases, higher quality and mo... Read More
Key Insights
- CI/CD in data engineering speeds releases by automating testing, validation, and deployment across environments.
- QA checks include unit testing, compliance testing, and source control management to maintain data quality and regulatory adherence.
- Selective promotion ensures only validated code moves to higher environments, reducing risk and enhancing reliability.
- Automated credential management between environments eliminates manual credential handling and misconfigurations.
- Batch data integration benefits from CI/CD by validating schema, joins, and transformed outputs automatically.
- Automations can adjust databases and credentials across environments to mirror production settings safely.
- Deployment is tracked and linked back to the initiating user for accountability and traceability.
- The kitchen metaphor illustrates how DevOps practices translate into faster, safer data workflows.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How does CI/CD improve data pipeline reliability?
CI/CD improves data pipeline reliability by enforcing automated testing and validation at each stage and by standardizing processes across environments. Unit tests catch component issues early, compliance tests ensure governance, and source control tracks changes, all of which reduce variability and help teams deliver consistent, high quality data outputs.
Q: What is selective promotion in CI/CD for data pipelines?
Selective promotion means only changes that pass validation tests are moved to higher environments. This reduces the risk of deploying unstable or unverified data changes, ensuring that staging and production contain code and data that have already met quality checks, which improves overall pipeline stability and reliability.
Q: Why is environment parity important in CI/CD for data work?
Environment parity ensures that tests and validations reflect production conditions. By automatically adjusting database credentials and configurations between environments, the pipeline minimizes discrepancies, prevents configuration drift, and ensures that what works in development will work in production, reducing deployment failures.
Q: How are credentials handled in this CI/CD approach?
Credentials are automatically adjusted between environments so production level credentials replace development ones as changes move through the pipeline. This automation minimizes manual handling, lowers the chance of credential leakage, and keeps access controls aligned with security policies across all stages.
Q: What role does version control play in the data CI/CD workflow?
Version control and Git integration automate tracking of changes, enable rollback if needed, and provide a clear history of who changed what and when. This supports collaboration, traceability, and compliance, making it easier to audit data and code alterations across the pipeline.
Q: How does CI/CD impact data pipeline delivery speed?
CI/CD reduces manual steps and automates testing, packaging, and deployment, which accelerates the release cycle. By removing bottlenecks and enabling automated checks, teams can push validated changes through environments more quickly, increasing overall throughput without sacrificing quality.
Q: What is the analogy used to explain DevOps in data engineering?
The video uses a Michelin star kitchen analogy where chefs prepare dishes, tests check quality, and plating corresponds to deployment. This helps illustrate how CI/CD standardizes processes, automates checks, and streams data pipeline delivery from development to production with quality and speed.
Q: What benefits does automated testing bring to batch data pipelines?
Automated testing in batch data pipelines checks schema conformity, join correctness, and transformed outputs, ensuring data integrity before promotion. It helps catch errors early, enforces data quality standards, and reduces risk by validating outputs against expectations prior to deployment to downstream systems.
Summary & Key Takeaways
-
CI/CD is framed as a kitchen style pipeline where automated checks verify ingredients and recipes before plating, ensuring consistency and quality. The approach reduces manual effort and mistakes by standardizing processes and testing at every stage.
-
Selective promotion is used to move only validated changes through environments, preventing risky deployments and aligning with production readiness. This concept helps manage complex data pipeline changes across environments.
-
Deployment tracking ties each change to the user who made it, ensuring traceability and accountability in the data and code base and supporting audits and compliance.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator