How to Scrape Unlimited Google Maps Leads and Emails With n8n Without Paid APIs (99% Free)
TL;DR
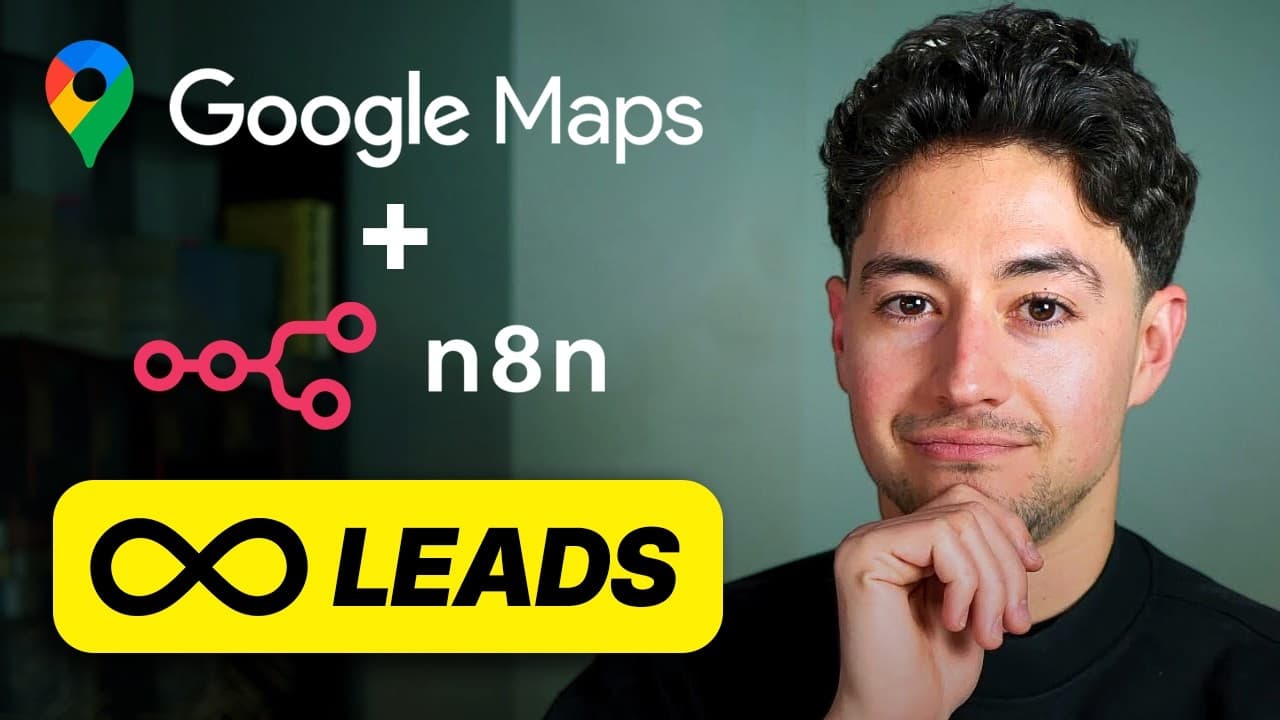
You can scrape Google Maps emails with n8n by requesting a formatted Maps search URL, extracting business websites, filtering unwanted links, removing duplicates, and visiting the remaining sites for email addresses. The demonstrated workflow takes searches from Google Sheets and writes eight test results to an emails sheet without a third-party API. Read on for the exact nodes, query format, and processing sequence.
Transcript
hey today I'm building a simple system in NAD that lets you scrape emails from Google Maps completely free without needing any thirdparty APIs that's right we're going to do it entirely in NAND and what I'll do first is demo the flow before then showing you guys how to build it on your own from scratch you guys can find the templates in the descrip... Read More
Key Insights
- The workflow is an n8n system that collects email addresses associated with Google Maps listings without requiring a paid third-party API. It uses HTTP requests, small JavaScript transformations, filters, duplicate removal, looping, and Google Sheets to move from a search query to an email list.
- A Google Maps search URL is created by inserting a business category and location into the URL. Spaces in the query are replaced with plus signs, so the example Calgary dentist search is represented as Calgary plus dentist before being submitted through the workflow.
- The HTTP Request node retrieves a large response containing data from the Google Maps search page. Its options are configured to ignore SSL issues and include response headers and status, giving the following code node the material needed to locate embedded website links.
- The URL extraction step uses JavaScript and a global regular expression to match website addresses inside the response. The transcript presents this as a short reusable code snippet and notes that AI can help produce this kind of transformation without requiring extensive programming knowledge.
- The n8n input structure represents data from previous nodes as an array of items. Even when a node returns only one item, the code selects the first array element and accesses its JSON data before applying the regular expression.
- The extracted URLs must be returned in the item format expected by n8n. A JavaScript map operation converts each matched website into a separately nested JSON object, allowing later workflow nodes to filter and process every address as an individual item.
- The raw URL list contains many irrelevant domains in addition to business websites. The demonstrated filter uses string conditions such as does not contain to exclude links containing schema, Google, GG, and Gstatic while retaining likely dental business domains.
- The completed flow can accept search terms from one Google Sheet and deposit extracted emails into another. The demonstration returns eight items from a limited test, while the presenter says larger runs can use more search terms and a higher limit to process many listings.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How can I scrape emails from Google Maps with n8n for free?
Send an HTTP request from n8n to a Google Maps search URL containing a location and business category. Extract website URLs from the response, filter unwanted domains, remove duplicates, loop through the remaining sites, and use code to collect email addresses. The workflow can then write those addresses to Google Sheets without using a paid third-party API.
Q: How should I format a Google Maps search query for the workflow?
Insert the location and business category into the Google Maps search URL and replace spaces in the query with plus signs. The demonstration uses Calgary plus dentist to retrieve Google Maps listings for Calgary dentists.
Q: What does the n8n HTTP Request node retrieve from Google Maps?
The node submits the formatted Maps search URL and receives a large response described as essentially HTML. That response contains links that can be extracted and used for additional HTTP requests to business websites. The demonstrated options ignore SSL issues and include the response headers and status.
Q: How does the n8n Code node extract website URLs?
The Code node stores the incoming response in a JavaScript input variable and uses a global regular expression to match website URLs. A map operation then converts each match into the JSON item structure expected by n8n, allowing downstream nodes to process the URLs separately.
Q: Why does the JavaScript select the first n8n input item?
n8n returns data from previous nodes as an array of items, even when the preceding node produces only one item. The code therefore selects the first array element and accesses its JSON data before searching the response for website URLs.
Q: How are irrelevant URLs removed from the Google Maps results?
Place Filter nodes after the URL-extraction step and use string conditions such as does not contain. The demonstrated filters exclude links containing schema, Google, GG, and Gstatic, leaving more relevant business websites for email extraction.
Q: How are duplicates and processing limits handled in the workflow?
The completed flow performs filtering, duplicate removal, and limiting before starting its email-extraction loop. The presenter uses a small limit for testing, but says it can be increased and supplied with more search terms to run across tens of thousands of Google Maps listings.
Q: How do Google Sheets connect to the n8n lead-scraping workflow?
The example spreadsheet has two sheets named searches and emails, with one column in each. The searches sheet supplies queries such as Calgary plus dentist, while the workflow deposits extracted email addresses into the emails sheet. The test run produced eight items.
Summary & Key Takeaways
-
The workflow begins with a Google Maps search query formatted inside a search URL, such as Calgary plus dentist. An n8n HTTP Request node retrieves the search response, including its headers and status. For a simple demonstration, the workflow can start with a manual trigger before Google Sheets input is connected.
-
A code node processes the returned data as the first item in n8n's array-based output structure. JavaScript stores the response in an input variable, applies a global regular expression to find URLs, and maps every extracted website into the JSON structure that n8n expects for separate workflow items.
-
The extracted links include relevant business websites alongside unwanted Google, schema, Gstatic, and other domains. Filter nodes progressively remove irrelevant results. The larger demonstrated workflow also removes duplicates, limits records for testing, loops through selected websites, extracts email addresses with code, and deposits the final results into a Google Sheet.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Nick Saraev 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator