How to Build and Model a Data Warehouse
TL;DR
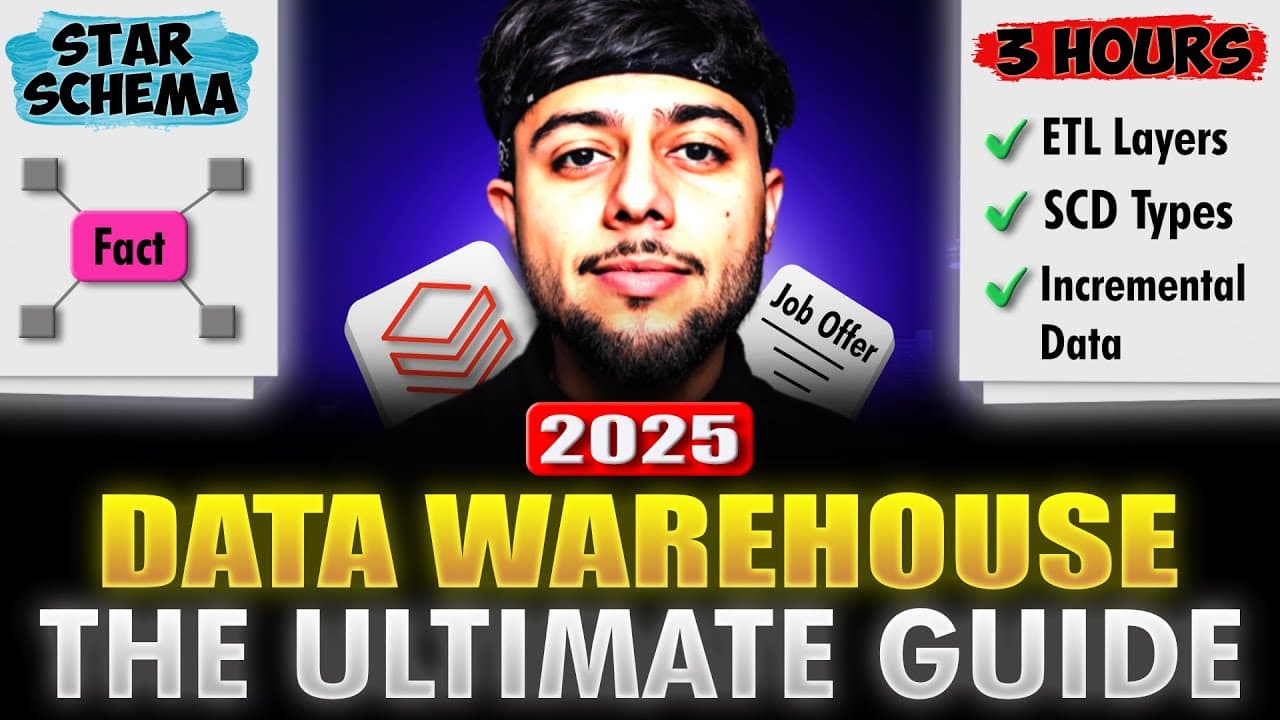
A data warehouse is a central repository that stores an organization’s information, including sales, transactions, budgets, marketing, and HR data. Building one requires understanding ETL layers, incremental loading, dimensional modeling, fact and dimension tables, schema design, and slowly changing dimensions, followed by practical implementation with Databricks and Spark SQL.
Transcript
the demand for data Engineers is growing rapidly and you need to master the skill to actually crack the interviews I'm not talking about Cloud because even Cloud developers fail in this area I talking about data warehousing so in this 3 hours long video you will learn everything related to data warehousing from scratch including ETL layers in data ... Read More
Key Insights
- A data warehouse is a central repository where an organization stores information from multiple business areas, including transactions, sales, budgets, marketing, and HR. It provides a central place for examining the total collection of data held by the organization.
- A database and a data warehouse can both be stored or managed through systems such as MySQL, PostgreSQL, or Microsoft SQL Server. The stated distinction is not the application name, but how data is stored, organized, and moved within each architecture.
- Data warehousing is presented as a fundamental skill for data engineers because it applies across Azure, AWS, Google Cloud, on-premises systems, and cloud environments. The course also identifies warehousing and data modeling as areas where candidates may struggle during interviews.
- ETL layers provide part of the architecture needed to move and organize warehouse data. The course places these layers after its introduction to data warehousing and before incremental loading, establishing them as a bridge between foundational concepts and practical data-loading techniques.
- Incremental data loading is taught both conceptually and through a Spark SQL implementation. The broader list of covered loading methods includes change data capture and timestamp-based approaches, while Databricks provides the environment used for the practical demonstration.
- Dimensional data modeling organizes warehouse designs around fact tables and dimension tables. The course introduces data modeling first, then dimensional modeling, and subsequently shows how to create the corresponding tables through practical Spark SQL work.
- Star and snowflake schemas are alternative dimensional modeling structures covered in a direct comparison. Their placement after fact and dimension table concepts indicates that understanding those table types is necessary before examining the two schema designs.
- Slowly changing dimensions address changes affecting dimension data and are covered through multiple types. The practical portion specifically implements SCD Type 1 in Databricks with Spark SQL, connecting the conceptual discussion to executable warehouse-building work.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is a data warehouse?
A data warehouse is a central location or repository where an organization stores its information. The examples provided include transactional data, sales data, budget information, marketing data, and HR data. It functions like a central hub containing many kinds of organizational records, allowing the organization to track the total collection of data it currently holds.
Q: What is the difference between a database and a data warehouse?
The difference is not necessarily the software used to hold the data. MySQL, PostgreSQL, and Microsoft SQL Server are described as database management systems, and a data warehouse can also be stored in such an environment. The important distinction concerns how data is stored and how it is moved within the database or warehouse architecture, with databases associated with transactional storage.
Q: Why should data engineers study data warehousing?
Data warehousing is presented as one of the most important areas of data engineering because it appears across different platforms and deployment environments. The same underlying knowledge remains relevant when working with Azure, AWS, Google Cloud, on-premises infrastructure, or cloud systems. Warehousing and data modeling are also identified as topics that can challenge candidates during data engineering interviews.
Q: How is incremental data loading implemented in the course?
Incremental data loading is introduced as a core data warehousing topic and then implemented using Spark SQL. The course first explains warehousing and ETL layers, covers incremental loading conceptually, introduces the Databricks environment, and then demonstrates the loading process there. Change data capture and timestamp-based loading are also named among the incremental loading subjects included in the material.
Q: What is dimensional data modeling in a data warehouse?
Dimensional data modeling is presented as a major stage of warehouse design based on fact tables and dimension tables. The course introduces general data modeling before moving into dimensional modeling, then explains the two table categories. It continues by comparing star and snowflake schemas and practically creating fact and dimension tables with Spark SQL in Databricks.
Q: What are fact tables and dimension tables used for?
Fact tables and dimension tables are the central table categories introduced for dimensional data modeling. The course teaches their concepts before discussing star and snowflake schemas, then demonstrates how to build them with Spark SQL. It also expands the subject through different fact table types and specialized dimensions, including degenerate, role-playing, and junk dimensions.
Q: What is covered in the star schema and snowflake schema comparison?
Star schema and snowflake schema are presented as two dimensional data modeling structures that should be studied after understanding fact and dimension tables. The course includes a dedicated comparison of the two, followed by practical construction of dimension and fact tables using Spark SQL. The supplied material does not provide the detailed structural differences discussed during that comparison.
Q: How are slowly changing dimensions implemented with Spark SQL?
Slowly changing dimensions are introduced after the lessons on fact table types and dimension table types. The course states that it covers all types of slowly changing dimensions and connects the theory with code. Its final practical section specifically implements SCD Type 1 in Databricks using Spark SQL, demonstrating how the concept is applied in a warehouse workflow.
Summary & Key Takeaways
-
A data warehouse serves as a central location for organizational data from areas such as sales, transactions, budgeting, marketing, and HR. Its distinction from a database is not simply the application used. The important differences concern how data is stored, organized, and moved through the respective architectures for analytical or transactional purposes.
-
The course progresses from foundational definitions into data warehousing architecture, ETL layers, and incremental data loading. It then introduces Databricks and demonstrates incremental loading with Spark SQL. The practical emphasis is intended to connect conceptual explanations with the actual construction of warehouse components using current data engineering tools and technologies.
-
Dimensional data modeling forms the later portion of the course, including fact tables, dimension tables, star schemas, snowflake schemas, and their Spark SQL implementation. The material also covers transactional and periodic fact tables, degenerate, role-playing, and junk dimensions, slowly changing dimension types, and an implementation of SCD Type 1 in Databricks.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Ansh Lamba 📚

Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator