How to achieve deterministic LLMs with batch invariant inference
TL;DR
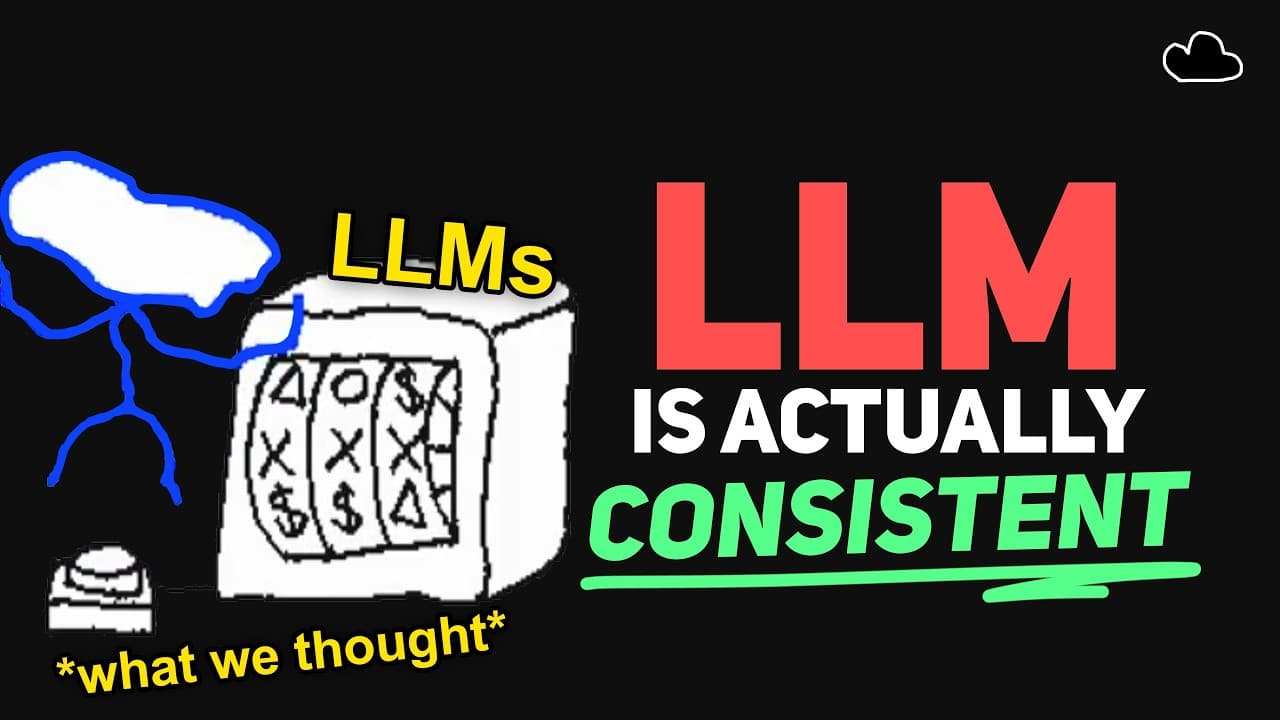
Determinism is achieved by fixing the reduction order in GPU kernels to prevent batch dependent rounding, not by temperature alone. Think Machines demonstrated that using batch invariant kernels makes outputs repeat across varying server load, though it may slow down inference. This approach also helps align training and inference by using consistent batching.
Transcript
When you are using AI chatbots, you might have seen this parameter that has a slider between zero and one called temperature. A common explanation for this parameter is that if you want the AI to be more creative, put it at one. And if you want it to have a more consistent answer, put it at zero. But what this does temperature value ultimately it t... Read More
Key Insights
- LLMs can be deterministic if kernel reduction order is fixed across batches.
- Batch invariant kernels remove variability arising from different batching strategies.
- Temperature zero alone does not guarantee identical outputs due to hardware and batching effects.
- Non determinism in LLMs arises from reduction order changes during GPU computations.
- Thinking Machines demonstrated that batch invariant inference yields identical results in 1000 completions under fixed conditions.
- Deterministic inference may incur speed penalties but improves reproducibility for evaluation.
- Batch invariant inference can help the RL update be on policy by matching training and inference setups.
- Batch invariant kernels can align inference and training stacks, reducing policy drift.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is batch invariant inference and why is it important?
Batch invariant inference is a method where the sampler uses consistent kernels regardless of how batches are formed during inference. It matters because it prevents changes in reduction order and numerical rounding that can lead to different tokens being selected in identical prompts. This yields reproducible outputs across varying server loads and batching scenarios, which is crucial for fair evaluation and stable policy updates.
Q: How does temperature affect determinism, according to the video?
Temperature alone does not guarantee determinism. Even with temperature set to zero, non deterministic behavior can emerge due to how requests are batched and how kernels adapt to different batch sizes. The key issue is reduction order and floating point rounding differences that can accumulate and change the final token selection, despite identical prompts.
Q: What experiment did Thinking Machines conduct to prove batch invariance?
Thinking Machines conducted an experiment on a prompt set involving Richard Feynman sampling with 1000 tokens and 1000 completions. They showed that using batch invariant kernels caused all 1000 completions to be identical, whereas standard batching produced 80 distinct completions with a first divergence at token 103. This demonstrated the impact of kernel reduction order on determinism.
Q: What trade off is involved with batch invariant inference?
The trade off is speed. Implementing batch invariant kernels for full determinism slows down inference by a factor roughly around 1.6 to 2.1 in the tested setup. This slowdown is a consequence of sticking to a fixed reduction order and avoiding the fastest, most adaptive kernel strategies in order to achieve reproducible results across batches.
Q: Why does non determinism matter for training and evaluation?
Non determinism matters because training and evaluation can drift apart when different batching strategies trigger different kernels and reduction orders. If the inference uses one set of kernels while training uses another, the model learns from a subtly different signal. Batch invariant inference helps ensure the policy being trained matches the policy used during sampling.
Q: How can batch invariant inference impact model performance beyond determinism?
Beyond determinism, batch invariant inference can unexpectedly improve training in some cases by aligning the inference and training stacks. By removing batch dependent variability, the RL updates can be more stable and on policy, potentially smoothing optimization and reducing off policy learning signals that arise from kernel diversity during sampling.
Q: What practical considerations accompany implementing batch invariant kernels?
Practical considerations include accepting slower inference, ensuring the same batching strategy is used across systems, and validating that the fixed reduction order does not excessively underutilize hardware. It also requires changes in the kernel scheduling and possibly alterations to the sampler to guarantee that all completions follow the same computational path under varying loads.
Q: What is the broader takeaway about LLM non determinism from the video?
The broader takeaway is that LLM non determinism is largely a product of interactions between batching requests, kernel strategies, and numerical reduction orders rather than pure GPU randomness. By making kernels batch invariant, researchers can achieve deterministic outputs that are reproducible for evaluation and more consistent across training and deployment environments.
Summary & Key Takeaways
-
Determinism in LLMs hinges on reducing batch variation in kernel strategies to ensure identical outputs across runs.
-
Batch invariant inference fixes kernel reduction order to prevent rounding differences that cause non-determinism.
-
This approach trades some speed for reproducible results, improving evaluation and policy alignment between training and inference.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from bycloud 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator