Is ASUS ProArt GR1X Fast Enough for Local AI?
TL;DR
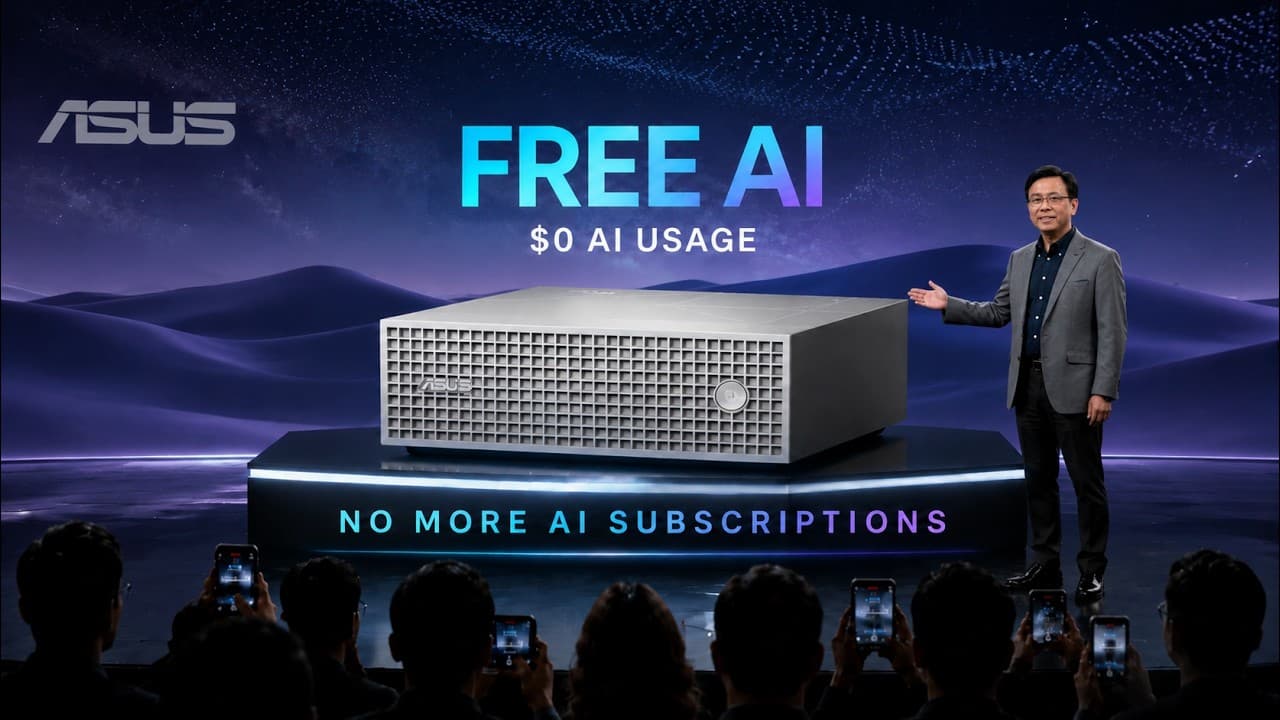
Memory bandwidth, not the advertised one-petaflop FP4 figure, will determine whether the ASUS ProArt GR1X runs large local models responsively. ASUS confirms 128 GB of unified memory, 6,144 CUDA cores, a 20-core Grace CPU, and roughly 140 watts of thermal headroom, but its unpublished bandwidth, price, and precise release date prevent a reliable verdict.
Transcript
There's a new AI mini PC with 128 gigs of unified memory and it's either a monster or a very expensive paper weight. The gap comes down to one number ASUS won't print. ASUS published the whole GR1X spec sheet and left out memory bandwidth. The line that decides whether a local model answers at reading speed or at slideshow speed. So, I'm grading th... Read More
Key Insights
- Memory bandwidth is the decisive specification for local language-model decoding because perceived generation speed is approximately bandwidth divided by the number of model bytes read per token. A machine can therefore have many CUDA cores yet remain slow when its memory system cannot move model weights quickly enough.
- The ASUS ProArt GR1X is confirmed to combine a 20-core Grace CPU with a Blackwell RTX GPU containing 6,144 CUDA cores and fifth-generation Tensor cores. ASUS also lists 128 GB of unified memory, 10-gigabit Ethernet, Gen 5 storage, and roughly 140 watts of thermal headroom.
- ASUS has not published the GR1X's memory bandwidth, price, or a release date more precise than fall. Earlier coverage suggested approximately 300 GB/s for the broader RTX Spark platform, but the source classifies that figure as possible rather than a confirmed specification for this computer.
- A 120-billion-parameter model quantized to four bits can behave very differently depending on bandwidth. Around 270 GB/s may produce faster-than-reading output, approximately 500 GB/s can feel responsive, while measured performance in the low 200s can turn long-context tasks into a much slower workflow.
- The advertised one-petaflop FP4 figure is based on sparse, best-case marketing math rather than ordinary dense workloads. On the related GB10 silicon, measured dense BF16 throughput was reported near 60 teraflops, showing why peak sparse FP4 claims should not be treated as everyday performance.
- Pre-production N1X laptop benchmarks are evidence about the silicon family, not direct measurements of the GR1X. The tested Surface Laptop Ultra has different thermal conditions, unfinished drivers, and only 64 GB of memory, while the GR1X is a desktop with roughly 140 watts of thermal headroom.
- The 20-core N1X engineering sample scored 2,570 single-core and 23,126 multi-core in Geekbench 7. An additional 18-core version with 5,120 CUDA cores scored 2,541 and 21,776, suggesting that multiple performance and pricing tiers may be planned.
- The competitive bandwidth figures show why capacity alone is insufficient. DGX Spark measured 273 GB/s, Strix Halo was rated at 256 GB/s but measured around 212–215 GB/s, M4 Pro offers 273 GB/s, M4 Max reaches 546 GB/s, and M3 Ultra reaches 819 GB/s.
- More videos from this channel:
- More from this channel: AI Master
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: Why does memory bandwidth matter for local AI inference?
Memory bandwidth largely controls the decode speed users experience while a local language model generates text. The source describes the relationship as memory bandwidth divided by the number of model bytes read per token. During this phase, the memory pipeline can be the bottleneck rather than the GPU's core count, so a powerful processor may still produce text slowly if model weights cannot move quickly enough.
Q: What specifications has ASUS confirmed for the ProArt GR1X?
ASUS confirms that the ProArt GR1X uses a Blackwell RTX GPU with 6,144 CUDA cores and fifth-generation Tensor cores for FP4 workloads. It pairs that GPU with a 20-core Grace CPU through NVLink C2C and includes 128 GB of unified memory. The published information also lists 10-gigabit Ethernet, Gen 5 storage, and an approximately 140-watt thermal design for sustained inference.
Q: Which important ProArt GR1X specifications remain unknown?
ASUS has not published the ProArt GR1X's memory bandwidth, price, or a release date more specific than fall. The missing bandwidth figure is especially important because it determines how quickly large local models can read their weights during decoding. A figure near 300 GB/s appeared in earlier RTX Spark coverage, but it applies to platform-level reporting and is not a confirmed GR1X specification.
Q: How fast could a 120-billion-parameter model run on the GR1X?
A reliable estimate is impossible until ASUS discloses memory bandwidth. The source says a 120-billion-parameter model quantized to four bits would answer somewhat faster than reading speed at around 270 GB/s. At roughly 500 GB/s, the same workload could feel responsive, while real measured bandwidth in the low 200s could make long-context work slow enough to resemble a coffee-break workflow.
Q: Is the advertised one-petaflop FP4 performance realistic?
The one-petaflop FP4 claim represents sparse, best-case marketing performance, not a measurement of typical dense workloads. The source compares it with sibling GB10 silicon, where measured dense BF16 throughput landed near 60 teraflops. These numbers use different precisions and assumptions, so they should not be presented as equivalent indicators of the performance users will experience during ordinary local AI inference.
Q: What do leaked N1X benchmarks reveal about performance?
A pre-production Surface Laptop Ultra engineering sample with 20 CPU cores and 6,144 CUDA cores scored 5,771 multi-core and 540 single-core in Cinebench 2026 while drawing around 50 watts. In Geekbench 7, a 20-core sample scored 2,570 single-core and 23,126 multi-core. These results suggest capable silicon, but they do not establish GR1X desktop performance.
Q: Why should N1X laptop benchmarks not be treated as GR1X results?
The leaked measurements came from a Microsoft Surface Laptop Ultra engineering sample running pre-production drivers, not from the ASUS desktop. The laptop operated under different thermal limits and included 64 GB of memory, while the GR1X offers 128 GB and approximately 140 watts of thermal headroom. Cinebench also misread the sample's clock, indicating that its tools did not fully understand the unfinished silicon.
Q: How does the GR1X compare with other local AI computers?
A definitive comparison is not possible without the GR1X's memory bandwidth. Available reference points include DGX Spark at a measured 273 GB/s, Strix Halo at 256 GB/s on paper and roughly 212–215 GB/s in testing, M4 Pro at 273 GB/s, M4 Max at 546 GB/s, and M3 Ultra at 819 GB/s. These figures define the range the GR1X must compete within.
Summary & Key Takeaways
-
The ASUS ProArt GR1X is a compact local AI computer built around NVIDIA's RTX Spark N1X platform. Confirmed specifications include a Blackwell RTX GPU with 6,144 CUDA cores, fifth-generation Tensor cores, a 20-core Grace CPU, 128 GB of unified memory, 10-gigabit Ethernet, Gen 5 storage, and roughly 140 watts of thermal headroom.
-
The decisive missing specification is memory bandwidth because local language-model decoding depends largely on how quickly model weights can move through memory. Comparable figures range from measured Strix Halo results of roughly 212–215 GB/s to the M3 Ultra's 819 GB/s, illustrating why identical memory capacity does not guarantee comparable responsiveness.
-
Leaked benchmarks provide limited evidence about the N1X silicon family, not the desktop GR1X itself. A pre-production Surface Laptop Ultra sample scored 5,771 in Cinebench 2026 multi-core and 23,126 in Geekbench 7 multi-core, but laptop thermals, unfinished drivers, unusual performance settings, and immature monitoring tools limit direct comparisons.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Master 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator