How Does xAI Build and Iterate So Quickly?
TL;DR
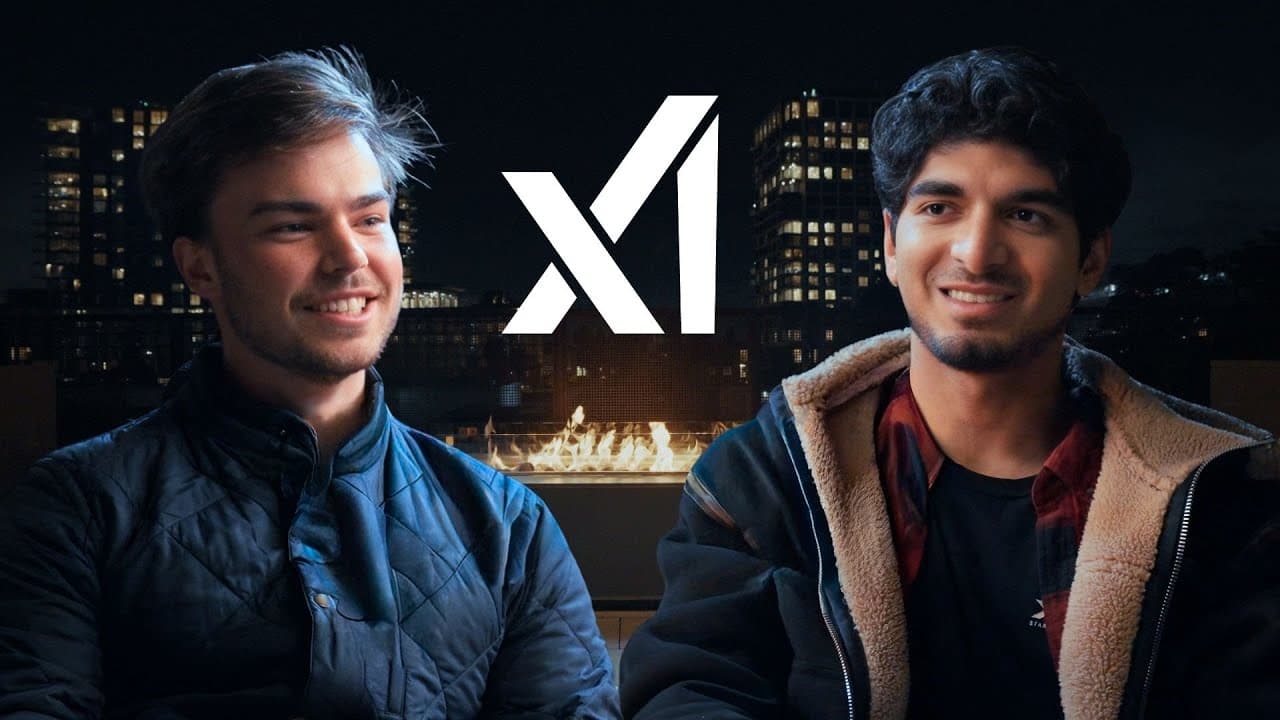
xAI moves quickly by identifying the core physical or financial constraint, removing artificial limitations, and organizing work around a high-leverage metric. Its engineers build infrastructure directly, run many training experiments in parallel, and receive broad autonomy to implement ideas immediately, while unusually fast hardware deployment supports rapid model and product iteration.
Transcript
Tyler took this bet with Elon like get a Cybert truck tonight if you can get a training run on these GPUs in 24 hours and we were training that night. >> Did he get the Cyber Truck? >> Yeah, he got Cyber Truck. >> My first day they just gave me a laptop and a badge and I was like okay now what? I don't even have a team. I've not been told what to d... Read More
Key Insights
- xAI's operating pace is driven by treating deadlines as already overdue and rejecting artificial blockers. Teams trace limitations toward their physical or financial foundations, then focus their effort on a core metric that directly reflects the desired return.
- Hardware deployment is described as xAI's biggest edge because the company builds and controls substantial infrastructure instead of accepting fixed cloud capacity. A newly installed rack can reportedly begin training within a day, and sometimes within only a few hours.
- Rapid experimentation is essential for xAI's novel model architectures because some projects do not build on an established body of work. They require new pre-training foundations and new datasets, making a high experiment rate necessary for discovering viable designs.
- Software performance limits are often treated as assumptions rather than fundamental constraints. Ghori says unnecessary stack overhead can frequently be removed, producing improvements of two to eight times for many relatively recent technologies, especially in areas involving speed and latency.
- Employee autonomy is a defining feature of xAI's engineering culture. Ghori says nobody told him what to do when he joined, so he found an active need involving Grok integrations with X and began contributing during his first week.
- Parallel execution allows xAI to pursue more than 20 efforts at once, including numerous training runs managed by small groups. High infrastructure utilization and concentrated technical talent enable model and product teams to produce iterations daily, sometimes multiple times per day.
- Long-term planning becomes more practical when infrastructure estimates are considered reliable. Ghori says the size and expectations for later Grok models were planned early, while rapid buildout allowed teams to design around lower latency assumptions than originally expected.
- Tesla computers are considered a possible deployment platform for Macrohard's human emulators. Ghori says deploying one million emulators would require one million computers, and the Tesla computer could potentially run both the model and a complete working environment more cheaply than cited alternatives.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How does xAI develop and train AI models so quickly?
xAI combines direct infrastructure deployment, extensive parallel experimentation, and small teams with broad authority. Ghori says a rack can begin training within a day of being installed, sometimes within hours. The company also removes conventional software overhead, runs many training efforts simultaneously, and centers decisions on metrics tied to fundamental physical or financial outcomes.
Q: Why is hardware infrastructure important to xAI's strategy?
Hardware is described as xAI's biggest edge because training capacity cannot simply be limited to whatever cloud providers make available. By building infrastructure directly, the company can maintain high utilization, bring new racks online rapidly, and give model teams confidence that expected resources will arrive. That reliability supports faster iteration and longer-term architectural planning.
Q: What is xAI's approach to conventional technical limitations?
xAI treats many accepted limitations as assumptions that should be challenged. Teams attempt to identify whether a restriction is genuinely rooted in physics or finance, or merely created by software layers and established practices. Ghori says removing unnecessary overhead can often improve relatively recent systems by two to eight times, particularly for speed and latency.
Q: What was Sulaiman Ghori's onboarding experience at xAI?
Ghori received a laptop and badge but was not assigned a team, desk, or specific task. He sought out co-founder Greg Yang, then noticed that work on Grok integrations with X needed help. He joined that effort during his first week, working closely with a small group and sitting at available desks around the office.
Q: How does employee autonomy work at xAI?
Engineers are expected to identify valuable problems and act on them without waiting for detailed instructions. Ghori says that if he has a good idea, he can often implement it the same day and show it directly to Elon Musk or another decision-maker. This autonomy shortens feedback loops and keeps teams focused on practical results.
Q: Why does xAI run so many experiments in parallel?
Parallel experimentation helps xAI explore multiple architectures and product directions without forcing every project into a long sequential queue. Ghori describes more than 20 efforts operating simultaneously, alongside many training runs handled by small groups. This scale is especially important for novel architectures that require new pre-training foundations instead of relying on existing research paths.
Q: How does fast infrastructure deployment affect xAI's planning?
Fast, reliable deployment lets model and product teams assume that required computing resources will become available. Ghori says this makes it possible to plan model size and expected capabilities well in advance. It also enables experiments with lower latency requirements, because teams can scale their experiment rate instead of designing around slower conventional infrastructure timelines.
Q: How could Tesla computers support Macrohard human emulators?
Macrohard's deployment concept would require a separate computer for each human emulator, so one million emulators would imply one million computers. Ghori says Tesla computers appeared to offer a capital-efficient option. They could potentially run both the model and the complete computer environment used by an emulated worker more cheaply than the alternatives he cited.
Summary & Key Takeaways
-
xAI operates with extreme urgency, loosely defined roles, and few artificial blockers. Engineers are expected to find useful work, trace problems to fundamental constraints, and act without waiting for conventional approval processes. Sulaiman Ghori describes joining without a team or assigned desk, then immediately helping build Grok integrations with X.
-
Infrastructure is presented as xAI's central competitive advantage. Racks can begin training within a day of installation, sometimes within hours, while many runs proceed simultaneously under small teams. This rapid deployment lets model and product engineers assume that planned computing resources will arrive and design ambitious experiments further in advance.
-
The company challenges accepted software limitations by removing unnecessary overhead and measuring work against core physical or financial outcomes. Ghori says recent systems can often be improved by two to eight times. This approach supports daily model iterations, novel architectures, and plans for deploying large numbers of human emulators on capital-efficient Tesla computers.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Relentless 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator