How do 1-bit LLMs achieve maximum efficiency?
TL;DR
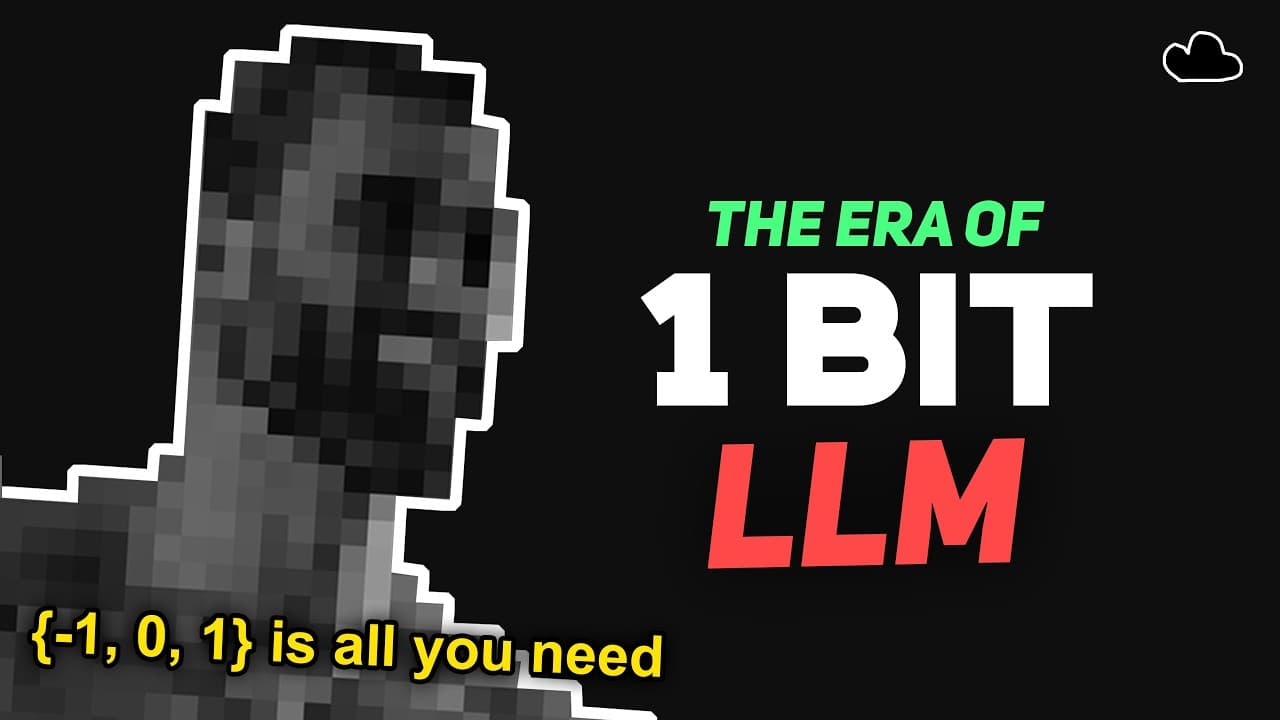
1-bit LLMs replace full precision weights with extremely compact representations, dramatically reducing memory and energy needs. Quantization to FP8 or even 1-bit schemes plus targeted activation reductions can keep performance while lowering resource use; BitNet variants show substantial memory and speed gains on larger models, though activations and KV cache remain bottlenecks.
Transcript
Pop quiz. What's something that you can see, you can copy, you can even have, but you cannot use? The answer is a state-of-the-art open-source model. Unless you are rich enough to have the hardware that would cost at least 400K, then running a copy of Deep Seek V3 is just a pipe dream for most of us. So, in response, researchers make smaller models... Read More
Key Insights
-
- A weight in an AI model is a parameter stored in FP16, representing the learned value.
-
- Quantization reduces weight precision to FP8 or lower to cut memory usage.
-
- Offloading weights to CPU/GPU memory can help fit models with small VRAM, but slows down computation.
-
- One bit neural networks aim to use only two states per weight, drastically reducing storage and computation.
-
- BitNet B1.58 adds a zero state to introduce sparsity, improving performance over pure 1-bit systems.
-
- Memory savings grow with model size, with BitNet 1.58 showing 3x memory reduction at 1.3B and 7.16x at 70B parameters compared to full precision models.
-
- Activation precision is still 8-bit and KV cache remains a bottleneck, motivating further reductions like 4-bit activations.
-
- The field is progressing with architectures that replace matrix multiplication with simpler operations while maintaining model capability.
- More videos from this channel:
- More from this channel: bycloud
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: A real search query question about the video (e.g. 'How to...', 'What is...', 'Why does...') Q1
What is a 1-bit LLM and why would researchers pursue such extreme quantization? A 1-bit LLM uses weights that are only one or negative one, drastically reducing memory and computation. The aim is to run large language models on far cheaper hardware by removing the need for full precision multiplications, trading some accuracy for huge efficiency gains.
Q: Question 2
How does BitNet B1.58 improve upon the original 1-bit approach? BitNet B1.58 adds a zero state to the weight representation, introducing sparsity that turns off some connections. This improves performance and energy efficiency beyond the basic 1-bit design, enabling better results on larger models while keeping the benefits of reduced computation.
Q: Question 3
What memory and speed benefits are claimed for BitNet on large models? For a 1.3 billion parameter baseline, BitNet B1.58 uses nearly three times less memory and is 66 times faster. On a 3 billion parameter model, it uses about 3.5 times less memory and is 2.7 times faster, illustrating how advantages scale with model size.
Q: Question 4
Why is FP8 preferred over FP16 in some cases according to the video? FP8 offers a smaller precision step than FP16, which can still maintain acceptable accuracy while reducing memory and energy costs. The video notes that the performance drop from FP16 to FP8 is not large, making FP8 a smarter choice in many scenarios.
Q: Question 5
What is the challenge with activations and the KV cache when using 1-bit or low-bit weights? Activations are still typically 8-bit, and the KV cache becomes a bottleneck as context length grows. This means even with 1-bit weights, users must address activation precision and caching efficiency to unlock full potential.
Q: Question 6
What is the proposed benefit of reducing activations to 4 bits in BNET A4.8? Reducing activations to 4 bits lowers the memory and compute burden further, helping to squeeze more efficiency from the model while aiming to preserve performance, particularly in attention mechanisms where precision matters.
Q: Question 7
What does the history of BitNet research imply about scaling laws for quantized models? The research suggests that the more parameters a model has, the better bit-based representations can perform, indicating favorable scaling where larger models benefit more from 1-bit and 1.58-bit representations, while still requiring careful management of activations and caches.
Q: Question 8
What practical steps could someone take to experiment with 1-bit or low-bit LLMs according to the video? Start with exploring BitNet implementations and papers, examine memory and energy metrics on larger models, test 4-bit activation variants, and consider activation and KV cache optimizations to balance accuracy with efficiency, while staying aware of the limitations highlighted in the video.
Summary & Key Takeaways
-
BitNet research shows 1-bit and 1.58-bit weights can cut memory usage and energy while preserving or improving performance at scale.
-
Activation precision remains a bottleneck and requires additional techniques like 4-bit activations to squeeze further gains.
-
The overall message is that extreme quantization can enable larger models to run with far lower hardware requirements without sacrificing too much accuracy.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from bycloud 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator