How to Build Generative AI Applications on AWS
TL;DR
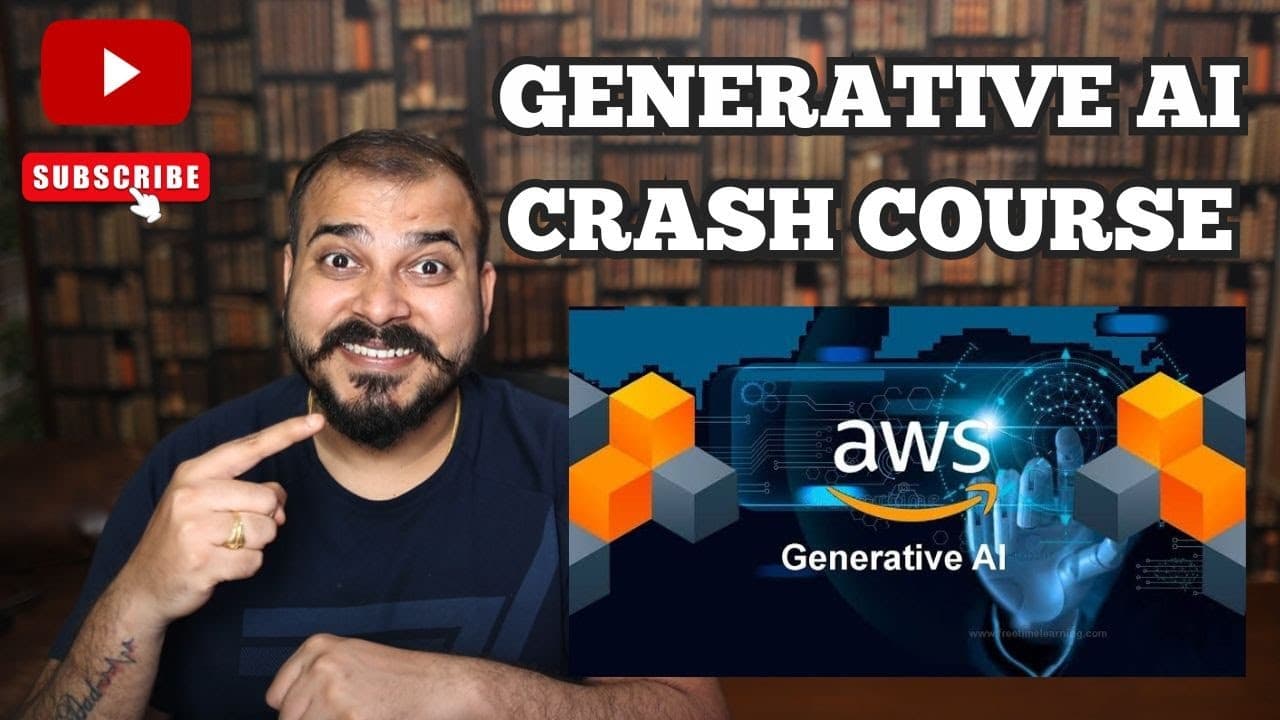
Build a generative AI application by defining its use case, choosing a suitable foundation or custom model, adapting and evaluating it, then optimizing it for deployment and application integration. AWS services such as Bedrock and SageMaker support access to foundation models, Hugging Face model deployment, inference, and integration with frameworks such as LangChain.
Transcript
hello all my name is krishak and welcome to my YouTube channel so guys welcome to the crash course of building generative AI application using AWS cloud in this crash course we will be seeing various AWS services and how we can specifically use them in order to build amazing generative AI applications not only that we'll also go through AWS Bedrock... Read More
Key Insights
- Use-case definition is the first stage of a generative AI project because it establishes the problem, scope, and technical requirements. Examples include retrieval-augmented generation, text summarization, and chatbot applications, each of which requires a different combination of data, models, storage, and integration components.
- A retrieval-augmented generation application can require PDF documents to be ingested, converted into vectors, and stored in a vector database. Identifying these requirements during scoping clarifies the complete workflow and the services needed before implementation, model adaptation, evaluation, or deployment begins.
- Model selection is a choice between using an existing foundation model and building a custom large language model from scratch. Foundation models include large existing models available for general use cases, while custom models are developed specifically for a company's requirements and require considerably more resources.
- Foundation models can solve many general business use cases without creating a new model from scratch. When a foundation model must perform better with custom data, it can be fine-tuned using techniques such as LoRA or QLoRA to adjust its behavior for the intended application.
- Model adaptation and alignment can use prompt engineering, fine-tuning, or training with human feedback. Prompt engineering may solve a use case without deeper model changes, while fine-tuning and human-feedback training provide additional ways to shape model behavior for specific requirements.
- Evaluation is the stage that determines how well an adapted model performs. Performance metrics are used to check whether the selected techniques are improving results and whether the model is ready to proceed from experimentation into optimization, deployment, inference, and application integration.
- Inference speed is essential because a completed or fine-tuned model cannot serve an application effectively unless it produces outputs quickly enough. LLM operations platforms and cloud services support deployment and inference, while different inference techniques can be considered when optimizing the final system.
- AWS Bedrock provides foundation models through APIs without requiring developers to manage the inference component directly. The course also uses SageMaker for deploying Hugging Face models and LangChain for building end-to-end generative AI applications that can be integrated and deployed on AWS.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How do you plan a generative AI project life cycle?
Start by defining the use case, project scope, and all associated requirements. Next, choose either an existing foundation model or a custom model built from scratch. Adapt and align the model through prompt engineering, fine-tuning, or training with human feedback. Evaluate its performance, optimize and deploy it for inference, integrate the resulting API, and build the LLM-powered application.
Q: How do you define a generative AI use case?
Define the specific business problem and the type of application required, such as retrieval-augmented generation, text summarization, or a chatbot. Then identify every component needed to support that application. For example, a retrieval project may involve PDF files, data ingestion, vector conversion, and a vector database. These decisions collectively establish the project's scope and requirements.
Q: Should you use a foundation model or build a custom LLM?
Use a foundation model when an existing large model can address the general use case directly or can be adjusted for custom data through fine-tuning. Build a custom LLM from scratch when the company requires a model designed specifically for its use case. The custom approach requires substantial resources and additional attention to issues such as model hallucination.
Q: How can a foundation model be adapted to custom data?
A foundation model can first be tested with prompt engineering to determine whether carefully designed instructions solve the use case. If stronger customization is required, the model can be fine-tuned on relevant data with techniques such as LoRA or QLoRA. Training with human feedback is another alignment mechanism discussed for shaping model behavior during model development.
Q: Why is model evaluation required before deployment?
Model evaluation determines how well the selected model performs after prompt engineering, fine-tuning, or alignment work. Performance metrics show whether results are improving and help establish whether the model is ready for deployment. Only after the model meets the intended performance needs should the workflow proceed to optimization, inference deployment, API integration, and application development.
Q: Why does inference speed matter for LLM applications?
Inference speed matters because a trained or fine-tuned model must generate outputs efficiently when used inside an application. A model that is successfully built but performs inference too slowly cannot be used effectively for the intended solution. The workflow therefore emphasizes model optimization, deployment platforms, cloud inference services, and multiple inference techniques as major parts of production delivery.
Q: How does AWS Bedrock support generative AI development?
AWS Bedrock provides access to multiple foundation models through APIs, allowing developers to use those models without worrying about managing the inference process directly. Within the described course, Bedrock is combined with LangChain to create end-to-end generative AI applications. This approach supports model access, application construction, integration, and deployment within an AWS-focused workflow.
Q: How are Hugging Face models deployed with AWS SageMaker?
The course includes using Hugging Face with AWS SageMaker to deploy large language models. This deployment work belongs to the optimization and inference stage of the generative AI project life cycle. After deployment, the model can be exposed through an API, integrated with other application components, and used as the model layer of an LLM-powered solution.
Summary & Key Takeaways
-
The generative AI project life cycle begins with defining the use case and its requirements. Possible projects include retrieval-augmented generation applications, text summarization systems, and chatbots. A retrieval project may require PDF ingestion, vector conversion, and a vector database, so its scope should identify every necessary component before model development begins.
-
Model selection involves choosing between an existing foundation model and a custom large language model built from scratch. Foundation models can address many general use cases directly and can also be fine-tuned with techniques such as LoRA or QLoRA. Custom models can serve specialized requirements but demand substantial resources and attention to hallucination.
-
After selecting a model, teams can use prompt engineering, fine-tuning, or training with human feedback to adapt and align it. Evaluation measures whether performance improves and whether the model is ready. The final stages optimize and deploy the model for inference, integrate its API, and build the resulting LLM-powered application.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Krish Naik 📚

Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator