How to Choose Between Codex 5.3 and Opus 4.6
TL;DR
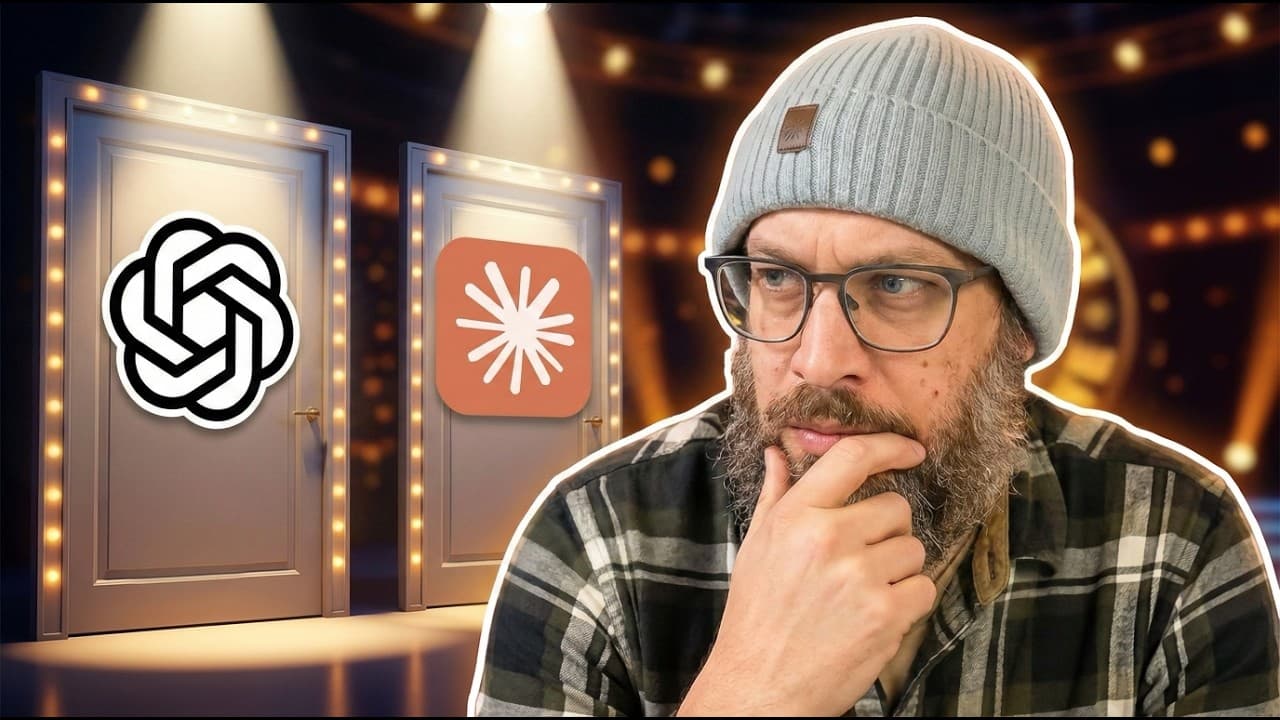
Choose Codex for complex, delegation-shaped work that can run autonomously, and choose Claude for coordination-shaped work spanning teams, tools, and existing workflows. Codex emphasizes planning, testing, recovery, and isolated worktrees, while Claude emphasizes integrations and peer communication among agents. Many organizations may benefit from combining both approaches instead of selecting one universal winner.
Transcript
Two visions of the Asian future shipped just 20 minutes apart a week or so ago. The one you pick changes how you work. Open AI shipped an AI system that's designed to be handed a task and left alone. You walk away, it works for hours, you come back to finished code. Anthropic shipped Opus 4.6. It's designed to plug into every tool you use, coordina... Read More
Key Insights
- Codex is designed for delegation-shaped work that users can hand off and leave running for hours. It builds a plan, decomposes the problem, executes subtasks, tests its changes, checks the result, and reports when the work is ready for human review.
- Claude is designed for coordination-shaped work across existing tools, agents, and organizational workflows. Opus 4.6 emphasizes integrations with systems such as Slack and project trackers, plus peer-to-peer communication among agents handling interdependent tasks.
- The central difference is organizational design, not simply benchmark performance. Codex resembles an employee who independently manages delegated work, while Claude resembles a coordinated team that remains connected to the user, workplace tools, and other agents throughout execution.
- Codex 5.3 scored 77.3% on Terminal Bench 2.0, compared with 65.4% for Opus 4.6, according to the transcript. The benchmark measures whether models can perform useful work within real codebases instead of merely solving isolated programming exercises.
- Codex 5.3 scored 64.7% on OS World Verified, while its predecessor scored 38.2%, according to the transcript. The newer model was also described as 25% faster and as using 93% fewer tokens on tasks where earlier models were especially wasteful.
- The Codex desktop app isolates every assignment in its own worktree. Multiple agents can therefore modify separate copies of a codebase simultaneously without touching the user's active branch, and successful changes can be merged while unsatisfactory work can be discarded.
- Codex automations can dispatch agents when predefined conditions occur. A newly filed issue can trigger an investigation, a failed test can trigger debugging, and a merged pull request can trigger review, allowing recurring development tasks to run continuously after initial configuration.
- The best agent choice depends on whether value comes from autonomous completion or ongoing coordination. Teams should classify workflows by that distinction and may adopt a mixture of Codex and Claude rather than forcing every problem into one agent operating model.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How should teams choose between Codex and Claude?
Teams should classify their work as delegation-shaped or coordination-shaped. Codex is better aligned with complex tasks that can be clearly assigned, completed autonomously, and reviewed afterward. Claude is better aligned with work requiring agents to communicate with one another, connect with workplace tools, and remain embedded in existing processes. Many organizations may need both systems for different workflows.
Q: What kinds of tasks are best suited to Codex?
Codex is suited to complex technical assignments where correctness matters more than immediate feedback. Examples in the transcript include analyzing a codebase, processing many documents, refactoring a module across a dozen or 20 files, adding a feature in an unfamiliar codebase, and diagnosing a bug that appears only under system load. These tasks benefit from planning, testing, and recovery.
Q: What kinds of tasks are best suited to Claude Opus 4.6?
Claude Opus 4.6 is suited to interdependent work that spans tools, agents, teams, or departments. Its approach emphasizes integration with places where work already happens, including Slack and project trackers, as well as direct communication among agents. This makes it appropriate when progress depends on coordination and shared context rather than one autonomous worker completing an isolated assignment.
Q: How does the Codex agent architecture improve reliability?
Codex uses a three-layer structure focused on producing trustworthy completed work. An orchestrator manages the overall assignment, executors handle individual subtasks, and a recovery layer detects failures and corrects them. Before producing results, the system builds an internal plan, decomposes the problem, runs tests, and checks its own work. The goal is to reduce constant human inspection during execution.
Q: What do the Codex 5.3 benchmark results show?
According to the transcript, Codex 5.3 scored 77.3% on Terminal Bench 2.0, while Opus 4.6 scored 65.4%. It also scored 64.7% on OS World Verified, compared with 38.2% for Codex 5.2. The transcript further states that Codex 5.3 was 25% faster and used 93% fewer tokens on tasks where earlier models were most wasteful.
Q: How do worktrees support multiple Codex agents?
Every task in the Codex desktop app runs inside its own worktree, described as an isolated copy of the codebase. This lets several agents work simultaneously without modifying the user's active branch or interfering with one another. Users can review and merge successful changes, while discarding unsuitable results. The structure turns the app into a command center for parallel delegated assignments.
Q: What Codex tasks can be started automatically?
Codex automations can launch agents when predefined triggers detect specific conditions. The transcript gives three examples: a new issue can start an investigation, a failed test can initiate debugging, and a landed pull request can begin an automated review. Once these triggers are defined, the system can continuously dispatch appropriate work without requiring a person to start every task manually.
Q: What is the main tradeoff of Codex's autonomous approach?
The main tradeoff is that Codex can be measurably slower on simple tasks because its architecture prioritizes planning, correctness, testing, and recovery rather than immediate output. The transcript argues that this becomes beneficial on complex work, where stronger self-checking may reduce the total time spent finding errors, repairing weak output, or cleaning up changes after the model finishes.
Summary & Key Takeaways
-
Codex represents a delegation model for AI work. A user describes a complex task, allows the system to plan and execute for hours, and returns later to review completed work. Its architecture emphasizes autonomous correctness through orchestration, specialized executors, testing, self-checking, and a recovery layer that detects and corrects failures.
-
Claude represents a coordination model designed to operate within existing tools and workflows. Opus 4.6 can connect with systems such as Slack and project trackers while coordinating agent teams through peer-to-peer communication. This approach suits interdependent knowledge work where agents, employees, departments, and software tools must exchange information throughout the process.
-
The practical choice depends on the shape of the work rather than a single benchmark winner. Delegation-shaped engineering problems favor Codex, while coordination-shaped organizational problems favor Claude. Codex may change existing workflows more substantially, whereas Claude may fit into them more naturally. Many organizations will need both operating models for different responsibilities.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI News & Strategy Daily | Nate B Jones 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator