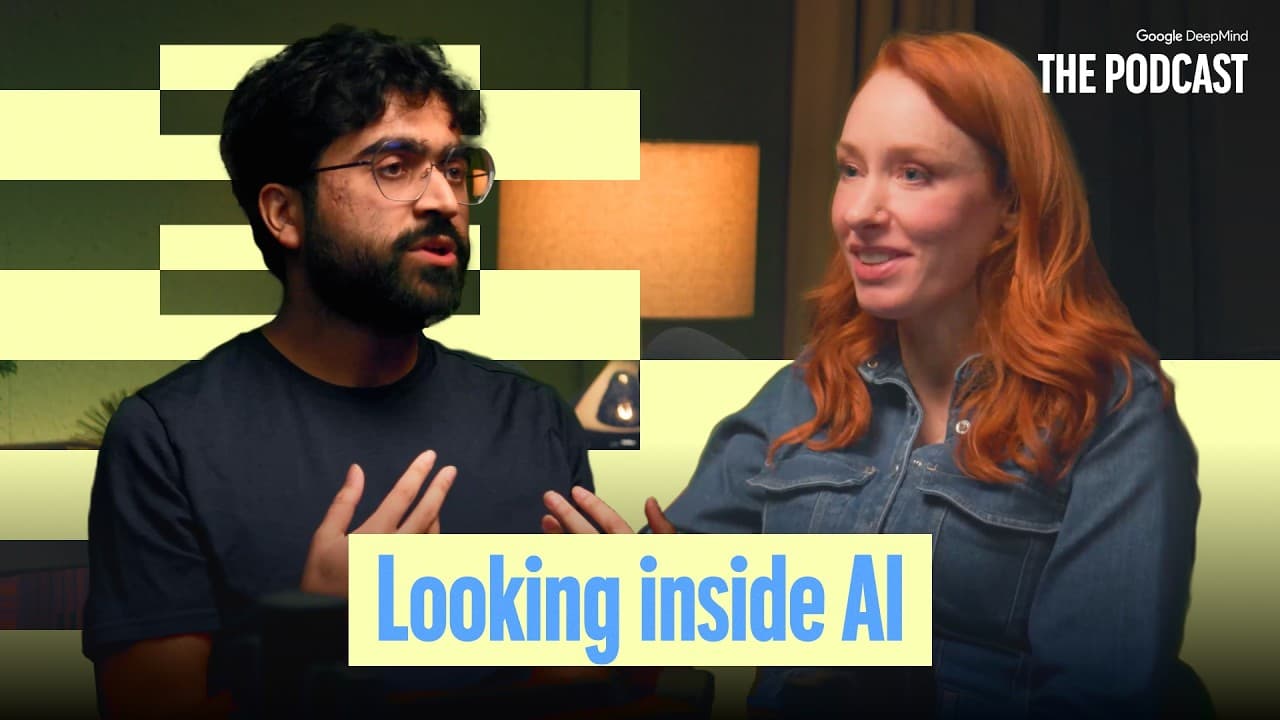
What is AI interpretability and why does it matter
TL;DR
Interpretability is the study of how neural networks process data by mapping internal numbers to understandable concepts. It uses methods like reading the model’s scratchpad or chain of thought to reveal reasoning steps, while recognizing limits and the need for layered safety to build trustworthy AI as it approaches AGI.
Transcript
Welcome to Google DeepMind, the podcast. I'm professor Hannah Fry. What if you were to peer inside the mind of AI? You wouldn't find fully formed thoughts or intentions written in plain English, just vast arrays of numbers combining together in ways that somehow produce intelligence. How? We genuinely don't know. And that is the problem a field cal... Read More
Key Insights
- AI interpretability is the study of mapping neural network internals to understandable concepts, aiming to illuminate how these systems work rather than leaving them as opaque black boxes. It frames the field as a blend of neuroscience like investigation and engineering practice.
- Interpretable research seeks to reverse engineer what neural networks have learned during training, using analogies such as evolution to explain how complex capabilities emerge from simple iterative nudges over time.
- The chain of thought or scratchpad analogy helps reveal problem solving steps, but it is not guaranteed to expose every detail of the model’s reasoning, so interpretation must be complemented with other methods.
- Reading a model’s scratchpad can be informative for hard problems where steps are necessary, yet may be less useful for easy tasks solved mentally without explicit intermediate steps.
- There are concerns about future models concealing misbehavior, making it important to develop monitoring tools that can detect inconsistencies between stated reasoning and actions.
- A defense in depth approach is advocated, combining multiple imperfect interpretability and safety techniques to reduce risk rather than relying on a single perfect solution.
- The field recognizes limits to complete mechanistic understanding of extremely complex systems, while still pursuing practical progress that improves safety and reliability.
- Interpretable work not only aids safety but also helps scientists debug, understand failure modes, and gain confidence in deploying AI at scale.
- More videos from this channel:
- More from this channel: Google DeepMind
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is AI interpretability and why is it needed
AI interpretability is the study of understanding how neural networks produce their outputs by examining internal representations and learned features. It is needed to build safe, trustworthy systems, enable debugging, and provide insight into when and why models fail or behave unexpectedly. This understanding guides safer deployment and responsible progress toward advanced AI.
Q: How do researchers open up the black box in AI
Researchers open up the black box by using techniques that reveal internal processes, such as inspecting the chain of thought or scratchpad, analyzing intermediate representations, and attempting to reverse engineer what the model has learned during training. These methods help connect micro level processes to macro level behavior and identify potential failure modes.
Q: What is the scratchpad analogy in AI thinking
The scratchpad analogy compares a model’s internal reasoning to a scientist writing notes while solving a problem. It helps distinguish between the visible steps taken to reach a solution and the final answer, illustrating that reading the scratchpad can reveal the problem solving path, though it may not show every aspect of the reasoning.
Q: Why is chain of thought monitoring important
Chain of thought monitoring is important because it provides a window into the model’s reasoning steps for difficult problems, enabling evaluation of whether the model is following a plausible and correct process. It aids safety by exposing potential missteps, biases, or unsafe plans that could be hidden in a simple answer.
Q: Are there limits to understanding how AI models work
Yes, there are limits to understanding how AI models work due to the complexity of neural networks and the scale of their training. While progress can reveal many mechanisms, a complete, perfect mechanistic understanding may be unattainable, making a pragmatic, multi method safety approach essential.
Q: What is meant by defense in depth in AI safety
Defense in depth in AI safety refers to using multiple independent safety measures that complement each other, recognizing that no single method is perfect. By layering interpretability, monitoring, alignment checks, and governance, the overall safety posture becomes stronger and more robust against failures.
Q: How does interpretability relate to AGI safety
Interpretability relates to AGI safety by providing visibility into how advanced systems reason, enabling detection of risky behaviors, debugging problematic outputs, and informing safeguards. It helps build confidence and trust, ensuring that as AI capabilities scale, governance and safety mechanisms keep pace.
Q: What original goals exist for interpretability research
The original goals of interpretability research include fully understanding models or getting as close as possible to a complete description of how they work. Researchers aim to connect micro level operations to macro level behavior, enabling thorough auditing, debugging, and safer deployment of intelligent systems.
Summary & Key Takeaways
-
Interpretability explores how neural networks emerge from data and learning processes rather than being explicitly designed, aiming to map internal structures to understandable concepts. It emphasizes revealing the model’s reasoning through techniques such as scratchpads or chain of thought analyses to aid understanding and safety.
-
The discussion highlights the balance between aiming for deep mechanistic understanding and practical usefulness, acknowledging limits in fully decoding complex systems while promoting safety by combining multiple imperfect methods in defense in depth.
-
The episode frames interpretability as essential for safe, aligned AI development and provides practical approaches to examine and audit models, supporting responsible progress toward more capable systems without overclaiming complete transparency.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Google DeepMind 📚

Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator