Real-Time Voice Cloning with Deep Learning
TL;DR
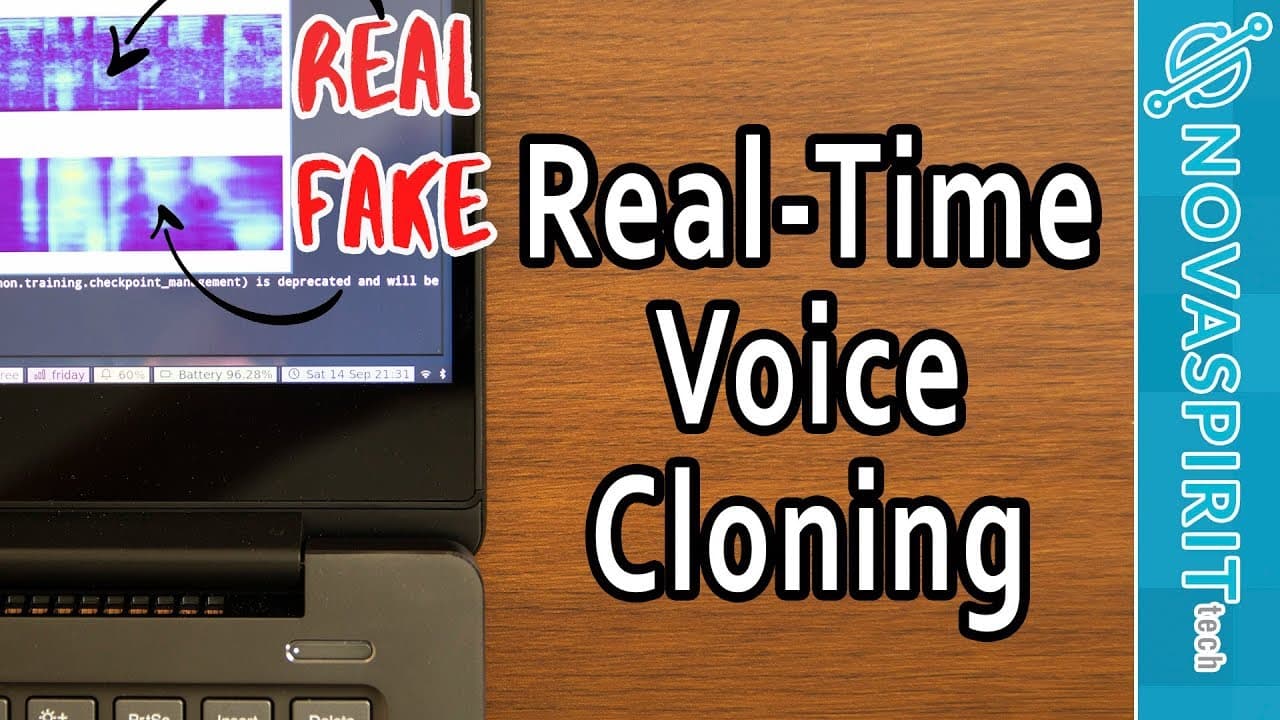
Real-time voice cloning uses deep learning to clone a person’s voice from a five-second sample and generate speech from typed text. The software runs on Python 3, takes about one gigabyte of space, and works best with an Nvidia graphics card with at least 2 GB of RAM. Its output remains robotic and lacks natural emphasis, making the installation steps, performance limits, and consent warning worth reading.
Transcript
hey guys what is going on it's down here from Nova spirit second today we are to be taking a look at something very cool yet very creepy and it's called the real-time voice cloning software and yeah I said cloning not changing so let's get started so before we again I want to talk about one of my sponsors which is private Internet access if you guy... Read More
Key Insights
- 😯 Real-time voice cloning technology represents a significant advancement in artificial intelligence, enabling the replication of human speech with minimal input.
- 🥺 Ethical implications loom large as voice cloning capabilities could lead to identity fraud and unauthorized voice replication in sensitive contexts.
- 🐎 Effective operation of the software requires specific hardware configurations, particularly a compatible Nvidia graphics card for speed and performance.
- 👨💻 Installation and operational processes are relatively straightforward, making this technology accessible to individuals with basic coding knowledge.
- ⚾ There is potential for improvements in voice cloning technology as developers can contribute and enhance the existing models based on community feedback.
- 😯 Current outputs from the software may not perfectly capture the emotional subtleties of human speech, indicating a need for ongoing development.
- 🧡 Practical applications for the technology range from creative projects to security systems, provided ethical considerations are strictly adhered to.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is real-time voice cloning, and how does it work?
The software uses deep learning to clone someone’s voice from a five-second audio sample. It can then generate that voice saying whatever text the user provides, although the result may sound robotic.
Q: How much audio is needed to clone a voice?
The software can work from five seconds of someone’s voice. The speaker warns that users should obtain the person’s consent before recording and cloning that voice.
Q: What computer requirements does the voice cloning software have?
Any computer that supports Python 3 should be able to run the software, and the installation takes about one gigabyte of space. An Nvidia graphics card with at least 2 GB of RAM is recommended; less memory can work, but it is much slower.
Q: How do you install the real-time voice cloning software?
Clone the GitHub repository, change into its folder, and use pip 3 to install the listed requirements. Then install PyTorch and TorchVision for the relevant system configuration, download the pretrained models, and place the encoder, vocoder, and synthesizer files in their corresponding locations.
Q: How long does installation take, and how large are the downloads?
Installing the required packages takes about five or ten minutes, depending on the internet connection. The PyTorch installation is about 300 megabytes, while the complete software setup takes about one gigabyte of space.
Q: How can you check whether the voice cloning installation works?
Run the demo CLI with Python 3 to test whether the system is ready. This check reports whether the setup is ready and is quicker than completing the full process through the toolbox; a successful setup displays that all tests passed.
Q: Can the software run on a graphics card with less than 2 GB of RAM?
Yes, the speaker demonstrates it on a laptop whose Nvidia graphics card has less than 2 GB of RAM. The low-memory option is required in that situation, and processing is much slower.
Q: What are the limitations and ethical concerns of real-time voice cloning?
The software is still in an early stage, and its generated speech sounds robotic because it does not reproduce natural emphasis or the way people normally talk. It can also be misused for unauthorized voice replication or identity fraud, so the speaker stresses obtaining consent before cloning someone’s voice.
Summary & Key Takeaways
-
The content introduces a real-time voice cloning software that can replicate someone's voice after a five-second sample, highlighting its ease of use and accessibility for Python 3 compatible devices.
-
The speaker emphasizes the ethical implications of such technology, warning against using it without consent, and discusses the limitations, including robotic-sounding outputs and the need for high-performance hardware.
-
Detailed installation instructions and a walkthrough of the software's functionalities demonstrate its practical applications, alongside personal testing results showing the software's effectiveness and areas for improvement.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Novaspirit Tech 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator