LLM Hacking Defense: Strategies for Secure AI
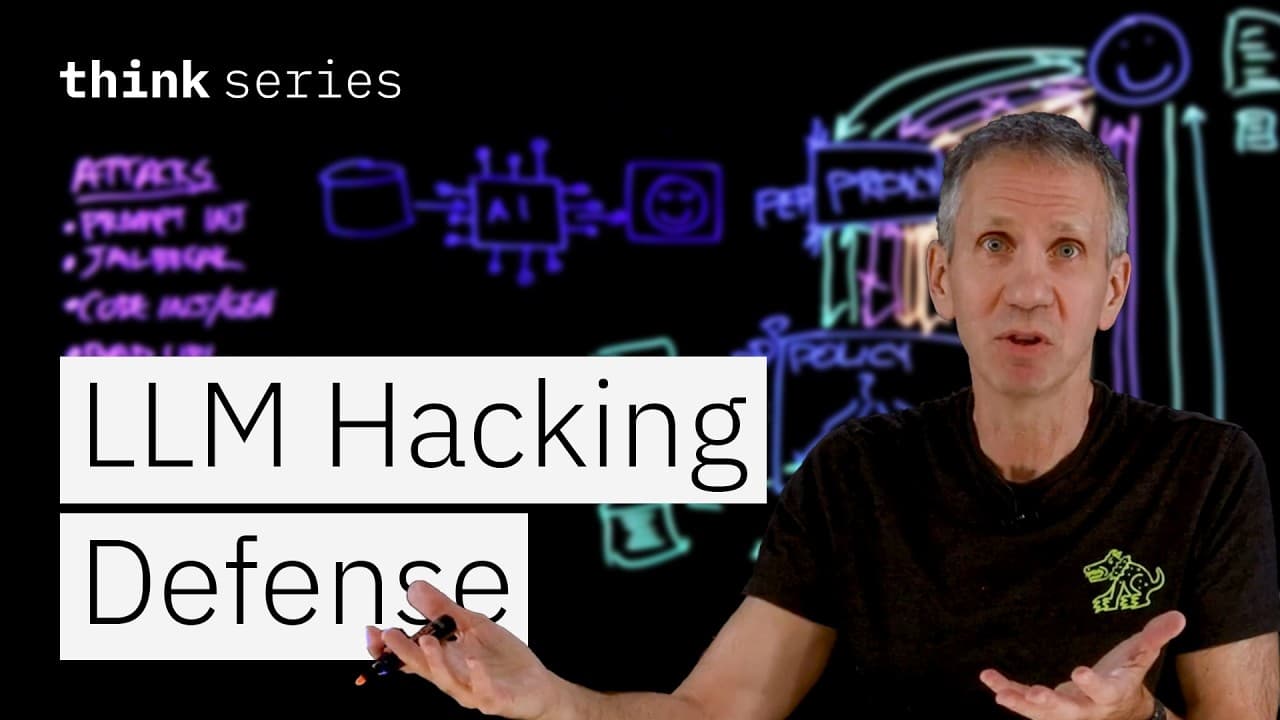
LLM Hacking Defense: Strategies for Secure AI
Transcript
Large language models are powerful, but they're often vulnerable to a wide variety of new attacks, ones that our traditional defenses aren't able to block. One of the most dangerous examples is called prompt injection, and it can lead to unexpected, manipulated, or even harmful outputs. In previous videos, I've talked about the importance of securi... Read More
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Download browser extensions on:
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
How Does Risk Determine an AI Architecture?
IBM Technology
4 Methods of Prompt Engineering
IBM Technology
What is the difference between AI and ML and how they relate?
IBM Technology
How to Reduce AI Risk With Governance and Security
IBM Technology
What is a Digital Twin?
IBM Technology
AI Agents Best Practices: Monitoring, Governance, & Optimization
IBM Technology
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Download browser extensions on:
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator