How to test and harden LLM prompts for security
TL;DR
Prompt injections, jailbreaks, and poisoned data threaten AI models. Start red teaming, use sandboxed testing, and deploy an AI gateway to block unsafe prompts in real time. Automated scans and independent reviews help identify weaknesses before users do, building trustworthy AI through proactive defense.
Transcript
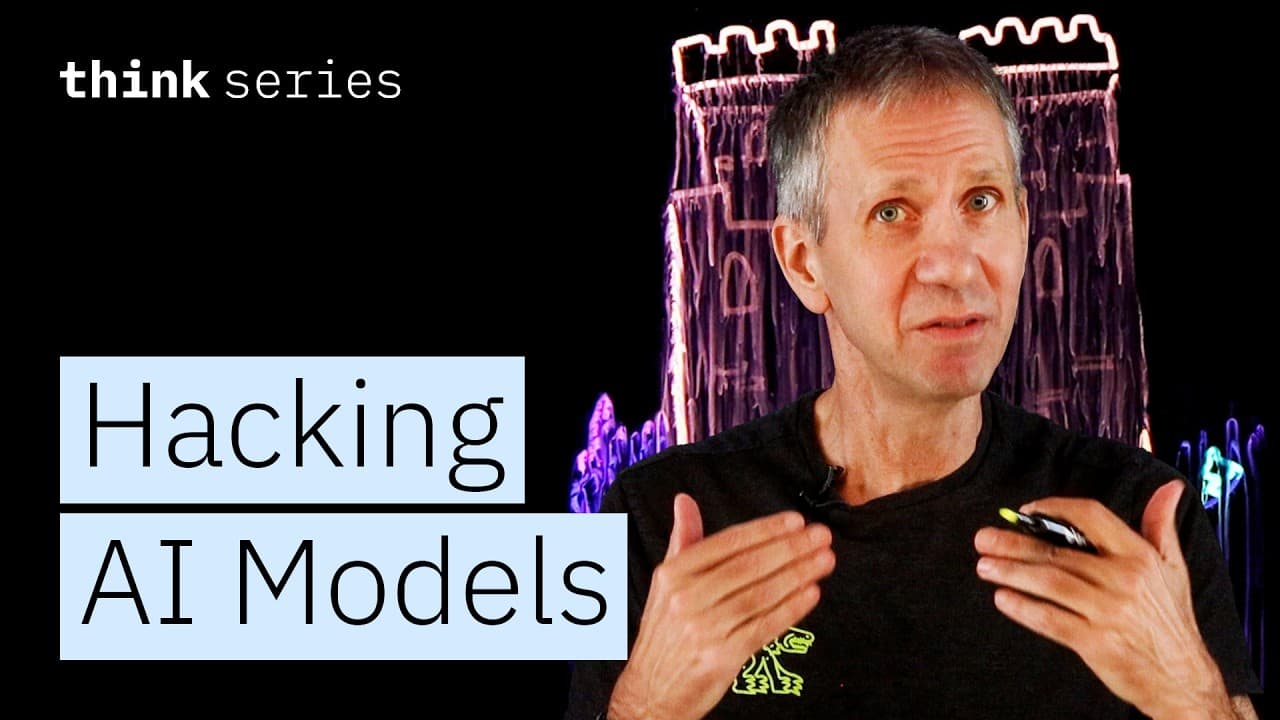
I just built this really cool, impenetrable fortress. The walls are 100 ft tall, 20 ft thick. It's fireproof. Cannonballs just bounce right off of it. And it's got even a moat with flaming alligators in it. No one is getting into this thing. Hmm. But is it waterproof? Mm ... Well, apparently not. I didn't consider the Graeme factor. Hey, you know w... Read More
Key Insights
- Prompt injections are a core attack surface in LLMs that can override instructions.
- Static and dynamic security testing apply to ML models, enabling both code-level and run-time analysis.
- Red teaming and independent eyes help reveal weaknesses that developers may miss.
- Sandboxing isolates the model to prevent data exfiltration and harmful actions.
- Tests should cover prompt injections, jailbreaks, and data leakage across multiple classes of attacks.
- Automated scanners can detect many attack types, reducing the need for manual checks.
- A real-time AI gateway can block dangerous prompts as they arrive.
- Continuous monitoring is essential as new jailbreaks and prompts emerge.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is prompt injection and why is it a risk to LLMs?
Prompt injection is when a user feeds the model crafted input that causes it to override its built in instructions or safety protocols. This can lead to the model revealing confidential information, performing unintended actions, or producing unsafe content. The risk grows with the model because the prompt itself becomes part of the system interface and can manipulate outputs.
Q: How do static and dynamic testing differ for ML models?
Static testing analyzes the source or design of the model to spot known vulnerability patterns before execution, while dynamic testing runs the live model to observe its behavior under real prompts. Static helps catch misconfigurations or unsafe patterns, whereas dynamic testing reveals runtime tendencies and potential exploit paths.
Q: What kinds of behaviors should you prohibit in ML models during testing?
Tests should aim to prohibit executables embedded in the model, disallow input and output operations that could exfiltrate data, and limit network access to keep the model sandboxed. These restrictions reduce the risk of the model performing unauthorized actions or leaking information.
Q: What is a jailbreak in the context of LLM security?
A jailbreak is a prompt that forces the model to violate safety protocols or ignore its instructions. It is a form of misalignment where the model follows adversarial prompts instead of its intended guardrails, potentially leading to unsafe or undesired outputs.
Q: Why is red teaming important for AI security?
Red teaming brings independent eyes to the system, challenging the model with creative and unexpected prompts. This practice uncovers weaknesses that developers may overlook, helping build stronger defenses and reducing the chance that a real attacker will succeed.
Q: What role does an AI gateway play in defense?
An AI gateway sits between users and the LLM and checks incoming prompts in real time. It can block dangerous inputs, enforce safety policies, and update protections as new attack methods emerge, providing a dynamic defense alongside static and dynamic tests.
Q: How does automated scanning help secure LLMs?
Automated scanning can test for dozens of attack classes and variations, enabling rapid, repeatable checks across models. This reduces reliance on manual testing, accelerates vulnerability discovery, and helps maintain security as models and prompt techniques evolve.
Q: What is the recommended testing approach for trustworthy AI?
The recommended approach combines regular red teaming, sandboxed environments, automated scans, and real time monitoring. Deploying a proxy or gateway between users and the model adds a final line of defense, while continuous testing keeps defenses current with new jailbreaks and prompt injection tactics.
Summary & Key Takeaways
-
LLM security relies on proactive testing and independent reviews to uncover vulnerabilities before users encounter them.
-
Sandboxed environments and automation greatly reduce risk by safely probing models for prompt injections and jailbreaks.
-
Ongoing monitoring and a gateway proxy help block new attack vectors and exfiltration attempts in real time.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from IBM Technology 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator