How Do You Build VGG From Scratch? Deep Learning Theory and PyTorch Full Course
TL;DR
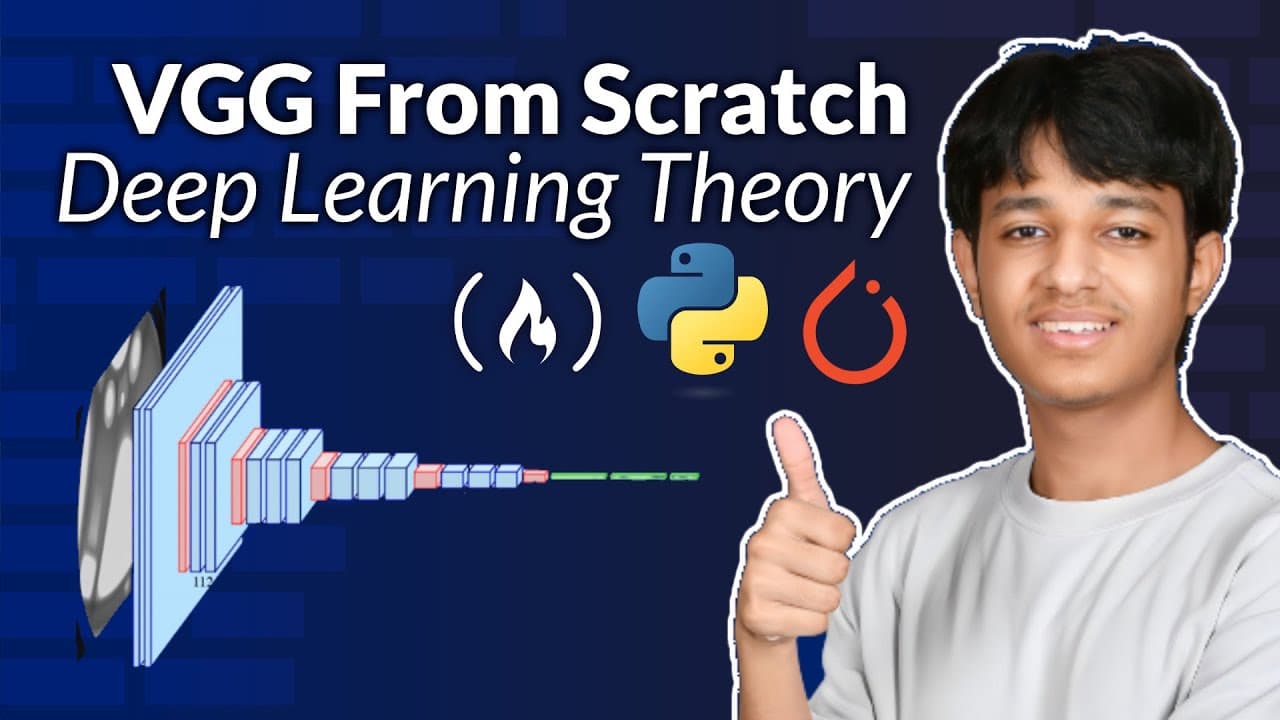
VGG processes images through stacked convolution and ReLU layers, periodic max pooling, and fully connected classification layers. It uses uniform 3x3 filters with stride one and padding one, while max pooling reduces spatial dimensions and the number of model parameters. The course rebuilds this influential architecture in PyTorch and explains its theory, mathematics, training, fine-tuning, and visualization, giving readers practical reasons to continue.
Transcript
This course is a hands-on deep learning tutorial that will help you understand one of the most influential convolutional neuronet networks in computer vision. You'll learn how to rebuild the VGG architecture from the ground up while mastering the theory, mathematics, and design principles that shaped it. VGG stands for visual geometry group. It's a... Read More
Key Insights
- VGG stands for Visual Geometry Group, a deep convolutional neural network known for its simple, uniform use of small 3x3 filters stacked in sequence to enable powerful image recognition and feature extraction.
- The VGG architecture combines three layer types: convolution layers paired with ReLU, max pooling layers, and fully connected layers at the end that classify the image into predefined classes.
- Max pooling layers reduce the dimensionality of the image, which lowers the number of parameters in the model and makes it faster to compute, downsizing the spatial size while increasing kernel depth.
- The ReLU layer, short for rectified linear unit, enables the model to learn complex nonlinear relationships, allowing it to capture complex curves and patterns present in the image.
- VGG uses 224x224 RGB input images with three color channels, standardized by subtracting the mean RGB value during preprocessing before feeding them into the first convolution layer.
- Every convolution layer in VGG uses 3x3 filters with a stride of one and padding of one to preserve spatial dimensions, applying the uniformity principle of a consistent kernel size across the whole architecture.
- VGG rests on three pillars: simplicity, depth, and uniformity, following a repeating pattern of convolution and max pooling blocks that grow from two to three convolution layers before each pooling step.
- VGG was unveiled at the ImageNet ILSVRC 2014 challenge by Karen Simonyan and Andrew Zisserman of Oxford's Visual Geometry Group, marking a shift from handcrafted feature engineering to deep learned features.
- "It's a deep convolutional neuronet network architecture known for its simple uniform use of small 3x3 filters stacked in sequence enabling powerful image recognition and feature extraction." (0:22)
- "The convolution operation is the most fundamental operation within any CNN model." (3:01)
- "So a CNN model must include at least one convolution layer." (3:14)
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is VGG in deep learning?
VGG stands for Visual Geometry Group. It is a deep convolutional neural network architecture known for stacking small 3x3 filters in a simple, uniform sequence for image recognition and feature extraction.
Q: How does the VGG architecture process an image?
VGG accepts a 224x224 image and passes it through convolution layers that apply filters to detect features. ReLU layers follow convolution operations, max pooling periodically reduces spatial dimensions, and fully connected layers classify the image into a predefined number of classes.
Q: Why does VGG use 3x3 filters?
VGG uses the same small 3x3 filter size throughout its architecture as part of its uniform design. These filters are stacked in sequence to extract increasingly fine-grained and complex patterns from an image.
Q: What does max pooling do in VGG?
Max pooling reduces the spatial dimensions of the data produced by convolution layers. This lowers the number of model parameters, making computation on the image faster while passing the downsized output to later convolution layers.
Q: What does ReLU do in the VGG architecture?
ReLU stands for rectified linear unit and follows convolution operations in VGG. It lets the model learn complex nonlinear relationships, curves, and image patterns rather than being limited to linear relationships.
Q: What image features can a VGG model learn?
The model can learn features such as edges, angles, lines, stripes, color gradients, brightness, contrast, and color saturation in pixels. These features are not explicitly defined by the programmer, because the model determines useful patterns from its inputs and correct outputs.
Q: What does the VGG from-scratch course implement in PyTorch?
The course builds a modular, transparent VGG implementation in PyTorch while explaining convolution mathematics and VGG design principles. It also covers data handling, transformation, visualization, a full training loop with live loss curve plotting, and fine-tuning.
Q: What tools does the VGG PyTorch course use?
The course uses Google Collab for practical work with data handling, transformation, and visualization. It also uses torch info, mapplot lib, and CNN explainer to analyze and interpret models.
Summary & Key Takeaways
-
VGG, or Visual Geometry Group, is a deep convolutional neural network that rebuilds image recognition from stacked convolution layers, max pooling layers, and fully connected layers. A CNN must include at least one convolution layer, since the network is named after the convolution operation, the most fundamental operation in any CNN model.
-
The architecture processes a 224x224 RGB image through convolution layers that apply kernels to extract features such as edges, angles, lines, color gradients, brightness, contrast, and saturation. Max pooling layers periodically reduce dimensionality and parameter count, making the model faster while preserving the important learned spatial patterns and features.
-
VGG embodies a philosophy that elegant simplicity, scaled methodically with depth, yields extraordinary expressive power. It rests on simplicity, depth, and uniformity, using only 3x3 filters with stride one and padding one. Debuting at ImageNet ILSVRC 2014, it shifted computer vision from handcrafted features to deep learned features.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from freeCodeCamp.org 📚

Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator