How to Train Reliable AI Agents Using RL
TL;DR
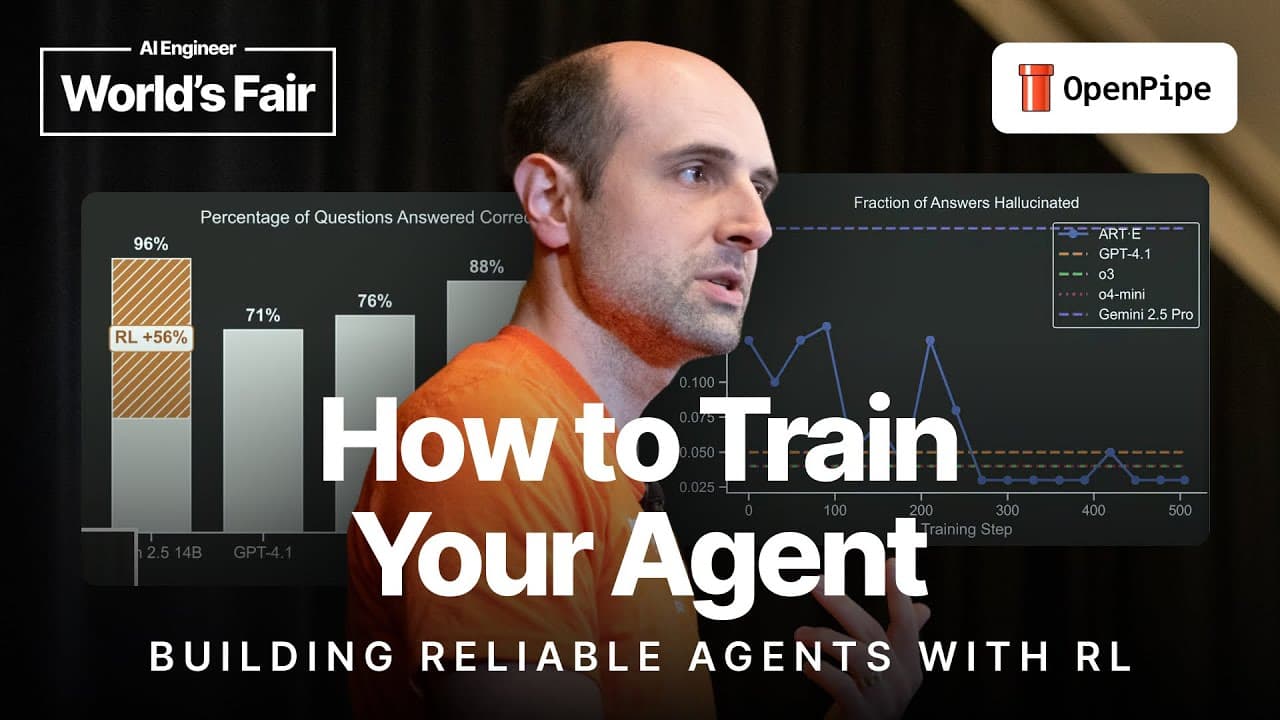
Start by pushing prompted models as far as possible, then use reinforcement learning only when they remain insufficient. Reliable agent training depends primarily on a realistic environment and an accurate reward function; with those foundations, a smaller specialized model can surpass prompted frontier models while reducing inference cost, latency, tool calls, and database interactions.
Transcript
um hey everyone glad you're all here this is the reasoning and reinforcement learning track uh on the afternoon of the last day of the AI engineer world's fair glad you're all here glad you're sharing it with us today what I'm going to talk about is uh a very specific case study um that we did uh this case study I'm going to talk about lessons lear... Read More
Key Insights
- Prompted models are the recommended starting point because they expose bugs in tools, data access, and the agent environment before training complexity is introduced. Prompt optimization may also produce adequate reliability, eliminating the need to build and debug a reinforcement-learning pipeline.
- A prompted baseline is the standard that reinforcement learning must beat. Establishing the strongest practical baseline makes later comparisons meaningful and shows whether specialization actually delivers better task performance than frontier models operating through prompts alone.
- ART-E is an email assistant that uses search and message-reading tools before answering a user’s question. This grounded workflow makes agent behavior observable because each query, returned message, selected email, and final answer can be evaluated within a specific task.
- The specialized Qwen 2.5 14B model initially performed much worse than the prompted models. Its early training gains reflected learning basic tool use, while later gradual improvements represented refinement of search, reading, and answer-generation behavior.
- The trained model reached 96% accuracy, compared with 90% for the best prompted model in the reported evaluation. The difference means the specialized system eliminated 60% of the errors made by that prompted baseline, which can materially strengthen the user experience.
- Smaller specialized models can improve unit economics because their reduced size makes inference cheaper. For a thousand searches, the reported prompted alternatives cost $55 and $8, while the specialized Qwen model reduced cost by another order of magnitude.
- Latency improvements came from both model size and learned behavior. The smaller model required less memory loading and computation, while training taught it to use more efficient queries and complete the task with fewer turns against the email database.
- Realistic environments and appropriate reward functions are the two recurring difficulties in reinforcement-learning projects. Training inputs, outputs, tools, and data must resemble production, while the reward must reliably distinguish successful agent behavior from poor results.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: When should reinforcement learning be used for an AI agent?
Reinforcement learning should be considered after a prompted model has been pushed as far as practical and still cannot meet the task’s reliability requirements. Starting with prompts helps uncover broken tools, missing data access, and other environmental defects separately from training-loop problems. If prompting already produces strong enough performance, training can be avoided, saving engineering time and computational expense.
Q: Why should agent development start with prompted models?
Prompted models provide a faster way to validate the complete agent environment before reinforcement learning is introduced. Developers can verify that tools work, required data is accessible, and the agent can achieve at least some success. Prompting also establishes a strong baseline, making it possible to determine whether a trained model genuinely improves accuracy, cost, or latency.
Q: How does the ART-E email assistant answer questions?
ART-E accepts a natural-language question about information contained in an email inbox. It uses an email search tool to find potentially relevant messages, receives search results, reads selected emails with another tool, and then produces a final answer. This sequence creates a concrete agentic task in which tool choices, retrieved evidence, and answer quality can all be examined.
Q: How did reinforcement learning improve the email agent?
The Qwen 2.5 14B model started significantly behind the prompted baselines. Training produced an early sharp improvement as the model learned basic tool-calling behavior, followed by a slower climb as its strategy became more effective. It eventually reached 96% accuracy and surpassed the best prompted result of 90%, eliminating 60% of that baseline’s errors.
Q: Why can a smaller specialized model cost less to operate?
A smaller model requires less memory loading and fewer matrix multiplications, so it can generate tokens more cheaply than a larger prompted model. In the reported benchmark, a thousand searches cost $55 with o3 and $8 with o4-mini. Moving to the specialized Qwen 2.5 14B model reduced the cost by another order of magnitude while retaining strong performance.
Q: How can reinforcement learning reduce agent latency?
Latency can fall for two complementary reasons. First, a smaller model can produce tokens faster because it performs less computation and loads less information from memory. Second, reinforcement learning can improve the agent’s operating strategy, teaching it to issue more efficient queries and use fewer back-and-forth turns with the email database before generating an answer.
Q: What makes a reinforcement-learning environment realistic?
A realistic environment reflects the conditions the agent will encounter after deployment. Its data, inputs, outputs, available tools, and tool behavior should closely match production use. If training conditions differ from actual operation, the agent may optimize behavior that earns rewards during training but does not produce the desired results when users rely on it.
Q: Why is the reward function critical when training an agent?
The reward function tells the training process whether the agent performed well or poorly. For the email assistant, it must provide a dependable way to judge whether the final answer is good after the agent searches and reads messages. An unsuitable reward directs optimization toward the wrong behavior, even when the environment and training procedure otherwise function correctly.
Summary & Key Takeaways
-
ART-E is a natural-language assistant that answers questions about an email inbox by searching messages, reading relevant emails, and producing a final response. Its development provides a concrete example of training an agent with reinforcement learning after prompt-based approaches had been tested, debugged, and improved as much as practical.
-
The trained model began from the relatively small Qwen 2.5 14B model and initially performed substantially worse than prompted alternatives. During training, it first improved sharply as it learned basic tool-calling behavior, then progressed more gradually until it surpassed every prompted baseline evaluated on the specialized email-question-answering task.
-
Specialization improved more than answer accuracy. The smaller model was cheaper and faster to run, while reinforcement learning encouraged more efficient searches and fewer interactions with the email database. The project required about a week of work from an experienced engineer, while the reported training run cost about $80 in GPU time.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Engineer 📚

Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator