How to use BM25 for agentic search effectively
TL;DR
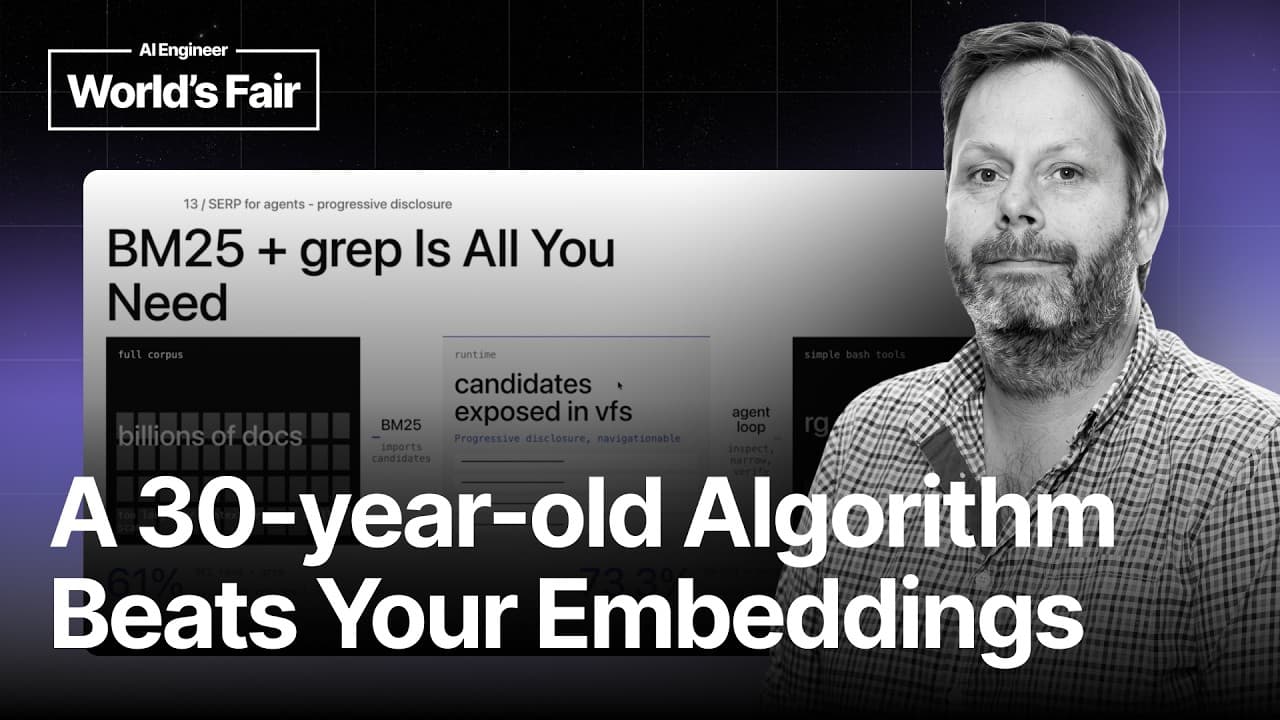
BM25 remains a simple lexical scoring function, but its effectiveness rises when paired with a powerful model that can generate long, precise queries and a robust harness that manages retrieval. The end result depends on retrieval quality and how the model formulates searches, with context limited by a small workspace yet expandable through dynamic retrieval strategies. This is demonstrated by a 830-question benchmark and a floppy-disk context analogy.
Transcript
[music] So great being here. Uh I'm Joe Bergam. I'm the CEO of Hornet Dev and I'm here today to talk about the unreasonable effectiveness of BM25 for Agentic Search. So how many of you heard about BM25 before? Is it new or is it Well, quite a few. So that's great. Uh I'm also watching the World Cup. Norway is playing there uh against the Ivory Coas... Read More
Key Insights
- BM25 is still the core scoring function, but its effectiveness now hinges on the user model and the retrieval harness that exposes search to the model.
- Agentic search is search inside an agent loop where a capable model formulates queries and uses tools to retrieve needed information.
- The model’s general knowledge allows it to generate longer, more specific queries than a human user would, changing how retrieval is performed.
- End-to-end accuracy depends on retrieval quality and the harness, not only on the model’s reasoning ability.
- The context window is limited, likened to a floppy disk of about 1.4 megabytes, so careful selection of what evidence to include is essential.
- Benchmarking with BrowseCom Plus shows that a simple BM25 baseline can be outperformed by more sophisticated retrieval configurations for long documents.
- Dynamic workspace expansion is proposed to scale retrieval to billions of documents by organizing retrieved fragments into a usable workspace.
- Long tail queries benefit from literal term matching and syntax learned from web search, making embedding-only approaches less attractive in some cases]
- Summary timestamped points are included to emphasize that the heuristic and tooling around retrieval are foundational to agentic search success.
- Overall, the talk argues for rethinking BM25 in the era of powerful models, where the user becomes the driver of effective search through structured tool use and query iteration.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is agentic search and why does it matter for retrieval
Agentic search is search inside an agent loop where an AI agent attempts to accomplish a task by formulating and executing queries to gather information. It matters for retrieval because the agent relies on a capable model, a harness to expose search functions, and a fast retrieval engine to operate over large document sets. The interaction between the model, tools, and the retriever determines end-to-end task success, not just the model’s reasoning ability.
Q: Why is BM25 described as a 30-year-old function making a comeback
BM25 is a lexical scoring function that has not changed, but its comeback is driven by a more powerful user—the modern AI model with general knowledge. This model can write long, targeted queries and leverage retrieved snippets efficiently. The combination means BM25 remains a strong baseline, while the new user capabilities allow it to perform better in agentic workflows.
Q: What role does the harness play in agentic search
The harness defines how retrieval is exposed to the model, enabling tool calling or code mode to access search results. It guides how queries are formed, how results are fed back into the agent, and how the overall retrieval loop progresses. A well-designed harness can significantly affect end-to-end accuracy by shaping the interaction between the model and the retriever.
Q: How does context window size influence retrieval effectiveness
The context window acts like a fixed workspace, roughly compared to a floppy disk in the talk, limiting how much retrieved information can be directly used. Because of this, the system must decide what retrieved documents to include, prioritizing evidence that will help the model answer the question without overwhelming the window.
Q: What is BrowseCom Plus and why is it relevant
BrowseCom Plus is a deep research benchmark with about 830 questions and a corpus of around 100,000 documents. It tests how well a model can use a simple search tool to retrieve snippets, then use those snippets to generate exact gold-reference answers. This benchmark illustrates the practical impact of retrieval quality on task accuracy.
Q: How do long queries change retrieval compared to AOL logs
Long queries are possible because the modern model has strong general knowledge and can generate lengthy, precise queries using site operators and web-search syntax. In contrast, AOL log data shows human users tend to search with short, few-term queries. The model’s ability to compose extended queries changes the retrieval dynamics.
Q: What are the tradeoffs between BM25 and embedding-based retrieval
BM25 remains simple and cheap, especially for literal term matching and inspectability of results. Embedding-based retrieval can capture semantic similarity but requires costly inference and more infrastructure. The talk notes that optimization must consider both cost and the model’s ability to inspect and understand why results were returned.
Q: What is dynamic workspace expansion and why is it useful
Dynamic workspace expansion is a concept to scale corpus interaction by expanding the workspace used by the agent. It enables the agent to manage information across billions of documents by organizing retrieved fragments in a structured workspace, allowing progressive disclosure and more effective search trajectories within agentic tasks.
Q: What is the main takeaway about using BM25 with agentic search
The main takeaway is that BM25 is still a strong baseline, but its effectiveness in agentic search depends on the powerful model and the retrieval harness. Long, precise queries generated by the model and robust retrieval strategies drive end-to-end task success, while context-window limits require careful evidence selection and workspace organization.
Summary & Key Takeaways
-
BM25 is presented as a stable scoring function whose value comes from how the model uses it and how the retrieval system is built around it, rather than changes to BM25 itself.
-
The talk emphasizes agentic search where an AI agent iterates through queries and retrieved snippets to accomplish tasks, highlighting the role of the harness and model capabilities.
-
A key takeaway is that the context window acts like a small workspace that must be populated strategically with retrieved documents to drive accurate results.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Engineer 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator