How to Build Low-Cost RAG with Gemini File Search
TL;DR
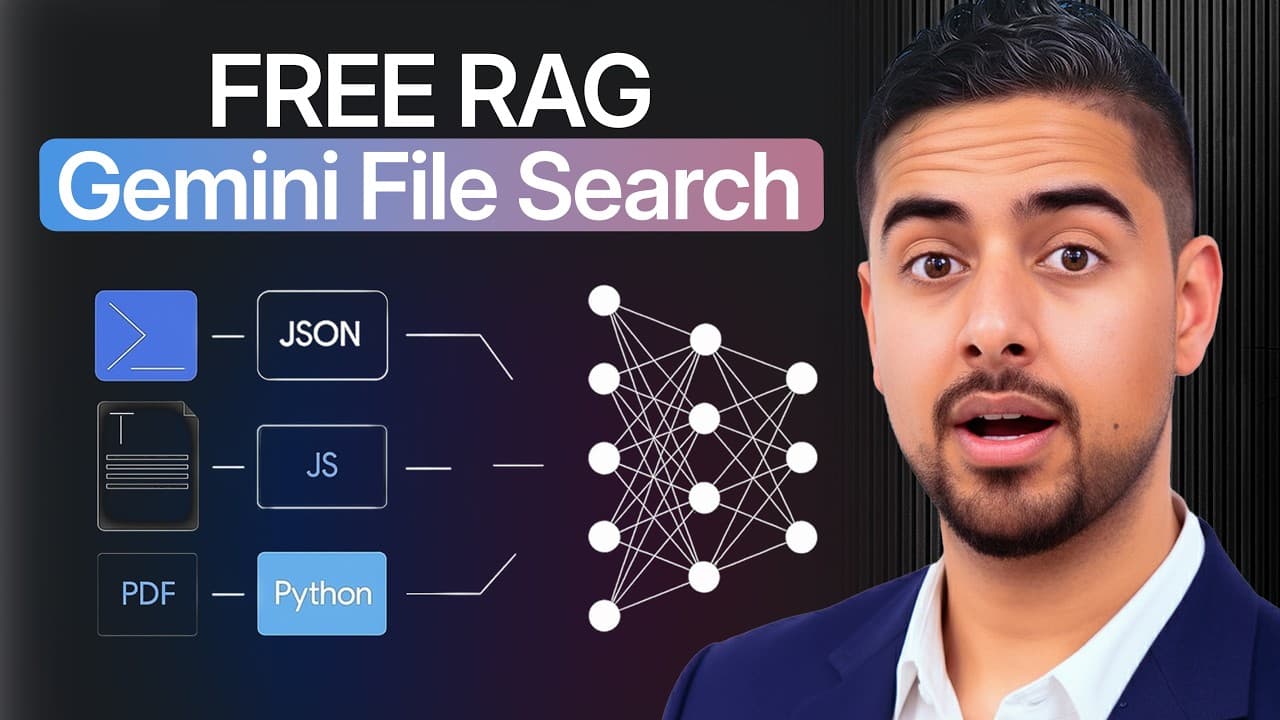
Gemini File Search API turns uploaded documents into a persistent, searchable knowledge base by automatically chunking, embedding, retrieving, and citing relevant passages. It supports grounded responses in AI Studio, n8n, and coding tools, while minimizing manual RAG infrastructure work and offering storage, querying, embeddings, and inference at costs described as substantially lower than competing managed options.
Transcript
Google just dropped their file search API, which not only makes Rag that much easier to do, but it's also some of the most aggressive pricing that I've seen from a non-opensource provider. Storage, querying, and creating embeddings is practically free, especially when you compare it to a lot of the other providers we have on the market. And this me... Read More
Key Insights
- Gemini File Search API is a managed RAG service that handles document chunking, embedding, indexing, semantic retrieval, grounding, and citations after users upload supported files, reducing the number of pipeline components they must configure themselves.
- A file search store is persistent, so uploaded documents remain available for later queries as long as the application retains the store ID needed to reference that collection of files.
- AI Studio provides an easy starting point for file search, allowing users to upload a document, index it in under 10 seconds in the demonstrated case, ask questions, and inspect citations and retrieved chunk previews.
- Grounded generation is designed to base an answer on passages retrieved from the file store instead of relying on the language model's general knowledge, increasing the likelihood that unsupported questions receive an explicit statement that no relevant information was found.
- Intelligent chunking abstracts decisions about document segmentation and chunk overlap. Gemini selects how to divide uploaded content, which simplifies implementation but gives developers less control over the internal preparation process.
- Semantic retrieval uses cosine similarity to match a question with document chunks and return top-K results, such as the top five or top 10 passages, before the language model converts the grounded context into a natural-language answer.
- An n8n file-search workflow can accept a PDF, DOCX, or text file through a form, extract and propagate its binary data, create a named file store, upload the file through an API endpoint, and expose the store to an AI agent.
- PDF is the preferred upload format in the demonstrated workflow because DOCX files appeared less reliable. Once indexed, multiple documents can be searched together, with grounding metadata showing the retrieved chunks and sources used to construct each response.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How does Gemini File Search API create a RAG pipeline?
Gemini File Search API accepts an uploaded document and automatically handles the main preparation stages of retrieval-augmented generation. It decides how to chunk the content, creates embeddings, indexes the chunks in a file search store, and performs semantic retrieval when a question arrives. The retrieved passages become grounded context for a Gemini model, which produces a natural-language answer with citations and source information.
Q: How can I use Gemini File Search in AI Studio?
In AI Studio, enable an API key with a payment method, open the available file-search demonstration or build interface, and upload a supported document. The service indexes the file, creates its chunks and embeddings, and adds it to the knowledge base. You can then select a suggested prompt or write your own question, receive a grounded response, and inspect citations, page references, and previews of retrieved chunks.
Q: What does grounding mean in Gemini File Search?
Grounding means that the generated response should be supported by information retrieved from the indexed files rather than produced solely from the model's existing knowledge. The file-search response includes grounding metadata and grounding chunks that reveal relevant passages. When the demonstrated agent was asked about Lucky Charms, which did not appear in its documents, it reported that it could not find supporting information instead of inventing an answer.
Q: How do citations work with multiple uploaded documents?
Citations identify the document passages that Gemini considered relevant when constructing an answer. In AI Studio, users can open the sources section and preview retrieved chunks, including the pages from which they came. Although the initial demonstration used one file, the same mechanism can work across 10, 15, or 20 files and reveal the leading sources used for a particular response.
Q: How can I connect Gemini File Search API to n8n?
An n8n workflow can begin with a form that accepts a PDF, DOCX, or text file. JavaScript then extracts the binary information needed by later nodes. An HTTP request creates a named file search store using the documented API URL and API key. Another request uploads the binary file through the upload endpoint, after which an AI agent can query the resulting store through a document-search tool.
Q: Why are PDFs preferred over DOCX files in the workflow?
PDFs are preferred because the presenter observed that the demonstrated workflow did not handle DOCX files as reliably. The upload form can accept PDF, DOCX, and text files, but PDF was recommended over the alternatives for practical use. After submission, the workflow preserves the selected file as binary data, sends it to the upload endpoint, and imports it into the persistent file search store for querying.
Q: How does semantic search retrieve answers from a file store?
A user's question enters the file-search pipeline and is compared with embedded document chunks through semantic vector search using cosine similarity. The system selects top-K matches, which could mean the top five or top 10 passages. Those passages form grounded context for the language model. Gemini then contextualizes the retrieved material into a human-readable response while retaining metadata about the chunks and sources that supported it.
Q: What are the main tradeoffs of managed file search for RAG?
Managed file search reduces implementation work because Gemini controls chunking, overlap, embedding creation, indexing, retrieval, and citation generation. This lets developers focus on uploading documents and using the resulting knowledge base. The tradeoff is reduced control over operations under the hood, including how documents are divided. The service is presented as especially economical for storage, querying, embeddings, and scaled RAG pipelines compared with other managed providers.
Summary & Key Takeaways
-
Gemini File Search API provides a managed RAG pipeline for text files and PDFs. After a file is uploaded, Gemini automatically divides it into chunks, creates embeddings, indexes the content in a persistent file store, and makes relevant passages available for grounded answers with citations and source previews.
-
AI Studio offers an accessible demonstration of the workflow. A user can enable a funded API key, upload a document, wait for indexing, and ask suggested or custom questions. The generated answer can include a structured summary, citations, source pages, and previews of the document chunks used as evidence.
-
The API can also support automated workflows and applications. The demonstrated n8n process accepts uploaded files, preserves their binary data, creates a file search store, uploads documents through API endpoints, and lets an AI agent query them. Coding assistants can use the API documentation to help build similar integrations and micro-SaaS interfaces.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Mark Kashef 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator