How to Give Claude Persistent Memory With Pinecone
TL;DR
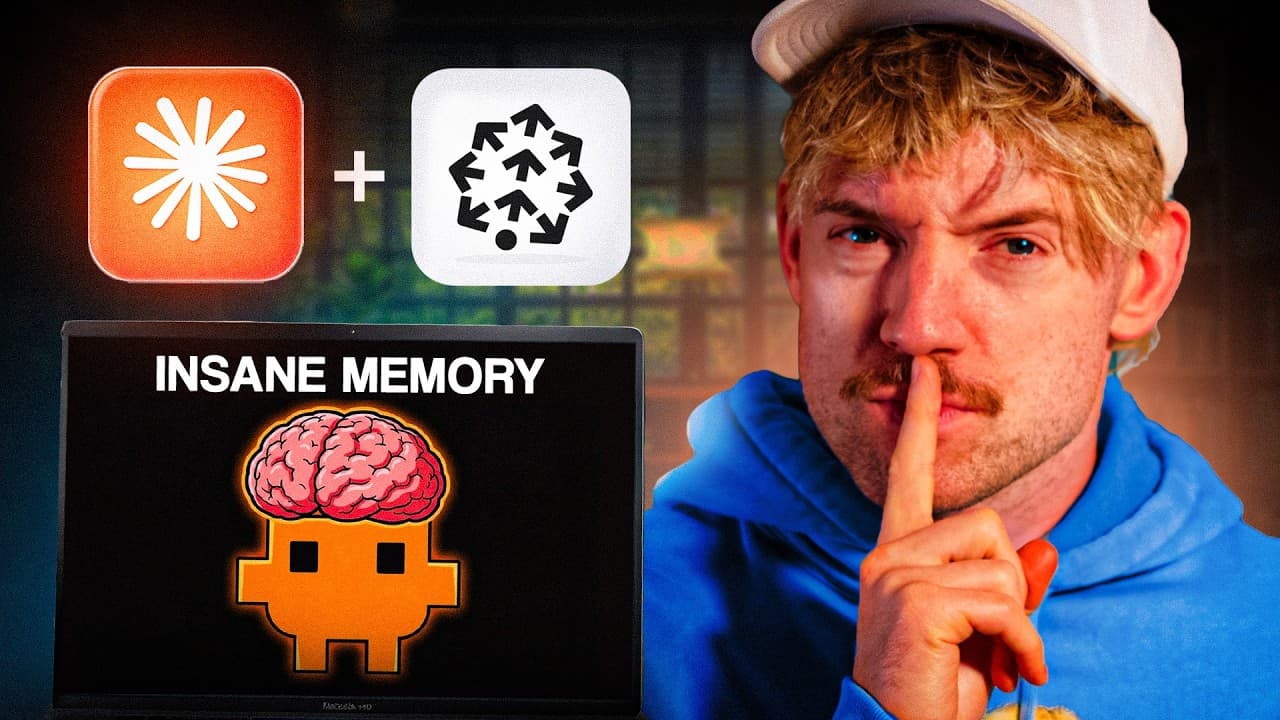
Connect Claude to Pinecone, place relevant files in a project, create an API key, and ask Claude to build an index with the multilingual E5 instruct model. The resulting RAG system stores vectorized knowledge and retrieves information by meaning, letting Claude reference selected documents without loading an entire knowledge library into every conversation.
Transcript
Imagine if Claude knew everything about you and never forgot a single conversation. I discovered a system that does exactly this. And it is a superpower, but most people don't even know that this exists. So, in this video, I'm going to show you exactly how to create this unlimited memory system with Pine Cone that solves Claude's greatest problem t... Read More
Key Insights
- RAG is a three-step process that stores information, retrieves relevant material when needed, and combines that material with Claude's existing capabilities to generate an answer for a particular project.
- Semantic search is based on intended meaning rather than exact keyword matches. A query about pricing strategy can therefore retrieve material discussing monetization, revenue models, or offer stacking, even when the source does not repeat the precise query wording.
- Pinecone serves as the database for vectorized knowledge in the demonstrated system. The setup begins by creating an account, opening the API keys section, generating a new key, and making that credential available to Claude.
- Vectorizing knowledge converts selected source files into information that can be searched and retrieved through the Pinecone index. The demonstrated sources include PDFs, books, company documents, YouTube material, and other personal or business files.
- An IDE provides a visual project view that makes it easier to see and organize the files being added. The same general process can also be performed through Claude, but the presenter prefers the IDE's visible file structure.
- The multilingual E5 instruct model is used when Claude creates the new Pinecone index in the demonstration. The user supplies an index name, identifies the files to vectorize, and asks Claude to perform the indexing work.
- API keys can be placed in an environment file instead of pasted directly into chat. This keeps the Pinecone credential out of the visible chat logs while still allowing the project to authenticate with the service.
- A completed setup can be checked in Pinecone's databases area. Refreshing the page should reveal the newly created index, confirming that Claude created the database and indexed the selected material successfully.
- More videos from this channel:
- More from this channel: Jack Roberts
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How do you give Claude persistent memory with Pinecone?
Create a Pinecone account, generate an API key, and collect the documents or other knowledge you want Claude to reference inside a project. Then ask Claude to create a new Pinecone index, use the multilingual E5 instruct model, and vectorize those files. After indexing, Claude can retrieve relevant stored material through a RAG workflow instead of loading every source into each conversation.
Q: What is RAG in a Claude memory system?
RAG is a workflow that stores information, retrieves the material relevant to a question, and combines that retrieved knowledge with Claude's capabilities to generate a response. The transcript compares it to a librarian who selects the right books from a large library, saving the AI from reading the complete collection from scratch whenever the user asks something.
Q: How does semantic search improve Claude's memory retrieval?
Semantic search finds information according to meaning rather than depending only on exact words. If a user asks about pricing strategy, the retrieval system can also search for connected ideas such as monetization, revenue models, and offer stacking. This broadens retrieval to conceptually relevant passages that a strict keyword search might fail to identify.
Q: What information can be stored in the Pinecone knowledge base?
The presented approach can store vectorized versions of many kinds of knowledge, including books, PDFs, company documents, YouTube material, personal files, and conversation history. Users first gather the sources they expect to reference, place them in the project, and then instruct Claude to vectorize them into a Pinecone index for later semantic retrieval.
Q: How do you create the Pinecone index for Claude?
Open Pinecone, create an account, visit the API keys section, and generate a new key. In the Claude-enabled project, provide a prompt asking Claude to create a new index, specify multilingual E5 instruct as the model, name the index, and identify the PDF or other files to vectorize. Claude can then create and populate the database.
Q: Where should the Pinecone API key be stored?
The Pinecone API key can be placed in an environment file used by the project. The presenter recommends this approach because it avoids putting the credential directly into the chat logs. Once the key is available to the project, Claude can use it to connect to Pinecone, create the requested index, and vectorize the selected files.
Q: Why use an IDE when building Claude's memory system?
An IDE gives the user a visual view of the project files being assembled and indexed. Documents can be placed together in the project, inspected from the file panel, and passed to Claude from the same workspace. The transcript says the process can also be completed through Claude, but presents the IDE as the easier option for visually organizing knowledge.
Q: How can you verify that Claude indexed the documents correctly?
Return to Pinecone after Claude reports that indexing is complete, open the databases area, and refresh the page. The newly named database or index should appear there. In the demonstration, the presence of the Los Angeles index confirms that the database was created and the selected PDF was processed for retrieval through the memory system.
Summary & Key Takeaways
-
The proposed memory system combines Claude with Pinecone to store large amounts of personal or business knowledge. Documents, books, YouTube material, conversations, and other files can be vectorized so Claude can retrieve relevant information later instead of requiring the entire collection to be loaded into its working context.
-
RAG is described through a library analogy. Without retrieval, an AI would need to read every book to answer a question. With retrieval, a semantic search system acts like a librarian that finds material connected to the intended meaning, including related concepts that do not contain the user's exact keywords.
-
The setup starts by creating a free Pinecone account and copying a new API key. In an IDE with Claude enabled, users collect files in a project, provide the key through an environment file, and instruct Claude to create an index, use multilingual E5 instruct, and vectorize the selected documents.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Jack Roberts 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator