How Close are We to Automated AI Research?
TL;DR
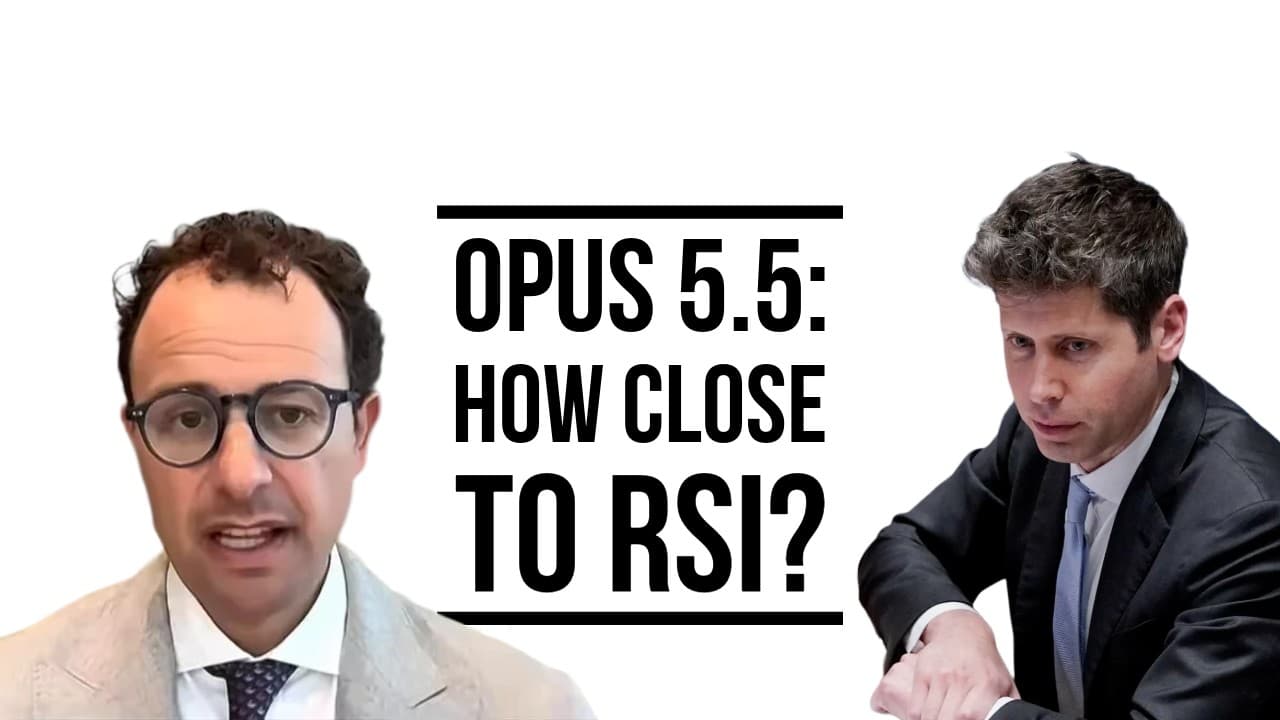
Opus 5.5 represents a strong frontier capability but does not yet double the pace of AI development. It shows faster internal model work and cheaper deployments, yet Anthropic says it cannot fully substitute researchers. The discussion spans benchmarks, RSI pace policy changes, and how labs balance speed, safety, and accountability while releasing new models.
Transcript
Claude Opus 5.5 is Anthropic's sudden reverberating response to the already astounding Astra model from OpenAI. And of course, it's easy to get lost again in the flood of flashy demos, benchmark scores, and claude crafted autobiographical animations. completely going to admit that I am not immune either, having spent several hours exploring a Final... Read More
Key Insights
- Opus 5.5 shows strong performance but not yet two times faster in AI development according to Anthropic’s measures.
- Opus 5.5 is behind Astra on some tasks yet ahead on others, indicating mixed progress in benchmarking.
- A stronger internal model can enable faster learning for smaller models through techniques like kernel and systems engineering.
- Anthropic bans Opus 5.5 from kernel development to protect advantaged capabilities and prevent others from copying them.
- Frontier models are accelerating the pace of model releases and making training cheaper, signaling deeper internal strength across labs.
- The term Recursive Self Improvement RSI is used to describe automated AI research and its evolving goals.
- Public climate around AI research is highly dynamic with policy shifts and new incidents influencing how labs progress.
- The Cobbench benchmark presents a realistic measure of how close models are to substituting researchers, with current scores far from the 85% threshold.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is Opus 5.5 in relation to other frontier models like Astra and Fable 5.1?
Opus 5.5 is a strong competitor among frontier models, performing well on some tasks and showing cost reductions, but it does not uniformly outperform Astra. The video notes that on Terminal Bench Science 0.1 Opus 5.5 trails Astra by about 6 percent, while in other areas it is ahead of Fable 5.1. This mixed performance supports the view that frontier models are advancing unevenly across benchmarks.
Q: Why does Anthropic place a ban on Opus 5.5 for kernel development, and what does this imply?
Anthropic bans Opus 5.5 from being used for kernel development because they consider the capability valuable and potentially dangerous if copied by others. This policy suggests a deliberate control of where powerful techniques are demonstrated and how capabilities are transferred between models, highlighting concerns about competitive advantage and safety implications in AI research.
Q: What is the Cobbench benchmark and what does its 56% score indicate?
Cobbench is an internal Anthropic benchmark that tests a model’s ability to diagnose root causes using snapshots of historical logs and internal messaging. A 56 percent score indicates the model can diagnose about half of the targeted internal research challenges, which is a step above earlier iterations but well short of the 85 percent benchmark required to substitute for researchers.
Q: How does the video describe RSI, Recursive Self Improvement, and its relevance to AI research?
RSI refers to the goal of automated AI research where models autonomously improve themselves. The video frames RSI as a moving target with evolving expectations, noting that headlines about RSI often outpace practical demonstrations. The discussion emphasizes that true automated improvement must balance speed with safeguards and demonstrable reliability.
Q: What policy shifts related to AI development are highlighted in the video, and why do they matter?
The video highlights changes to Anthropic’s Responsible Scaling Policy and related documents, reflecting how labs adjust safety and governance as capabilities evolve. These shifts matter because they influence deployment decisions, model usage restrictions, and the pace at which models can be scaled up, affecting both innovation and public accountability.
Q: How do labs view the pace of AI development in relation to safety and security measures?
Labs acknowledge that faster development needs to be matched with safety and security measures. The discussion references commitments about not training or deploying models unless safeguards are in place, indicating a cautious approach where progress is weighed against potential misalignment, safety risks, and adversarial threats.
Q: What is the significance of the Frontiers Code benchmark mentioned in the video?
Frontiers Code benchmark is significant because it focuses on long horizon coding tasks, a domain where Opus 5.5 might outperform Astra. This benchmark demonstrates that different models excel in different areas, affecting the overall assessment of which model is most capable for AI research tasks and how rapid improvements translate into practical research capabilities.
Q: What overall message does the video convey about automated AI research and the near future?
The video conveys that automated AI research is advancing but not yet ready to replace human researchers. It emphasizes that internal models, benchmark results, and safety policies will shape how quickly automation can meaningfully contribute to AI development. The trajectory suggests gradual integration of automation with continued emphasis on accountability and governance.
Summary & Key Takeaways
-
Opus 5.5 demonstrates significant internal model strength and cost reductions, yet it is not enough to substitute human researchers according to Anthropic’s benchmarks. The video argues that frontier labs are accelerating but face governance, safety, and reliability constraints. The overall trend is rapid model releases with evolving safety policies.
-
The video analyzes how benchmarks like Terminal Bench Science and Frontiers Code shape perceptions of progress and how the pace of AI development is measured internally. It highlights the tension between innovation speed and safeguards in frontline labs.
-
The discussion concludes that automated AI research may emerge gradually, with internal models assisting humans but not fully replacing them yet, as policy and practical constraints evolve in response to new capabilities and external scrutiny.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from AI Explained 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator