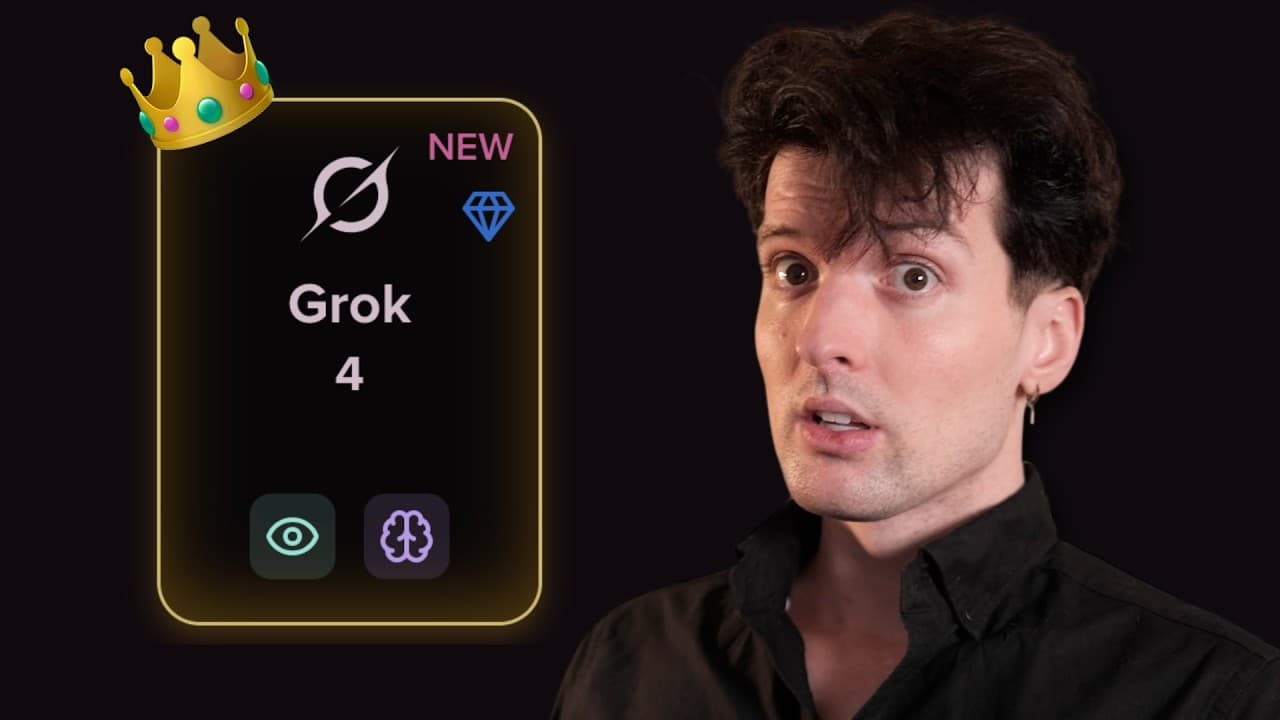
Is Grok 4 the Best AI Model Right Now?
TL;DR
Grok 4 places first or second in nearly every benchmark, making xAI a serious LLM competitor for the first time. It scored 16% on the ARC-AGI test (roughly double any prior model), hit 24% on Humanity's Last Exam, and was trained on tool calls for reliable function calling. It is a strong reasoning model but slow, and not the best at code yet.
Transcript
So, Grock 4 just dropped. Normally, I would take the opportunity to make fun of it a whole bunch. And don't worry, we're going to do that. I don't like how XAI does things, generally speaking. That said, I did not think this would happen. Gro 4 is the best model ever made. It is coming in first or second place in every single benchmark, and I didn'... Read More
Key Insights
- Grok 4 is the best model ever made according to the reviewer, coming in first or second place in every single benchmark and turning xAI into a serious competitor it was not before.
- ARC-AGI is one of the hardest AI benchmarks, using visual pattern puzzles humans solve easily but AI historically fails; Grok 4 hit 16%, nearly double Claude 4 Opus's groundbreaking 8%.
- Grok 4 is a slow reasoning model that does not show its reasoning tokens unless you use the new SuperGrok subscription priced at $300 a month.
- xAI trained Grok 4 on tool calls during training rather than only through later reinforcement, resulting in far more reliable tool and function calling than previous Grok models and many competitors.
- Grok 4 is not the best at code; xAI teased a separate coding model dropping supposedly between August and September, though xAI timelines should be bumped by two months to a year.
- On Humanity's Last Exam, a general reasoning and knowledge test, Grok 4 scored 24%, above the 21% that 2.5 Pro reached and the roughly 20% mark first broken by o3.
- Grok 4 has quirks: during SnitchBench runs it randomly output 40 to 50 pages of empty new lines as text for no reason, and it can time out because it is so slow.
- Grok 4 passed the hexagon ball test with flying colors, which was unexpected since Grock models have historically not been great at code, though Claude still feels like the king.
- Grok 3 was a stupid non-reasoning model while Grok 3 Mini was a surprisingly decent, fast, cheap reasoning model; Grok 4 is described as just a good reasoning model.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: Is Grok 4 the best AI model right now?
According to the reviewer, Grok 4 is the best model ever made, coming in first or second place in every single benchmark. He did not expect this and admits xAI is now a real, serious competitor when it was not at all before. That said, he frames this within the LLM race where a new leader appears and then something else surpasses it shortly after, so its lead may be temporary.
Q: How did Grok 4 perform on the ARC-AGI benchmark?
Grok 4 scored 16% on the general ARC-AGI test, nearly double what any model had done before. ARC-AGI is one of the hardest AI benchmarks, made of visual pattern puzzles that humans usually solve at 100% but AI has historically failed. Incredible models like GPT-4.5 or o1 Pro got only 1 to 2%, and Claude 4 Opus was groundbreaking at 8%, so Grok 4's 16% is described as kind of nuts.
Q: How much does Grok 4 cost to access?
The new SuperGrok subscription, which includes SuperGrok Heavy, is priced at $300 a month, which the reviewer criticizes as xAI seeing OpenAI's $200 plan and charging 50% more. Only with this subscription do you see the reasoning tokens. Alternatively, you can access Grok 4 through the T3 Chat app for $8 a month, and using code GET-GROKKED at checkout gets you one month for just $1.
Q: Is Grok 4 good at coding?
Grok 4 is not the best at code. The reviewer says if you are looking for a new model to code with, you have to wait a bit. It did surprisingly pass the hexagon ball test with flying colors, which was unexpected given Grock models' history, but it still has weird quirks and Claude still feels like the king. xAI teased a separate dedicated coding model supposedly dropping between August and September.
Q: Why is Grok 4 better at tool calls than previous models?
xAI trained Grok 4 on tool calls during the training process itself, not just as reinforcement applied later. Their scaling graphs showed tool calls used throughout training, which made the model far more reliable at calling tools and functions than previous Grock models and many others. The reviewer ran thousands of tool call tests with SnitchBench and found it usually called the tool successfully and much more accurately.
Q: What are the downsides or quirks of Grok 4?
Grok 4 is slow, which is its main drawback, and it can take too long to generate and time out. It also has strange quirks: during SnitchBench work it randomly output hundreds of new lines as empty text for no reason, forcing the reviewer through 40 to 50 pages of blank output. He describes it as a Grock model that is quirky, weird, and stupid in its own unique ways, though still impressive.
Q: What future models did xAI tease during the presentation?
xAI teased a timeline including a new coding model supposedly dropping between August and September, a multimodal agent around early September to October, and a video generation model by October. However, the reviewer warns that given how xAI handles timelines, you should bump every one of those estimates by somewhere between two months and a year before expecting them.
Q: How does Grok 4 compare to other models on specific benchmarks?
On the reasoning and knowledge MMLU test, Grok 4 is right behind Opus Thinking. On the GPQA Diamond general science test, it is leading the pack. On Humanity's Last Exam it scored 24%, above 2.5 Pro's 21%. On other code tests it performed slightly worse than lead models and even slightly underperformed Grok 3 Mini Reasoning, but it crushed the AIME math test with an industry-leading score.
Q: How did Grok 3 and Grok 3 Mini compare before Grok 4?
Grok 3 was a really stupid non-reasoning model. Grok 3 Mini, by contrast, was a surprisingly decent reasoning model that ran really fast and, the reviewer argues, is a bit underrated because it is weird and quirky but cheap and fast. Grok 4 is described as just a good reasoning model, a clear step up, though interestingly Grok 3 Mini Reasoning still slightly outperformed Grok 4 on one particular code test.
Summary & Key Takeaways
-
Grok 4 just dropped and, despite the reviewer's dislike of how xAI operates, it lands first or second in every benchmark. This makes xAI a serious LLM player for the first time, even if it will likely only lead the pack briefly in the ongoing AI race.
-
The standout result is ARC-AGI, a benchmark of visual pattern puzzles humans solve easily but AI struggles with. Models like o1 Pro scored 1 to 2%, Claude 4 Opus hit a groundbreaking 8%, and Grok 4 nearly doubled that at 16%. It also scored 24% on Humanity's Last Exam.
-
Grok 4 is slow and quirky, sometimes outputting pages of empty lines. It is not the best at code, but xAI trained it on tool calls, making function calling reliable. Pricing is steep at $300 a month for SuperGrok, or you can try it through T3 Chat for $1 the first month.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Theo - t3․gg 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator