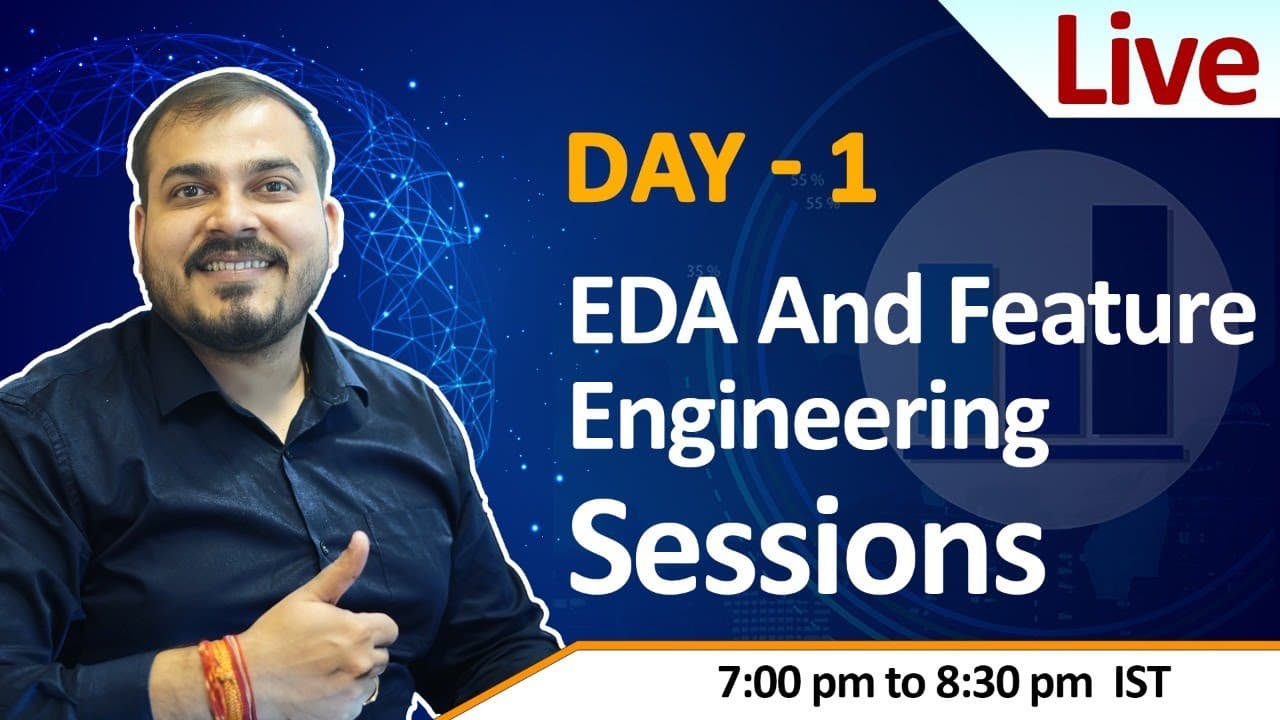
How to Perform EDA on the Zomato Dataset
TL;DR
Start exploratory data analysis by loading the Zomato CSV with pandas using Latin-1 encoding, then inspect its rows, columns, data types, and null values with head, columns, and info. Use describe to summarize numerical features through statistics such as the mean, standard deviation, minimum, percentiles, and maximum before proceeding to deeper analysis or feature engineering.
Transcript
hello guys i hope am i audible hello everybody okay so if you are hit like everyone and today we are going to do a lot of amazing things with respect to eda so so zomato dataset exploratory data analysis right we are going to complete this today so before we start please make sure that you download the data set hit like and yes we will uh just let ... Read More
Key Insights
- Exploratory data analysis is a process of examining what a dataset communicates through its columns, values, types, missing entries, and statistical distributions. The instructor emphasizes that useful basic observations can still be made even when the analyst has limited knowledge of the dataset's domain.
- The working environment uses pandas, NumPy, matplotlib, and seaborn as its main Python libraries. Inline matplotlib output is enabled so charts and other visualizations can be displayed directly within the notebook while the Zomato dataset is being investigated.
- The supplied materials include a Zomato CSV file, a country-code spreadsheet, and multiple JSON files. The transcript states that the JSON content has already been converted into the CSV, while the conversion script is reserved for a later class.
- The Zomato CSV requires Latin-1 encoding in the demonstrated pandas read_csv call because attempting to read it with the default UTF-8 decoding produces a codec error. The instructor notes that encoding requirements depend on the individual file and should be investigated through errors and documentation.
- The DataFrame's columns include restaurant ID, restaurant name, country code, city, address, locality, longitude, latitude, average cost for two, and currency. Reviewing column names is presented as an early step for understanding the information contained in a dataset.
- The pandas info method reports the available columns, their data types, and whether their entries are non-null. Integer columns appear as int64, floating-point columns appear as float types, and object columns may represent strings, categories, or general text values.
- The pandas describe method summarizes numerical features with count-related and distribution statistics, including the mean, standard deviation, minimum, 25th percentile, 50th percentile, 75th percentile, and maximum. In the demonstrated default output, object and other categorical features are not included.
- The five-number summary consists of the minimum, 25th percentile, 50th percentile, 75th percentile, and maximum values. The session connects these descriptive values with constructing box plots, making them useful for understanding the distributions of numerical variables in the Zomato data.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How do you load the Zomato dataset with pandas?
Import pandas and call pd.read_csv with the Zomato CSV file path. In the demonstrated notebook, the initial read produces a UTF-8 codec error, so the call is repeated with encoding set to Latin-1. Assign the resulting table to a DataFrame such as df, then run df.head() to confirm that the records and columns were loaded.
Q: Why does the Zomato CSV need Latin-1 encoding?
The demonstrated Zomato CSV cannot be decoded successfully through the initial read_csv call because pandas reports a UTF-8 codec error at a specific byte position. Setting the encoding argument to Latin-1 allows this particular file to load. The instructor cautions that Latin-1 is suitable here but is not necessarily the correct encoding for every CSV file.
Q: Which Python libraries are used for this EDA session?
The notebook imports pandas as pd, NumPy as np, matplotlib.pyplot as plt, and seaborn. Pandas is used to read and inspect the tabular data, while matplotlib and seaborn are prepared for visualization. Matplotlib inline is also enabled so generated images and plots can appear directly within the notebook during the exploratory analysis.
Q: What should you inspect first during exploratory data analysis?
Begin by understanding what the data contains rather than immediately applying complex operations. The session recommends viewing sample rows, listing the columns, checking data types, and identifying non-null or missing entries. These checks show how the table is structured and help distinguish numerical features from object columns that may hold categories, text, or strings.
Q: What information does pandas df.info provide?
The df.info method provides a structural overview of the DataFrame. It displays the column names, the number of non-null entries, and the data type assigned to each column. In this dataset, integer features appear as int64, coordinates can appear as floating-point values, and object columns may contain categorical variables, strings, or broader text data.
Q: What statistics does pandas describe calculate?
The describe method reports descriptive statistics for the dataset's numerical features. The displayed measures include the mean, standard deviation, minimum, 25th percentile, 50th percentile, 75th percentile, and maximum. These figures help summarize the location and spread of numerical values. The default demonstrated output does not include object, categorical, or general text columns.
Q: How is the five-number summary related to a box plot?
The five-number summary uses the minimum, 25th percentile, 50th percentile, 75th percentile, and maximum of a numerical feature. The instructor connects these values to the construction of box plots. Because pandas describe reports these percentile and boundary statistics, its output can support an initial review of numerical distributions before creating corresponding visualizations.
Q: What files are included with the Zomato analysis dataset?
The downloadable materials include zomato.csv, a country-code spreadsheet, and multiple JSON files. According to the session, the JSON-formatted source has already been converted into the Zomato CSV through a Python script. The current lesson focuses on reading the CSV and spreadsheet, while the process for converting JSON into CSV is deferred to an upcoming class.
Summary & Key Takeaways
-
The session begins by importing pandas, NumPy, matplotlib, and seaborn into a notebook, with inline plotting enabled so visualizations appear inside it. The Zomato CSV is then loaded into a pandas DataFrame. Because the default UTF-8 decoding fails, the instructor specifies Latin-1 as the encoding for this particular file.
-
Basic exploratory analysis starts by examining the DataFrame with head, columns, and info. These operations reveal sample records, available feature names, data types, non-null counts, and potential missing values. The dataset contains restaurant identifiers, names, country codes, cities, addresses, localities, coordinates, costs, currencies, and other restaurant-related features.
-
The describe function generates statistics for numerical columns, including the mean, standard deviation, minimum, 25th percentile, median, 75th percentile, and maximum. These measures support a five-number summary and can inform box plots. Object columns require separate attention because they may contain strings, categorical values, or other text-based information.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Krish Naik 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator