How good is GPT-5.2 really and where does it fail
TL;DR
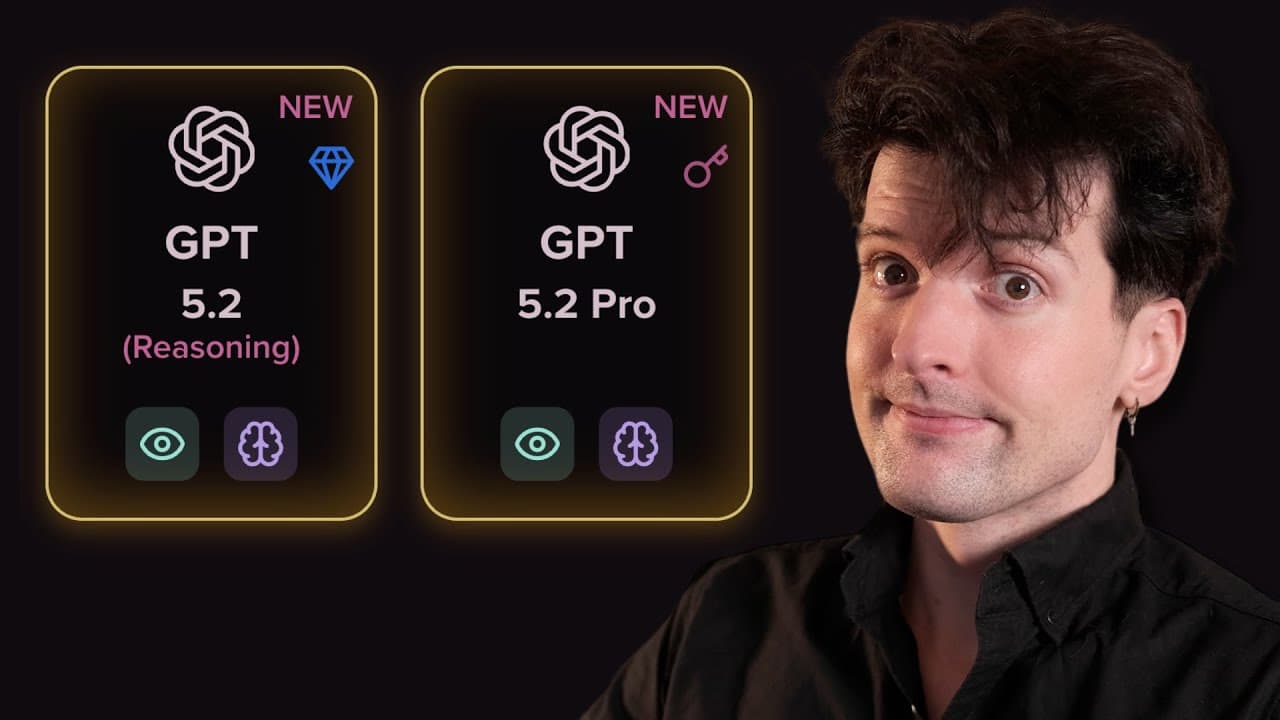
GPT-5.2 shows strength in code and tool usage and strong ARC AGI scores, but it also has notable regressions in certain reasoning tasks and skateboard trick benchmarks. The reviewer highlights speed issues, timing out on some tasks, and the impact of different reasoning settings, making its performance nuanced rather than uniformly superior.
Transcript
Where's the guy with the counter? Because there's a new best new model. Yes, really. GPT 5.2 just dropped and it is really, really good. Which is why it is uh Wait, what? Skatebench shows it as a huge regression. What's going on? I thought this was the best new model. Well, in many ways it is, but in a handful of important ones, it isn't. And I hav... Read More
Key Insights
- GPT-5.2 is better at code and tool calls according to the video.
- The model exhibits a significant regression in three dimensional spatial reasoning under default reasoning settings.
- Benchmarks show GPT-5.2 improving on some tasks but regressing on others depending on the task and configuration.
- OpenAI GPT-5.2 Pro High achieves high ARC AGI scores but with high per task costs and longer run times.
- Skatebench results depend heavily on model harness settings and reasoning level.
- The reviewer notes that benchmark outcomes vary widely across different evaluation suites.
- There is a tension between raw performance numbers and practical usability due to speed and timeout issues.
- Clerk is promoted as an authentication and payments solution as part of the sponsorship, illustrating real world integration considerations.
- More videos from this channel:
- More from this channel: Theo - t3․gg
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is GPT-5.2 good at, according to the video?
GPT-5.2 is reported as being better at code and tool calls, and it performs very well on ARC AGI scores in some configurations. The reviewer notes substantial improvements in those areas, indicating that the model handles development tasks and complex tool interactions more effectively than some prior versions.
Q: Where does GPT-5.2 show regressions?
The video highlights a regression in three dimensional spatial reasoning when using lower reasoning settings, such as the default. This regression affects tasks like naming skateboard tricks, where the model’s performance drops significantly compared to GPT-5.1 and earlier versions, illustrating that higher reasoning settings can dramatically alter results.
Q: What benchmarks are discussed and what do they show?
Benchmarks discussed include Skatebench and ARC AGI, among others. Skatebench showed a large regression in certain spatial reasoning tasks, while ARC AGI scores for GPT-5.2 Pro High reached high levels at much lower costs per task. The video emphasizes that different benchmarks tell different parts of the story.
Q: How does model speed impact usability?
The reviewer points out that GPT-5 series models can be slow, especially the pro variants, sometimes taking tens of minutes per response. This affects practical usability, making even strong performance numbers less impressive in real time workflows where quick feedback matters.
Q: What does the video say about API timeouts and reliability?
API timeouts are noted as a problem in verifying certain model outputs, with some prompts timing out or taking long to complete. This undermines reliability in practice and is presented as part of the broader discussion of what makes the model’s performance inconsistent across tasks.
Q: What is the role of reasoning settings in GPT-5.2 performance?
Reasoning settings heavily influence results: default settings may suppress reasoning and cause lower scores on certain tasks, while enabling higher reasoning can improve outcomes but at a higher cost per request. The video uses skateboard trick tasks to illustrate this effect.
Q: How does the video describe the relationship between benchmarks and real world use?
The video emphasizes that benchmarks are nuanced and task dependent. While some benchmarks show strong improvements, others reveal regressions or slower speeds, indicating that a model might excel in some areas while underperforming in others, which matters for choosing the right tool for a given job.
Q: What sponsorship and real world tools are mentioned?
The sponsor Clerk is presented as a solution for authentication, authorization, and payments, illustrating practical integration benefits for developers building real applications. The video uses Clerk as an example of how modern tooling can simplify building secure, payable features in apps. The promotional content is tied to practical use cases.
Summary & Key Takeaways
-
GPT-5.2 delivers strong performance in coding, tool use, and certain benchmarks while showing regression in spatial reasoning benchmarks like skateboard trick naming under default settings.
-
The video stresses that speed can be a major pain point, with some pro models taking long to respond and certain tasks timing out, complicating real world use.
-
The overall takeaway is that GPT-5.2 is powerful but not universally better, requiring careful evaluation of use cases and settings.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Theo - t3․gg 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator