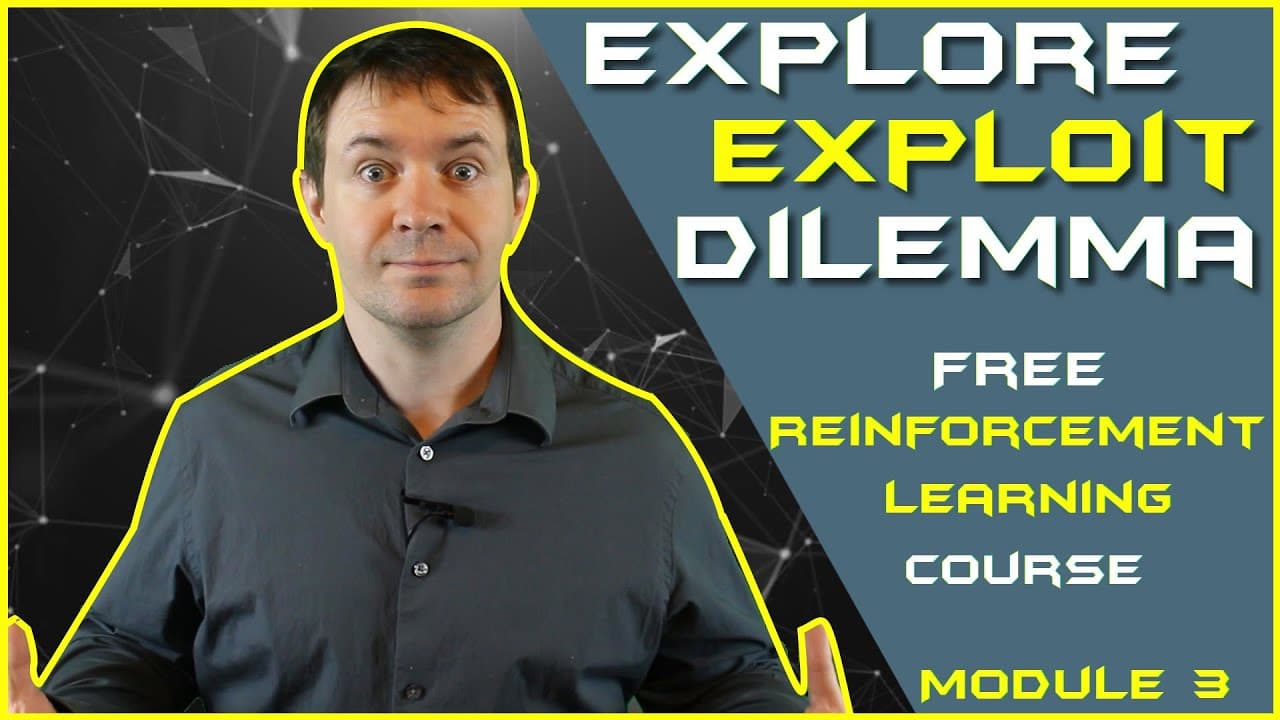
What Is the Explorer Exploit Dilemma in Reinforcement Learning?
TL;DR
The explorer exploit dilemma in reinforcement learning refers to the challenge of balancing immediate rewards against the benefits of exploring new actions for long-term optimization. Solutions include using optimistic initial values to encourage exploration and employing an epsilon greedy strategy, which allows the agent to mostly exploit known best actions while occasionally exploring others.
Transcript
welcome to module three of the free reinforcement learning course from neural net dot AI I'm your host Phil Taber if you're not subscribed make sure to do that now so you don't miss the rest of the course in the previous video we learned about a special type of process called the Markov decision process there each state depends only on the previous... Read More
Key Insights
- ❓ The explorer exploit dilemma is a fundamental challenge in reinforcement learning.
- ❓ Optimistic initial values and the epsilon greedy strategy are solutions to encourage exploration.
- ❓ Agents can leverage two policies for data generation and updating estimate, known as off policy learning.
- ❓ The proportion of exploration vs. exploitation is a hyperparameter that can be adjusted.
- 🤗 The agent's convergence to a purely greedy strategy depends on the problem at hand.
- ❓ The dilemma and its solutions are relevant in various reinforcement learning algorithms.
- 🛀 Off policy learning, such as Q learning, shows efficient results in updating estimate using an epsilon greedy strategy.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is the explorer exploit dilemma in reinforcement learning?
The explorer exploit dilemma refers to the challenge faced by reinforcement learning agents to decide between maximizing immediate rewards or exploring other actions for potential long-term optimization.
Q: How can optimistic initial values help in exploration?
By setting positive or zero initial estimates for all state-action pairs, agents are more likely to explore different actions, as the disappointment from negative rewards encourages exploration.
Q: What is the epsilon greedy strategy?
The epsilon greedy strategy involves spending most of the time exploiting the best-known action and a certain portion of the time exploring randomly. It allows for flexibility by gradually converging to a nearly pure greedy strategy.
Q: How does off policy learning work in reinforcement learning?
Off policy learning involves using one policy to generate actions and another to update the estimate of the action value or value function. In Q learning, for example, an epsilon greedy strategy is used to generate steps and update the estimate of a purely greedy strategy.
Summary & Key Takeaways
-
Reinforcement learning agents aim to maximize total rewards, but they struggle with the explorer exploit dilemma.
-
One solution is to use optimistic initial values to encourage exploration before settling on a purely greedy strategy.
-
Another strategy is the epsilon greedy strategy, where the agent spends most of the time exploiting the best-known action and some portion of the time exploring randomly.
-
Agents can leverage two policies, using one to generate data and the other to update the estimate of the action value or value function.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Machine Learning with Phil 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator