What AI reasoning model performs best: DeepSeek vs Gemini?
TL;DR
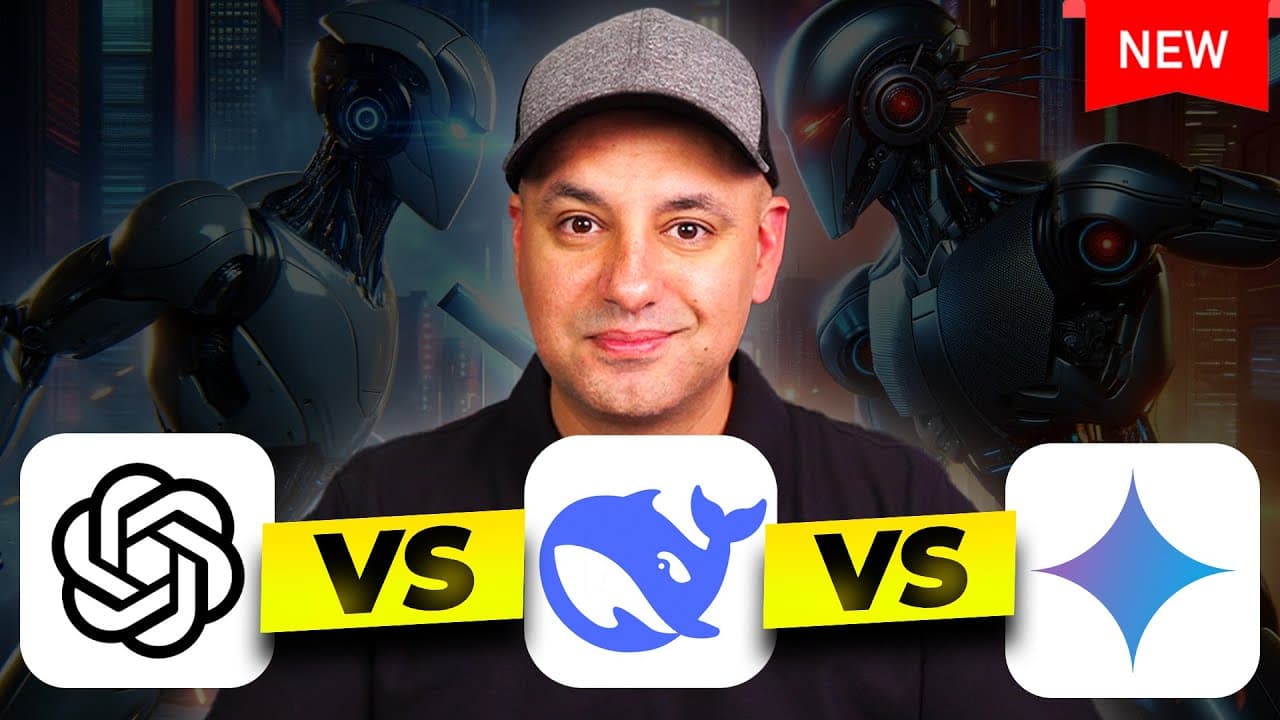
DeepSeek often provides deeper step-by-step reasoning, but Gemini is fastest; overall accuracy varies by prompt. ChatGPT 3.0 mini remains quick but less thorough, while DeepSeek tends to be slower yet more thorough in multi-step problems. The test emphasizes speed versus accuracy trade-offs across tasks.
Transcript
Chad GPT deep seek and Google Gemini all have newer reasoning models that could outperform older models in pretty much every single Benchmark so I wanted to make a very comprehensive video and put them through the ultimate test so we're going to take this across 10 different prompts and this is going to start easy and it's going to get pretty much ... Read More
Key Insights
- Reasoning models break questions into smaller parts before answering.
- DeepSeek tends to produce longer, more detailed reasoning traces.
- Gemini is the fastest model among those tested.
- ChatGPT 03 Mini is generally quicker but less thorough on complex prompts.
- Performance varies significantly by task type and prompt complexity.
- Similar triangle methods were used by some models to solve geometry prompts.
- Speed and accuracy trade-offs are evident across the prompts.
- Evidence shows different models excel in different domains like logic and coding.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: What is a reasoning model and how does it differ from traditional AI models?
A reasoning model differs from traditional AI models by taking time to break down a user’s prompt into smaller parts and by showing a chain of thought that leads to the final answer. This process allows for multi-step problem solving, where the model tests intermediate conclusions and validates them before delivering a final result. The approach often results in slower responses but higher accuracy on complex tasks.
Q: Which model was fastest in handling prompts, and what trade-offs did this speed imply?
Gemini was the fastest in handling prompts, delivering quick results across several tasks. The trade-off for speed was that the model’s reasoning steps were less elaborate compared to DeepSeek in some cases, potentially reducing the transparency of its thought process. In fast responses, users gain speed but may lose some depth of reasoning.
Q: How did DeepSeek perform on multi-step creative problems compared to ChatGPT 03 Mini?
DeepSeek generally performed better on multi-step creative problems, providing longer chains of reasoning that revealed the approach and checks used to reach the solution. In contrast, ChatGPT 03 Mini tended to produce quicker results that sometimes compromised the coherence or validity of the reasoning path, especially for complex, multi-step scenarios.
Q: What was the outcome on the logical deduction paradox prompt among the models?
The models produced varying conclusions on the logical deduction paradox. One model stated the statement was paradoxical and neither true nor false, another claimed the statement above was true, while Gemini asserted a different reasoning path. The discrepancy highlights that logical paradoxes can yield inconsistent outputs across reasoning systems depending on how they interpret self-reference and truth conditions.
Q: How did the models handle the rope-and-building height problem, and what methods were used?
In solving the rope-and-building problem, some models used proportional reasoning and similar triangles to derive the building’s height, demonstrating a structured geometric approach. DeepSeek and Gemini often produced solutions employing similar triangle concepts, while ChatGPT 03 Mini struggled with a clear, valid step-by-step method in this prompt, illustrating differences in problem-solving strategies.
Q: What limitations were observed when modifying a chess game rule in the coding prompt?
When modifying the chess rules so the king moves like the queen, the models could implement the movement correctly and generate a playable sequence for several moves. However, none of the models consistently produced a complete endgame or checkmate logic, indicating limitations in higher-level game state evaluation and endgame reasoning within a single-pass prompt.
Q: What practical takeaway does the video offer about using reasoning models for tasks?
The practical takeaway is that reasoning models can improve accuracy for multi-step tasks but require careful prompt design and task alignment. Users should select models based on whether they prioritize speed or depth of reasoning, and leverage models that expose their reasoning steps when transparency is valuable for validation and learning.
Q: How should prompts be designed when working with reasoning models according to the video?
Prompts should be kept relatively simple to avoid overcomplicating the chain-of-thought process, allowing the model to break the problem into smaller questions naturally. The video suggests avoiding overly long or context-heavy prompts, as simpler prompts tend to yield clearer, more reliable stepwise reasoning from reasoning models.
Summary & Key Takeaways
-
Deep reasoning models break problems into smaller parts and think through steps before answering, which can improve accuracy on complex prompts. The video compares three models across ten prompts, highlighting speed versus depth of thinking. Results vary by task, with no single winner across all categories.
-
The tests show DeepSeek producing longer, more elaborate chains of thought, while Gemini delivers faster, concise reasoning. ChatGPT 3.0 mini sits between in speed and depth. Practical prompts reveal strengths in different domains like math, deduction, and creative problem solving.
-
The overall takeaway is that reasoning models add time to compute but often yield more robust results on multi-step questions. Model choice should align with the user’s priority: speed, depth, or a balanced approach depending on the task.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Skill Leap AI 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator