How to Reduce Claude Code Token Consumption
TL;DR
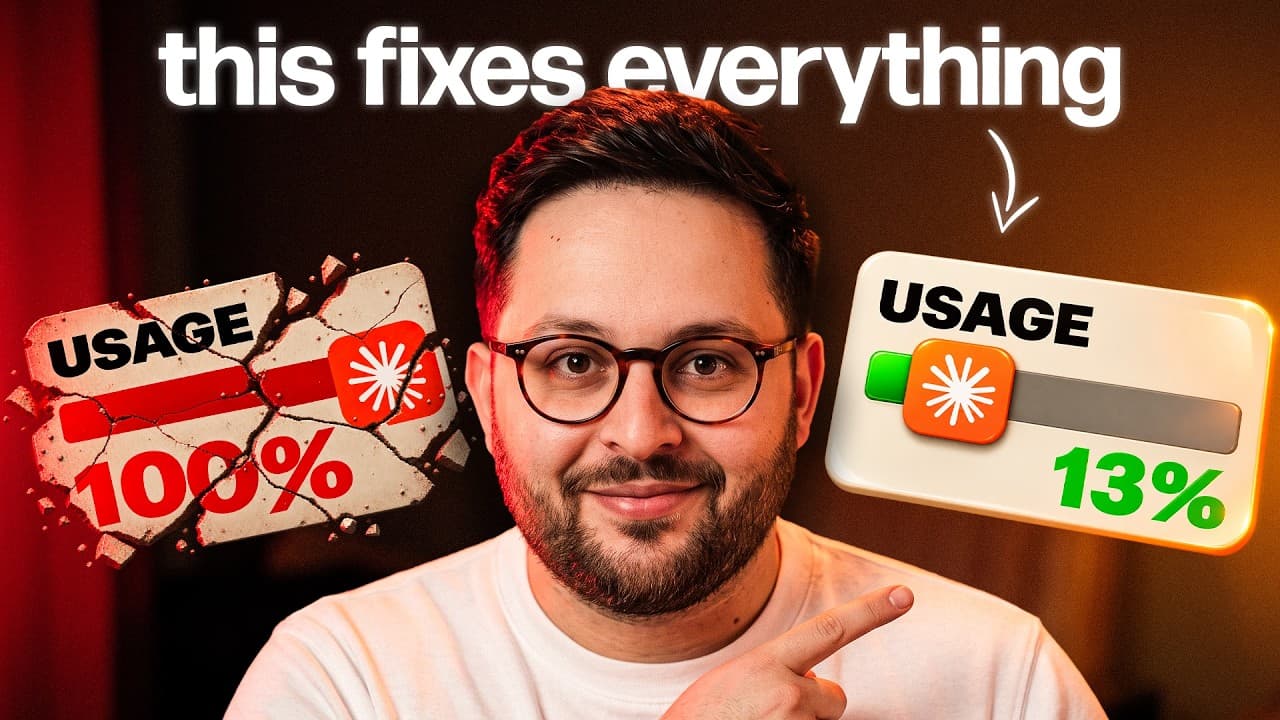
Clear Claude Code whenever you finish one job and begin another, because the accumulated conversation is resent with every new message. Choose the model and effort level before starting, filter large command outputs, disable unused tool connections, and use sub-agents only when their summarized results will prevent bulky details from being carried through many later turns.
Transcript
Claude just told me to come back in 5 hours and I still have a lot of work to do today. I didn't have it do anything massive. I didn't even run it for 8 hours straight. So, I set myself out on a journey to understand why I kept reaching my session limit and how I can stop that from happening ever again. [music] And the crazy part is almost none of ... Read More
Key Insights
- Claude Code context compounds because every new request includes the conversation accumulated so far. A 3,000-token file read on turn four of a 40-turn session can remain in the context and be sent again 37 more times.
- The /clear command is the highest-leverage free reduction because it resets the entire message-history component. In the demonstrated session, messages fell from 80,000 tokens to 0% after clearing, and 96% of spending had come from rereading history.
- The /rename and /resume commands preserve access to previous work without forcing an unrelated new task to carry the old conversation. Renaming before clearing creates a practical recovery path if the earlier session becomes necessary again.
- Model changes can invalidate the conversation cache because the model is part of the cache key. At 200,000 tokens of context on Opus 5, the example says a cached 10-cent turn can become a 1-dollar turn after the history is reprocessed.
- Large tool outputs consume context even when the user never reads them. Filtering hundreds of installation lines before they reach the agent can reduce incoming context from tens of thousands of tokens to hundreds, with the filter continuing to work across later sessions.
- Connected tools add instruction material before the first user message. GitHub is cited as costing 26,000 tokens and Slack 21,000 tokens, while deferred tool loading cuts the manual-loading cost by 85% by opening detailed sections only when needed.
- Sub-agents move token consumption rather than automatically reducing it. In the example, a sub-agent spent roughly 9,800 tokens to keep 5,700 tokens out of the main context, so the trade becomes worthwhile only when that avoided context would be resent across many later turns.
- The right model should be selected before a session begins. Small tasks can use the least capable model that will still complete them, while isolated sub-agent work can use Haiku for a fivefold reduction without changing the main session cache.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: Why does Claude Code run out of tokens during long sessions?
Claude Code runs out of tokens because the model has no persistent memory and receives the accumulated conversation again whenever the user sends another message. Earlier prompts, answers, files, and tool results therefore remain part of later requests. In the creator's audit, personally typed content represented only 0.01% of the usage limit, while rereading message history accounted for 96% of spending.
Q: How does clearing a Claude Code session reduce token usage?
The /clear command removes the accumulated message history from the active context, preventing an unrelated new job from repeatedly carrying everything produced by the previous job. In the demonstration, the messages component dropped from 80,000 tokens to 0%. Because clearing resets the full history base, it can produce a larger reduction than changes affecting only one smaller context component.
Q: How can I preserve a Claude Code session before clearing it?
Use /rename inside the current session before running /clear. The renamed session can later be restored with /resume if its work becomes necessary again. This approach does not throw the earlier work away. It stops the next, unrelated job from carrying and repeatedly resending the old conversation while maintaining a path back to the original session.
Q: Why is switching Claude models mid-session expensive?
Switching models can be expensive because the model is part of the conversation cache key. Once the model changes, the existing cached history no longer matches and may be processed again at full price. The example states that with 200,000 tokens of context on Opus 5, a 10-cent cached turn can become a 1-dollar turn, making the attempted saving ten times more expensive.
Q: What settings can break the Claude Code conversation cache?
The listed cache-breaking changes include switching models, changing effort level, enabling fast mode, connecting or disconnecting an MCP server when tools load up front, enabling a plugin that includes an MCP server, and compacting. Upgrading Claude Code and then resuming a long session is also described as especially expensive. The recommended rule is to select the model and effort level at the beginning and leave them unchanged.
Q: How can large command outputs be prevented from wasting tokens?
Place a filter between Claude Code and commands that return excessive output. Installation commands can produce hundreds of lines containing package names, versions, warnings, and funding messages, even when the user only needs confirmation that installation succeeded. A small filtering file can reduce that output before the agent sees it, cutting incoming context from tens of thousands of tokens to hundreds and continuing to work in future sessions.
Q: How should unused MCP tools be managed in Claude Code?
Open the panel listing connected tools and turn off anything that has not been used in roughly the last month. The connection remains configured, but its contents-page entry stops loading into active sessions. Then run /context and inspect the tools line. If it says deferred, detailed tool manuals stay closed until needed, although the growing contents page still consumes some context.
Q: When do Claude Code sub-agents actually save tokens?
Sub-agents are worthwhile when the source material is high volume, its details will not be needed again, and the main session will continue for many more turns. Their summaries keep bulky material out of the main context, where it would otherwise be resent repeatedly. If the session ends immediately afterward, delegation can waste tokens because the sub-agent loads its own system prompt, memory file, tools, and working material.
Summary & Key Takeaways
-
Claude Code repeatedly sends the accumulated conversation because models have no memory between turns. Consequently, files, answers, command results, and earlier requests can be charged repeatedly throughout a long session. The creator found that rereading message history represented 96% of spending, while personally typed content accounted for only 0.01% of the usage limit.
-
The highest-impact practices are clearing between unrelated jobs, preserving useful sessions with rename and resume, and avoiding model or effort changes during an active conversation. Switching models invalidates the existing cache, causing the full history to be processed again at normal price instead of benefiting from cache reads priced at one tenth of normal output.
-
Additional savings come from filtering verbose command results before they enter context, disabling tools that have not been used recently, and confirming that tool definitions are deferred. Sub-agents help when they summarize high-volume material that will not be needed again and the main session will continue for many turns, but otherwise they can consume more tokens overall.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from Sharbel A. 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator