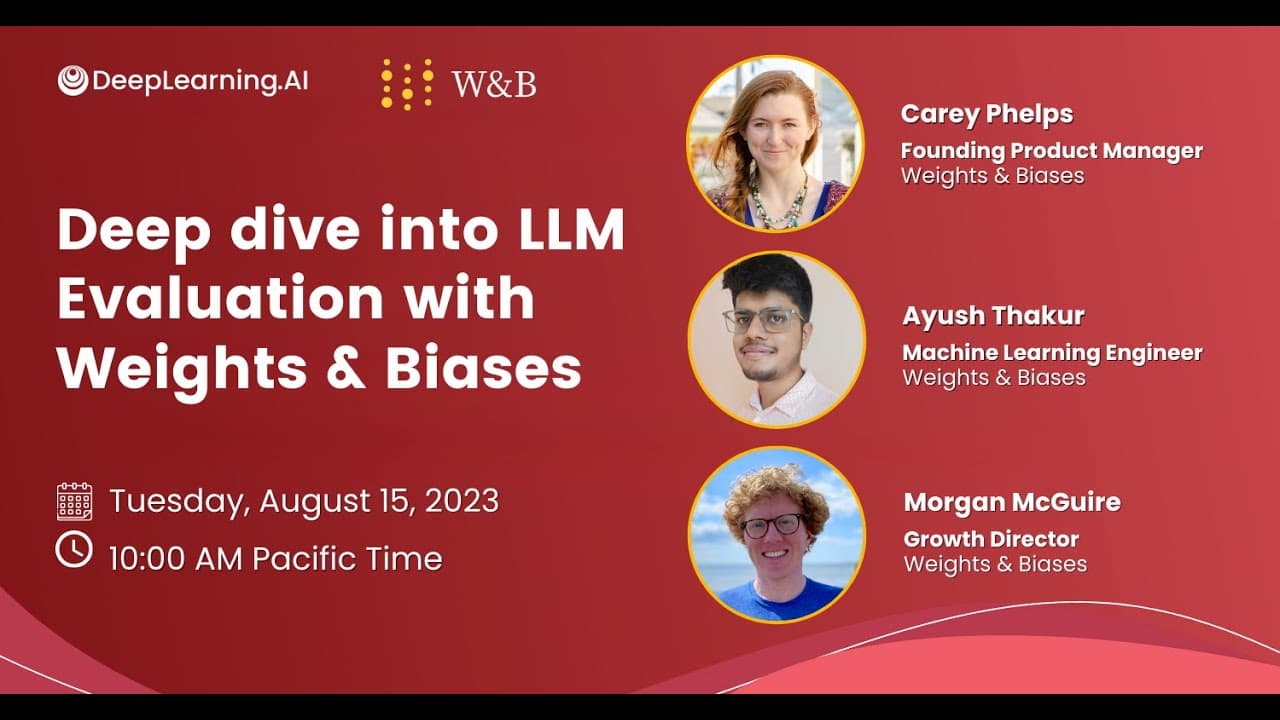
How to Effectively Evaluate Large Language Models
TL;DR
To effectively evaluate large language models (LLMs), use techniques such as eyeballing responses for initial assessment, conducting supervised evaluations with created datasets, and employing self-evaluation where LLMs generate their own evaluation data. Incorporating prompt engineering and using tools like Weights and Biases can enhance accuracy and streamline the evaluation process.
Transcript
foreign hi everyone my name is Diana Chen Morgan and welcome to the next deep learning.ai event I bring together all things AI Community for everyone and today we are very lucky to have a workshop with some special speakers from weights and biases in this Workshop we're going to dive into how we can effectively evaluate llm systems with a particula... Read More
Key Insights
- 📈 Evaluating LLM systems requires careful consideration of the evaluation dataset, metrics, and prompt engineering techniques.
- ❓ Weights and Biases offers a comprehensive platform for experiment tracking, training, and monitoring LLM models.
- 🖐️ Prompt engineering plays a crucial role in effectively evaluating LLM systems by providing specific instructions and context.
- 👻 Self-evaluation using prompts and standard metrics allows LLM models to generate their own evaluation data.
Install to Summarize YouTube Videos and Get Transcripts
Explore YouTube Video Summarizer or Get YouTube Transcript Extractor
Questions & Answers
Q: How can we effectively evaluate LLM systems?
Evaluating LLM systems can be done through techniques like eyeballing, supervised evaluation, and self-evaluation using prompts and standard metrics. It is important to consider the specific use case and carefully design evaluation datasets.
Q: What is the role of prompt engineering in evaluating LLM systems?
Prompt engineering involves providing specific instructions and context to LLM models to achieve desired tasks. It plays a crucial role in effectively evaluating LLM systems by ensuring accurate and meaningful responses.
Q: How can we use self-evaluation to evaluate LLM systems?
LLM systems can be used to generate evaluation data for themselves. This can include generating question-answer pairs, comparing generated answers to ground truth, and using standard metrics to measure performance.
Q: How can the Weights and Biases platform assist in optimizing LLM models?
The Weights and Biases platform provides tools for experiment tracking, model training, and hyperparameter optimization. By integrating with different tools and infrastructures, it simplifies the process of capturing results and finding the ideal balance to maximize accuracy and minimize costs.
Summary & Key Takeaways
-
The workshop focuses on evaluating LLM systems using techniques such as eyeballing, supervised evaluation, and self-evaluation.
-
Weights and Biases offers a platform for experiment tracking, model training, and monitoring LLMs in production.
-
The workshop highlights the importance of prompt engineering and the use of sweeps for hyperparameter optimization.
Read in Other Languages (beta)
Share This Summary 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator
Explore More Summaries from DeepLearningAI 📚
Summarize YouTube Videos and Get Video Transcripts with 1-Click
Try YouTube Summary with ChatGPT & Claude or YouTube Transcript Generator